BrainFrame® Developers
Plug-and-play smart vision platform

What is BrainFrame®?
BrainFrame® is a smart vision platform that is built to be easy to scale, highly configurable, and deployable on-premises or to the cloud.
To open this documentation from BrainFrame, type the IP address of the BrainFrame OS server in a browser to open the BrainFrame Web Client. Once connected, click the Developer button at the bottom left to bring up the Developer References menu, then click BrainFrame® Documentation.
Powered by our highly optimized, automatic model orchestration and algorithm fusion real-time engine, BrainFrame® enables plug-and-play integration of VisionCapsules® from the AI Marketplace using the OpenVisionCapsules format.
This platform turns any connected camera into a smart sensor for sophisticated monitoring and inspection tasks, serving a variety of vertical markets such as security and safety, logistics, industrial automation, and retail.
Getting Started
We recommend our Getting Started guide, which will help you install BrainFrame® and explore its features with the user interface.
If you're interested in developing with BrainFrame®, you'll want to take a look at the REST API Documentation or the Database Description.
Getting Started ↵
Getting Started
Introduction
The BrainFrame ecosystem includes a server for the video processing and a web client to view the live results and configure the server.
The server requires a Linux machine. It is possible to install and run BrainFrame on Linux variants other than Ubuntu. However, the continuous integration of releases is tested only on Ubuntu, and only x86 architectures are available in the general public releases.
Prerequisites: Python and Docker
First, let's install pip, which will be used install brainframe-cli in the
next section:
sudo apt update && sudo apt upgrade
sudo apt install -y python3-pip
pip3 install --upgrade pip
BrainFrame Server requires Docker. Ensure Docker is installed on your system. If it is not, you can install it using the following commands
curl -fsSL https://get.docker.com -o get-docker.sh
sudo sh get-docker.sh
After installation, add your user to the Docker group to manage Docker as a non-root user:
sudo usermod -aG docker $USER
newgrp docker
BrainFrame CLI
For this guide, we will use the brainframe-cli (Command Line Interface) to
download and install BrainFrame. This tool requires Ubuntu.
For Ubuntu 20.04 and 22.04, use pip to install the brainframe-cli:
sudo -H pip3 install --upgrade brainframe-cli
If you are using Ubuntu 24.04 with Python 3.12, virtual environment is required
before the brainframe-cli installation:
sudo apt install -y python3-venv
python3 -m venv my_venv
source my_venv/bin/activate
pip3 install --upgrade brainframe-cli
pip install setuptools
Starting the BrainFrame Server
With the tool installed, now you can use the brainframe command. Check the
version and view available commands by running:
pip show brainframe-cli
brainframe --help
Now, install BrainFrame by running the below command and following the directions:
sudo $(which brainframe) install
Info
The $(which brainframe) command is used if brainframe was installed
without sudo.
If you are in mainland China and downloading the BrainFrame Docker images is taking a long time, consider using a Docker mirror by following these instructions.
Once BrainFrame is downloaded, the BrainFrame CLI will ask you if you want to start BrainFrame server now or not. You can either start BrainFrame server now, or with the following command later:
sudo $(which brainframe) compose up -d
Then to view logs live:
sudo $(which brainframe) compose logs -f
Info
If you said Yes to adding your user to the brainframe group during the
installation, then rebooting your computer will allow you to use
brainframe commands without needing sudo.
Install a specified BrainFrame Release
By default, brainframe install will install the latest version. To update to
a specified BrainFrame release, use the following command:
sudo -E $(which brainframe) update --version v{#.#.#.#}
sudo -E may not be necessary if you install brainframe-cli within a Python
virtual environment - such as the one required on Ubuntu 24.04.
If you are an early access partner, set up the environment variable for your
staging access before running the brainframe update command:
export BRAINFRAME_STAGING_USERNAME={username}
export BRAINFRAME_STAGING_PASSWORD={password}
Then run the brainframe update command:
BRAINFRAME_STAGING=yes sudo -E $(which brainframe) update --version v{#.#.#.#}
BrainFrame Client
Info
A new BrainFrame Web Client beta is available. Access it at
http://<your-server-ip> (replace with your server's address).
You can download and install our client app for Linux from here.
On the first run on Linux, run the installation script. Then, run the client.
bash install.sh
bash brainframe_client.sh
Getting a License
The client will now request a license be uploaded to the server, like such:

To get a license:
- Go to the website.
- Click the
Sign Inbutton located near the top of the page. - Either sign in with your existing account or click
Sign Upto create a new account. - On the Account Page, under the
License Keysection, clickCreate a New Key. Then, clickDownload Keyonce the option appears.

Now on the client, select Configure and then License Config. Drag in the
downloaded license_file into the window, then select Update License. It
should complete looking like this:

Close the license config and the server config windows, and the client will open!

Next Steps
Now with the BrainFrame server and client installed, you can go on to use the ecosystem to your full advantage.
Alternative Methods
You can also accomplish the tasks above using either of the following:
Info
The BrainFrame Client (GUI) and the BrainFrame CLI are completely powered by the REST API. As a result, you can integrate BrainFrame OS directly into your own applications with a custom interface. For more details, view the architecture diagram
Downloads
This page provides downloads for the BrainFrame system (v0.32.0 8b96566e--no-cache, 2026-11-11 22:04:12).
View past public releases.
BrainFrame Server
Instructions for downloading and installing BrainFrame can be found in the Getting Started guide.
BrainFrame Web Client
The BrainFrame Web Client runs in a browser on Linux, Windows, or Mac, and needs no installation. Type the IP address of the BrainFrame OS server in a browser to access it:
http://<your-server-ip>
For more information, see Web Client.
BrainFrame Linux Client
Obsolete
The BrainFrame Linux Client is obsolete. It is kept here for reference only, and is not recommended for new deployments. Use the BrainFrame Web Client instead.
Download BrainFrame Linux Client from here for Ubuntu. The client is also available on the Snap Store:
# To install or update
sudo snap remove brainframe-client && sudo snap install brainframe-client --channel=0.32/stable

# To run
brainframe-client
For more information on running the BrainFrame Linux Client, follow the instructions in the Getting Started guide.
StreamGateway
StreamGateway for Linux (Ubuntu): Download
For more information on running the StreamGateway, follow the guide on setting up a Premises.
Accessing the VisionCapsules® AI Marketplace
Starting from version v0.29.9, BrainFrame includes a reference design for the
VisionCapsules® AI Marketplace. You can access it by
clicking Developer | VisionCapsule AI Marketplace or opening a web browser
and navigating to:
http://<your-server-ip>:9090
Through the AI Marketplace user interface, you can:
- Browse and download capsules
- Load capsules to BrainFrame, enable, or disable capsules
- Adjust capsule options
Alternatively, you can follow our tutorial here for
step-by-step manual installation instructions. Capsules with
a ✨ are recommended as production-ready. The hardware section describes
the devices the capsule can run on: GPU refers to NVIDIA GPUs, iGPU
refers to Intel integrated graphics, and HDDL refers to
MyriadX devices accessed through the OpenVINO HDDL plugin.
| Name | Description | Hardware | Required Input | Output |
|---|---|---|---|---|
| Calculator Object Speed | ✨ Measure pixel-per-second speed on tracked detections, and puts the information in the extra_data field. | CPU | Type: Single Detection Tracked: True |
Type: Single Detection |
| Classification Detections Filter | v0.1 The capsule takes detections from other capsules, filter the detections based on the options setting and present the filtered results. | CPU | Type: List of Detections |
Type: List of Detections Detections: Filter_Confirmed |
| Classifier Age | Determine a persons approximate age by analyzing their face. | CPU GPU |
Type: Single Detection Detections: Face |
ExpandType: Single DetectionClassifies: Age: 0-2 Years Old, 14-24 Years Old, 25-33 Years Old, 3-6 Years Old, 34-37 Years Old, 38-44 Years Old, 45-59 Years Old, 60-100 Years Old, 7-13 Years Old |
| Classifier Behavior Closeup | v3 Determine several behaviors for compliance use cases. | CPU GPU |
Type: Single Detection Detections: Person |
Type: Single Detection Classifies: Behavior: Drinking, Phoning, Smoking, Unknown |
| Classifier Behavior Closeup Openvino | v1.1 Determine several behaviors for compliance use cases. | CPU HDDL iGPU |
Type: Single Detection Detections: Person |
Type: Single Detection Classifies: Behavior: True_Drinking, True_Phoning, True_Smoking, Unknown |
| Classifier Eyewear Closeup | ✨ Determine what type of eyewear a person is wearing. | CPU GPU |
Type: Single Detection Detections: Face |
Type: Single Detection Classifies: Glasses: Glasses, No_Glasses, Sun_Glasses, Unknown |
| Classifier Face Age Gender Openvino | v1.1 OpenVINO face age/gender classifier. | CPU HDDL iGPU |
Type: Single Detection Detections: Face |
ExpandType: Single DetectionClassifies: Age: 12 - 17 Years, 18 - 24 Years, 25 - 34 Years, 35 - 44 Years, 45 - 54 Years, 55 - 64 Years, 65+ Years, Under 12 Years Gender: Feminine, Masculine |
| Classifier Face Emotion Openvino | v1.1 OpenVINO face emotion classifier. | CPU HDDL iGPU |
Type: Single Detection Detections: Face |
Type: Single Detection Classifies: Emotion: Anger, Happy, Neutral, Sad, Surprise |
| Classifier Gender Closeup | ✨ Determine the gender of people based on their faces. | CPU GPU |
Type: Single Detection Detections: Face |
Type: Single Detection Classifies: Gender: Feminine, Masculine, Unknown |
| Classifier Hat Administration | Determine if a person is wearing a hat. | CPU GPU |
Type: Single Detection Detections: Face |
Type: Single Detection Classifies: Hat: Hat, No_Hat, Unknown |
| Classifier Mask Closeup Openvino | v1.1 OpenVINO face mask classifier. | CPU HDDL iGPU |
Type: Single Detection Detections: Face |
Type: Single Detection Classifies: Mask: Not_Wearing_Mask, Wearing_Mask |
| Classifier Person Attributes Openvino | v1.1 OpenVINO powered person classifier, for general person appearance attributes. | CPU HDDL iGPU |
Type: Single Detection Detections: Person |
ExpandType: Single DetectionClassifies: Hat: Has_Hat, No_Hat, Unknown Pants: Has_Long_Pants, Has_Short_Pants, Unknown Coat_Jacket: Has_Coat_Jacket, No_Coat_Jacket, Unknown Bag: Has_Bag, No_Bag, Unknown Gender: Feminine, Masculine, Unknown Hair: Has_Long_Hair, Has_Short_Hair, Unknown Sleeves: Has_Long_Sleeves, Has_Short_Sleeves, Unknown Backpack: Has_Backpack, No_Backpack, Unknown |
| Classifier Pose Closeup | ✨ Roughly identify the current pose of a person. | CPU GPU |
Type: List of Detections Detections: Person |
ExpandType: List of DetectionsClassifies: Pose: Bend/Bow (At The Waist), Crawl, Crouch/Kneel, Fall Down, Get Up, Jump/Leap, Lie/Sleep, Run/Jog, Sit, Stand, Unknown, Walk |
| Classifier Safety Gear Openvino | Roughly identify if person is wearing safety hat and safety vest. | CPU HDDL iGPU |
Type: List of Detections Detections: Person |
ExpandType: List of DetectionsClassifies: Safety_Hat: With_Safety_Hat, Without_Safety_Hat Safety_Vest: With_Safety_Vest, Without_Safety_Vest |
| Classifier Vehicle Color | GPU capable vehicle color classifier. Trained with a private dataset. | CPU GPU |
Type: Single Detection Detections: Vehicle, Bus, Car, Motorcycle, Truck |
Type: Single Detection Classifies: Color: Black, Blue, Brown, Green, Grey, Red, White, Yellow |
| Classifier Vehicle Color Openvino | v1.1 OpenVINO vehicle color classifier. | CPU HDDL iGPU |
Type: Single Detection Detections: Car, Bus, Truck, Van, Vehicle |
ExpandType: Single DetectionClassifies: Vehicle_Type: Bus, Car, Truck, Van Color: Black, Blue, Gray, Green, Red, White, Yellow |
| Claude Classifier Agent | v0.1. The capsule takes detections from other capsules, and send a prompt request to Anthropic API for classification and publish the answers to BrainFrame API or for other capsules to consume and generate fused results. | CPU | Type: List of Detections Detections: Person |
Type: List of Detections Detections: Claude |
| Detector 80 Objects Mo Torch | v1.1 detector_80_objects_mo_torch | CPU HDDL iGPU |
ExpandType: List of DetectionsDetections: Bed, Airplane, Sandwich, Cat, Oven, Snowboard, Fork, Mouse, Bear, Sports Ball, Sheep, Refrigerator, Cell Phone, Parking Meter, Clock, Carrot, Bus, Umbrella, Fire Hydrant, Boat, Keyboard, Elephant, Tv, Zebra, Spoon, Couch, Orange, Teddy Bear, Broccoli, Bowl, Cup, Surfboard, Knife, Train, Toilet, Donut, Backpack, Car, Microwave, Hair Drier, Skateboard, Book, Truck, Suitcase, Remote, Cow, Person, Stop Sign, Wine Glass, Laptop, Tie, Bench, Skis, Dining Table, Toothbrush, Baseball Bat, Bird, Motorcycle, Toaster, Dog, Giraffe, Traffic Light, Chair, Bottle, Pizza, Horse, Cake, Scissors, Tennis Racket, Apple, Banana, Baseball Glove, Potted Plant, Bike, Vase, Frisbee, Sink, Kite, Hot Dog, Handbag |
|
| Detector Barcode | ✨ v0.1 it performs detection and recognition (i.e., decoding the data) and fully supports Code 128, Code 39, GS1-128, and QR Codes. | CPU GPU |
Type: List of Detections Detections: Barcode |
|
| Dtag | ✨ Find DTags including pose information and distance. | CPU | Type: List of Detections Detections: Dtag Encoded: True Tracked: True |
|
| Detector Face Fast | ✨ Efficiently detect faces in most environments. | CPU GPU |
Type: List of Detections Detections: Face |
|
| Detector Face Openvino | ✨ OpenVINO fast face detector. | CPU HDDL iGPU |
Type: List of Detections Detections: Face |
|
| Detector Fire Fast | Classifies if there is fire in the videostream or not. It currently does not localize the fire. | CPU GPU |
Type: List of Detections Detections: Fire |
|
| Detector License Plates | A low-quality license plate detector that can very well detect close-up plates, but has trouble reading them. | CPU GPU |
ExpandType: List of DetectionsDetections: K, N, C, A, H, 6, P, Z, 0, 8, 2, O, 4, S, X, E, M, 9, License_Plate, D, 5, Q, 1, G, L, R, J, 3, I, T, B, F, V, Y, 7, U, W |
|
| Detector Ocr Cn | ✨ v1.2.4 OCR text detector and recognition: support over 6000 Chinese charactors. | CPU | Type: List of Detections Detections: Text |
|
| Detector Person Administration | Detect people in a low-resolution well lit environment where the camera is typically far from the person, and there are 3-10 people, some behind desks. | CPU GPU |
Type: List of Detections Detections: Person |
|
| Detector Person And Vehicle Fast | ✨ v1.1 Find people and vehicles in most environments. | CPU GPU |
ExpandType: List of DetectionsDetections: Vehicle, Bird, Sheep, Car, Motorcycle, Bus, Dog, Giraffe, Truck, Boat, Elephant, Zebra, Cow, Horse, Person, Bike, Cat, Train, Bear |
|
| Detector Person Openvino | ✨ v1.1 OpenVINO generic person detector. | CPU HDDL iGPU |
Type: List of Detections Detections: Person |
|
| Detector Person Overhead Openvino | OpenVINO fast person detector. Works best in surveillance perspectives from a downwards facing point of view. | CPU HDDL iGPU |
Type: List of Detections Detections: Person |
|
| Detector Person Vehicle Bike Openvino | OpenVINO person, vehicle, and bike detector. Optimized for outdoor street crosswalk scenarios. | CPU HDDL iGPU |
Type: List of Detections Detections: Person, Vehicle, Bike |
|
| Detector Safety Gear Openvino | OpenVino's safety gear detector (safety vest and safety hat) | CPU HDDL iGPU |
Type: List of Detections Detections: Safety Vest, Safety Hat |
|
| Detector Text Openvino | ✨ v1.1 OpenVINO text detector and reader. | CPU HDDL iGPU |
Type: List of Detections Detections: Text |
|
| Detector Vehicle License Plate Openvino | OpenVINO license plate detector. Not capable of reading the plate. Vehicle detection is disabled by default, but can be enabled via the capsule options. This capsule is best used in close-up scenarios. | CPU HDDL iGPU |
Type: List of Detections Detections: License_Plate, Vehicle |
|
| Edge Model Router | v0.3 The capsule takes detections from other capsules, and send a prompt request to OpenAI API for classification and publish the answers to BrainFrame API or for other capsules to consume and generate fused results. | CPU | Type: List of Detections Detections: Person |
Type: List of Detections Detections: Router |
| Encoder License Plate Openvino | v1.1 An OpenVINO license plate reader from the OpenVINO model zoo. It is trained on chinese license plates, and works well only when the plate is very close to the camera. | CPU HDDL iGPU |
Type: Single Detection Detections: License_Plate |
Type: Single Detection Encoded: True |
| Encoder Person | ✨ Recognize people based on clothing and general appearance. | CPU GPU |
Type: Single Detection Detections: Person |
Type: Single Detection Encoded: True |
| Encoder Person Openvino | v1.1 OpenVINO powered people encoder. | CPU HDDL iGPU |
Type: Single Detection Detections: Person |
Type: Single Detection Encoded: True |
| Landmarks Face Openvino Simple | v1.1 OpenVINO capable. Outputs simple face landmarks in the detections extra_data | CPU HDDL iGPU |
Type: Single Detection Detections: Face |
Type: Single Detection Detections: Face_Landmarks |
| Recognizer Face | ✨ Recognize faces. Works best close-up. | CPU GPU |
Type: Single Detection Detections: Face |
Type: Single Detection Encoded: True |
| Recognizer Face Landmarks Openvino | v1.1 OpenVINO powered face recognizer. Requires 'Landmarks Face Openvino Simple' capsule to be loaded + any face detector. This capsule aligns faces before feeding them into the encoder, thus allowing higher accuracy recognition. | CPU HDDL iGPU |
Type: Single Detection Detections: Face_Landmarks |
Type: Single Detection Encoded: True |
| Recognizer Handwritten Text Openvino | ✨ v1.1 OpenVINO handwritten simplified chinese text (only one line) recognition. | CPU | Type: List of Detections Detections: Text |
|
| Recognizer Identitycard Face | ✨ v1.1 Recognize and compare identity card face and the other face. Works best close-up. | CPU GPU |
Type: List of Detections Detections: Face |
Type: List of Detections Detections: Face_Compare |
| Tracker Person | ✨ v1.0 Track people using state of the art techniques. | CPU | Type: List of Detections Detections: Person, Car, Motorcycle, Bus, Truck, Vehicle Encoded: True |
Type: List of Detections Tracked: True |
| Tracker Vehicle Iou | ✨ v1.2 Efficient vehicle, person tracker using IOU. | CPU | ExpandType: List of DetectionsDetections: Car, Motorcycle, Bus, Train, Truck, Boat, Vehicle, License_Plate, Bike, Special Vehicle, Person, Book, Tv |
Type: List of Detections Tracked: True |
Python API
A Python wrapper around the REST API is available on PyPI.
pip3 install brainframe-api
The source is available on Github.
For more information on using the Python API, refer to Python API.
Server Hardware
Recommended Hardware
This guide will talk about the recommended hardware for running a BrainFrame Server, and how to install drivers to enable different inference accelerators.
AI Computer/Machine Requirements
Local AI inference requires a network-connected Linux host. Hardware acceleration is optional, but recommended for optimal performance.
How much computing power you need depends entirely on the VisionCapsules (computer vision models) you load. For security use cases, people and vehicle detection and tracking are usually very lightweight. An old laptop or an Intel NUC with an Intel Core or AMD processor can potentially support 8 or more streams and work well for these use cases.
- Operating System: Ubuntu 22.04 LTS or 24.04 LTS
- Processor (CPU): Intel Core i5 / i7 / i9 or Xeon (desktop, laptop, server, or edge/mini PC)
- Hardware Acceleration (Optional): Intel iGPU or discrete NVIDIA GPU
- Memory (RAM): 8 GB minimum (supports up to 8 standard IP camera streams; higher capacity recommended for multi-capsule workloads)
- Storage: 256 GB SSD or higher
- Connectivity: Local network connection (Ethernet recommended for IP/RTSP camera ingestion)
- Audio Output (Optional): 3.5 mm jack, HDMI audio, or built-in speaker (for real-time audible alerts and alarms)
Enabling GPU Acceleration
Most capsules will run significantly faster if an NVIDIA GPU is available to provide hardware acceleration. However, capsules that use OpenVINO are optimized to run well on CPU and won't benefit from the availability of a GPU. We recommend deciding what capsules you'll need before deciding whether a GPU is necessary for you. See all available capsules here.
If you are using a GPU, we recommend an NVIDIA GTX 1060 or better. AMD GPUs are not supported at this time.
Drivers
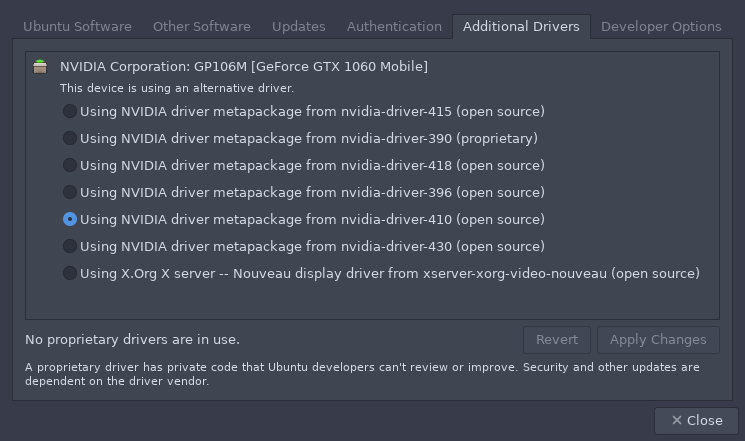
BrainFrame requires that the NVIDIA graphics drivers be installed before the GPU can be utilized. To do this, launch the "Software & Updates", application. Then, on "Additional Drivers" tab, Select "Using NVIDIA driver metapackage" option, and click "Apply Changes". If there are multiple NVIDIA driver metapackages available, prefer the most recent one.
Docker Passthrough
If you have an Nvidia GPU, you can enable hardware acceleration by installing Nvidia Docker 2. Please refer to the installation guide.
Then, make the Nvidia Container Runtime the default runtime for Docker by
editing /etc/docker/daemon.json to have the following configuration:
{
    "runtimes": {
        "nvidia": {
            "path": "/usr/bin/nvidia-container-runtime",
            "runtimeArgs": []
        }
    },
    "default-runtime": "nvidia"
}
You can probe hardware inference acceleration devices using BrainFrame CLI devices command.
Camera Compatibility
BrainFrame supports IP cameras and USB cameras, and can load video files or images directly. This page focuses on IP cameras, or IP-connected cameras.
For developers, the onvif tools in Dev Tools are handy for discovering, scanning, and validating IP cameras on your network. You can then use REST API Apps to add the cameras to BrainFrame in a batch with a script.
In general, any IP camera that is compatible with RTSP is supported. Below are some of the IP cameras we tested as examples:
| Brand | Model | Talkdown.ai Validated Deterrence Features |
|---|---|---|
| Tyco Security Products | Illustra Pro 2MP Minidome indoor Camera | |
| Illustra Pro 2MP Minidome outdoor Camera | ||
| HIKVISION | IP turret dome camera DS-2CD2342WD-I | |
| Bullet Camera DS-2CD7A87EWD-IZS | ||
| HNC | ONVIF Strobe Light Turret HNC354G2-XDAU/SL | |
| HNC324-TD 4MP True WDR Fixed Mini Dome Camera | ||
| Dahua | Bullet Camera N45EF63 | External Speaker supported |
| Fisheye Camera N55BT5 | ||
| QSee | Bullet IP Camera | |
| Uniview | MultiView Dual-light Network PTZ Camera IPC9312LFW-AF28-2X4 | Built-in Speaker, Lighting, PTZ |
| Dual-light Turret Network Camera IPC3634SS-ADF28KMC-I1 | Built-in Speaker, Lighting | |
| Tri-Guard Fixed Dual-light Bullet Network Camera IPC2B15SS-ADF28KMC-I1 | Built-in Speaker, Lighting | |
| Vehicle License Plate Recognition Bullet IP Camera PKC2640@Z80-P | ||
| Vehicle License Plate Capture Camera ITC237-PU1B-IR | ||
| IPS302030-S IP Speaker | Speaker |
For Talkdown.ai Deterrence, choose cameras that provide the features you need: a speaker, lighting, and PTZ (pan, tilt, and zoom) for deterrence. In the table above, look for the models with Speaker, Lighting, or PTZ in the Talkdown.ai Validated Deterrence Features column, for example the camera with built-in Speaker, Lighting, and PTZ. A camera with an external Speaker needs a speaker connected to it, and a separate IP speaker such as the IPS302030-S can also be used.
For example, a home setup for deterrence can use:
- Driveway: Dual-light Turret Network Camera IPC3634SS-ADF28KMC-I1, for Voice and Lighting deterrence.
- Front door: MultiView Dual-light Network PTZ Camera IPC9312LFW-AF28-2X4, for Voice, Lighting, and PTZ deterrence.
- Siren: IPS302030-S IP Speaker, for very loud siren deterrence with human confirmation.
Networking
Plan your network before you deploy BrainFrame. Cameras, the BrainFrame server, and the devices people use to view it all need to reach each other.
Camera and NVR (Network Video Recorder) IP addresses
IP cameras are usually configured with static IP addresses, for example 192.168.x.x or 10.x.x.x, instead of DHCP. Once the network is set up, a static address does not change, so the system keeps working if cameras are not assigned a new address after a power loss.
Small networks may use DHCP. In that case, reserve a range of addresses for static IPs, for example 192.168.x.0 to 192.168.x.100, and assign the device addresses from that range.
BrainFrame Server on the same network as the cameras
The BrainFrame server pulls video from the cameras, so it needs to be on the same network as the cameras. We recommend a static IP address for the BrainFrame server as well, so that its address does not change.
To analyze cameras on other private networks, see Premises.
Access BrainFrame from phones and computers
Users should be able to reach the BrainFrame server's IP address from their phones and computers. From there they can:
- Check live videos and event records.
- Configure the system.
- Use Security Operation Center (SOC) functions, for example hearing voice alerts when something happens around the building.
See Web Client for how to open BrainFrame from a browser.
BrainFrame access to the internet
The BrainFrame server needs access to the internet to send email alerts to users when an event happens.
Local deployment
When BrainFrame OS is deployed locally, everything stays on the server. The only traffic to the internet is the periodic validation of the license.
There is also an offline deployment option. In this mode the BrainFrame license is bound to the machine fingerprint, and there is no traffic to the internet at all.
Talkdown.ai
The Talkdown.ai application, built on top of BrainFrame OS, sends emails with camera snapshots to the users you configure.
Managed security service
If you purchase a managed security service, additional software may be installed on the AI server, for example:
- Remote access: MeshCentral, for remote configuration and maintenance.
- Backup: the system configuration may be backed up to the cloud, so that the system can be restored.
- Incident investigation: your security patrol provider may access your video footage and pictures to investigate incidents, and share them with the police for criminal reports.
For the Intellectual Property, Data Privacy, and Data Communication policies, see Privacy & Terms on the homepage.
Other devices
A typical deployment also uses these network devices:
- Routers: configure DHCP and static IP addresses for all devices.
- PoE switches: connect the cameras and provide power to PoE-enabled cameras.
- Remote A/C power switch: manage the power of the devices, for example to restart a machine remotely for maintenance.
The diagram below shows a typical network topology.
Ended: Getting Started
User Guide ↵
Streams
Introduction
BrainFrame runs analysis primarily on video streams. Streams can come from many sources, like an IP camera, webcam, or video file. BrainFrame supports all major video formats and is expected to support any IP camera that provides an RTSP, HTTP, or MJPEG stream.
Talkdown.ai, the AI video security app built on BrainFrame OS, works with the same streams: any IP camera that provides an RTSP stream works with Talkdown.ai.
See Camera Compatibility for examples of compatible IP cameras.
This tutorial assumes that the server, client, and any IP cameras are on the same local network. BrainFrame supports analyzing streams on other private networks using our 'Premises' stream proxying system.
Adding a Stream
Click the floating action button at the bottom right of the window to add a stream.

The Add Stream dialog will appear. BrainFrame supports three types of video streams: File, webcam, and IP camera. For this example, we will use a video file.

Once a stream is added, you will see a video thumbnail of the stream, live, on the top left. As you add streams, they will fill this screen in a grid. If you add more video streams, the view will look something like this.

If you use the BrainFrame Web Client, you can adjust the information and performance of how videos and detections render on the web page in the Settings menu
- Detections
- Show detections
- Use polygons when available | Always use bounding boxes
- Show labels
- Show attributes (e.g. gender/behavior for a person detection)
- Show tracking
- Show extra data: Check this option to show extra information about the detections, such as classification results.
- Show regions
- Show lines
- Streams:
- Media Mode:
- Thumbnail View: JPEG | HLS, default: JPEG
- Show detections in thumbnail view: Off
- Player View: JPEG | HLS | MJPEG, default: MJPEG
- Task Config View: JPEG | HLS | MJPEG, default: MJPEG
* JPEG Static Picture Mode * HLS Async Video Mode (HTTP Live Streaming) * MJPEG Sync Video Mode (Motion JPEG Live Picture Streaming)- MJPEG Max FPS: 1 - 25, default: 5
- HLS Port (0: the same as the page): 9888
- Advanced
- Theme: Dark | Light
Stream Types
Different stream types take different parameters. The following is a quick introduction to what each parameter means.
Files
As seen in the above example, file streams simply take a file path. Most common video file types are supported by BrainFrame. When the source video ends, BrainFrame will automatically loop it back to the beginning.
Webcams
Webcam streams take a webcam device ID as their only parameter. Webcam device IDs start at zero and increment for each webcam that is connected. For a computer with a single connected webcam, the ID will generally be "0".
IP Cameras
IP camera streams take a URL as their main parameter. This URL should point to an RTSP, HTTP, or HTTPS video stream. BrainFrame supports many video encoding formats, including H264, VP8/9, and MJPEG.
For more information on how to get an RTSP URL for your IP camera, take a look at Connecting to IP Cameras.
Zones
Introduction
BrainFrame allows you to specify areas of interest within a video stream and gain specific insights about that area. These come in two forms, regions and lines, which are collectively referred to as "zones". Region zones are often used for counting objects inside of a region. Line zones are for counting objects that have crossed the line.
Creating a Zone
To create a zone, start by clicking on the video stream that you want to add the zone to in the grid view, then click the "Task Config" button in the bottom-right.

You will see the Task Configuration window. This window allows us to create zones and add alarms to these zones, which will be discussed in the next section. For now, click on the "Region" or "Line" button to start creating a zone of that type.

To specify where a region is located, click to create the region's vertices one-by-one. When the region is complete, click the "Confirm" button. For lines, click to specify where the line starts, then click again to specify where it ends.

Now that we know how to create zones in a stream, we will discuss how to get information from these zones with alarms.
Alarms
Introduction
Alarms allow BrainFrame to notify you when a specified condition happens within a zone. Alarms generate alerts when their condition is met. Alerts are made available through the REST API, and a stream with an active alert is brought to the top of the grid view in the client.
All alarms have an "Active Time", a period during the day where the alarm is allowed to trigger. This can be useful if, for example, you want to be notified if a person is in an area after business hours.
Alarm Conditions
There are two main types of alarm conditions: count-based conditions, and rate-based conditions.
Count-Based Conditions
Count-based conditions are triggered based on the number of objects in a zone. The condition may trigger if the number of a certain object class is greater than, less than, equal to, or not equal to a given value. The condition may also specify an attribute value to filter objects by.
The following are examples of count-based conditions:
- If less than 3 people in uniform are in region "Entrance", raise an alarm
- If there is not 1 person in region "Cash Register", raise an alarm
- If there is greater than 0 cars in region "Restricted Parking", raise an alarm
Rate-Based Conditions
Rate-based conditions are triggered based on a change in the number of objects in a zone over time.
The following are examples of rate-based conditions:
- If greater than 10 people enter region "Main Entrance" within 5 seconds, raise an alarm
- If fewer than 1 car exits region "Parking Lot" within 120 seconds, raise an alarm
Creating an Alarm
To create an alarm, open the Task Configuration window for the stream of interest and under the "Add New" section, click the "Alarm" button.

This will bring up the "Alarm Configuration" window. Here you may choose which condition type to use and specify each parameter. The "Condition Type" section is meant to be read like a sentence.
Info
If you don't see any class names available in the second drop-down, make sure that you have at least one plugin loaded that is able to detect objects.

When an alarm is triggered, the alert will appear in that stream's alert log and the stream will be moved to the "Streams with ongoing alerts" section.

Intersection Points
By default, a detection is said to be inside a zone if the bottom center point of the detection is in the zone. This bottom center point is referred to as the detection's "intersection point". This default works well for most overhead camera angles, but can be changed to the top, left, right, or center of the detection by changing the "Intersection Point" drop-down in the alarm configuration dialog.
Identities
Introduction
An identity is a unique instance of a certain class of object. Identities allow BrainFrame to recognise a pre-defined specific person in a group of people, or a specific car in a parking lot. To use this feature, the user must upload one or more images or precomputed vectors of that unique instance. BrainFrame will pick out differentiating features in that instance for later use during recognition.
Identities can span multiple classes of object. For example, a person identity might be described by the person's face and by their gait.
Identities are added to BrainFrame in bulk using a specially organized directory. This directory includes child directories for each identity the user wants to add to BrainFrame. These child directories are in the format "unique_id (nickname)", where the unique ID is a differentiating string, and the nickname is a friendly name to display the identity as. These child directories contain one or more other directories that contain images or precomputed vectors of the identifiable object. The name of the directory defines the class of what is in the image, so if the identity is for a person and we have pictures of their face, the directory would be called "face".
An image should be of only a single instance of the class it is being encoded for. Most common image formats are supported, like JPEG and PNG.
Precomputed vectors are arrays of floating point values in a JSON file. These are used when the encoded vector of a class is already known. For example, DTags have their vector value printed on the tag so they can be registered through this method. For most class types, images are preferred.
An example of this format is shown below. In this example, we are creating three identities with pictures of their faces:
$ tree brainframe-identities/
brainframe-identities/
├── employee000000 (John Cena)
│   └── face
│       ├── 0001_01.jpg
│       ├── 0002_01.jpg
│       └── 0003_01.jpg
├── employee000001 (Bob Suruncle)
│   └── face
│       ├── 0001_01.jpg
│       ├── 0002_01.jpg
│       ├── 0003_01.jpg
│       ├── 0004_01.jpg
│       ├── 0005_01.jpg
│       └── 0006_01.jpg
└── employee000002 (Stacy Sgotigoenon)
    └── face
        ├── 0001_01.jpg
        ├── 0002_01.jpg
        ├── 0003_01.jpg
        ├── 0004_01.jpg
        ├── 0005_01.jpg
        ├── 0006_01.jpg
        └── 0007_02.jpg
Once you have this directory structure created, you're ready to add it using the UI.
Adding Identities
To add new identities, start by clicking the "Identity Configuration" button in the toolbar.

The "Identity Configuration" window displays what identities are currently uploaded. On the right is a grid view of all the identities in the database. On the left is a list of encoding classes that are available through currently loading plugins as well as those of any encoding currently in the database. Clicking on the encoding class will filter the grid of identities to show only those encoded with that class. There is also a search tool at the top left that can be used to search by unique names or nicknames of identities.
To add more identities, click the floating action button at the bottom right of the window.

Clicking the Add Identities button will bring up a directory selection dialog. Use the folder button to select the path to the identities directory. If desired, you can also type the path manually in the text box.
Wait for the identities to finish uploading using the progress bar that appears at the bottom as an indicator.
If there is an error with the directory structure, a dialog will pop up with the error. If any errors occurred for any of an identity's encodings, they will be displayed in a separate window as a tree view.

Uploading the same directory twice will not result in duplicates, so it is safe to make any necessary modifications to the data and upload the entire directory again.
Once the identities are uploaded, you will see them in the Identity Configuration window.

Premises
Introduction
For most deployment configurations, IP cameras will be hosted on a local network that is protected behind a firewall. If the BrainFrame server is not running in this local network, it will not be able to directly access the IP cameras. To enable this kind of configuration, BrainFrame provides tools to proxy video streams from local networks to a remote BrainFrame server, through the concept of a premises.
A premises is a local network with one or more IP cameras. In order for a remote BrainFrame server to have access to IP cameras on a premises, a StreamGateway must be running on that premises. The StreamGateway will take care of proxying local IP camera streams to BrainFrame as needed.

Prerequisites
The StreamGateway communicates with a stream proxy server that runs alongside the BrainFrame server. To allow the StreamGateway to communicate with this server, the StreamGateway server port (8004) must be forwarded. See the Server Configuration page for information on how to customize this port.
Setting Up a StreamGateway
The StreamGateway executable is included in your distribution of BrainFrame. Transfer the executable to a dedicated machine on the same local network as the IP cameras.
Before starting the StreamGateway, we need to create a new premises with the
new command. For additional options, run ./StreamGateway new -h.
./StreamGateway new --premises-name "The Emerald City" --hostname <BrainFrame IP Address>
The new command creates a new premises and saves the provided information to
a configuration file named gateway_config.json.
To start the StreamGateway, use the start command.
./StreamGateway start
Using Premises
Now that we've created a premises and started a StreamGateway, we can connect to IP cameras on that premises. In the Add Stream dialog, select the new premises from the "Premises" drop-down and provide an IP camera URL as if it were being connected to directly (which usually means a local IP address should be used).

Deleting a Premises
When a premises is no longer needed, it can be deleted using the StreamGateway
delete command.
./StreamGateway delete
Capsule Options
Introduction
Capsule Options allow users to customize behaviors of the capsule, for example, using a threshold to filter out less confident detections from an algorithm. Capsules can define their own options, and hence different capsules will have different configurable options.
Once a capsule is loaded, its options will be set to the default value, and those values will apply to all streams. This tutorial will demonstrate how to set the global capsule options, and override global capsule options for specified streams.
Global Capsule Options
Global capsule options are applied to all video streams, except those which have overridden the option for a specific stream. In this example, we have two video streams and two capsules loaded.

To set the global capsule options, click Capsules icon on the left-bottom of
the client, you will see the loaded capsules and their options.

You can see that there are two options for Detector Face Fast. One is to
enable this capsule or not, the other one is the threshold.
You can change the capsule options value by clicking the checkbox or editing
the text box, depending on the type of the option. You can always click the
Reset to Defaults button on the right corner to discard your changes and
restore the default values.
Let's disable this capsule by unchecking the checkbox after Capsule Enabled,
then click the Apply button.
Now if you go back to the video streams, you will see Detector Face Fast has
been disabled for all videos.

Override Global Capsule Option
You can set unique capsule options for the specified video stream and leave
the other videos stream using the global capsule option. For instance, we
want to enable Detector Face Fast for the first video stream and leave it
disabled for the second one. Click the first video, then on the video view,
click Stream Capsule Config button on the right-bottom.
In the Stream Capsule Options view, check Override Global checkbox for
Capsule Enabled Option, then check the check box in the Value column.
Finally, click Apply to make it effective.

Now let's go back to the video view, you will face detection for the first video, but not for the second one.

Object Counting
Introduction
BrainFrame allows you to analyze the traffic conditions by counting objects in specified zones. You will be able to see the data from the BrainFrame client, or through the REST API. In BrainFrame, there are two metrics to measure the traffic history:
total_entered: The total number of objects that have entered the zonetotal_exited: The total number of objects that have exited the zone
This is a core feature of BrainFrame and is enabled by default. However, you will need to match certain capsule requirements in order to utilize this feature. As the implementation is different, the requirements vary for different types of zones, e.g. regions and lines. For more information about zones, please refer to the documentation.
Regions
In BrainFrame, regions are represented as polygons (more than two coordinates).
For a region, total_exited represents the total number of objects that have
moved from the inside of the region to the outside, total_entered is the
inverse.
You will need an object detector to enable BrainFrame to analyze the traffic.
We supply two starter capsules Detector Person And Vehicle Fast and
Detector Person Vehicle Bike Openvino that can satisfy this requirement. As
regions are primarily used to analyze enclosed objects, the client only
displays the counts of objects that are currently contained within regions.

However, you can retrieve the entire, unabridged counts using
get_latest_zone_statuses() or get_zone_status_stream() or the corresponding
REST API. You will get a ZoneStatus object:
{
  "2": {
    "Store": {
      "zone": {...},
      "tstamp": 1601450507.8037934,
      "total_entered": {
        "person": 146
      },
      "total_exited": {
        "person": 148
      },
      "within": [],
      "entering": [],
      "exiting": [],
      "alerts": []
    }
  },
  "Screen": {...},
}
In the above example, 146 people have entered the "Store" region, and 148 have exited. (Note: in order to make the example clearer, some fields were removed for succinctness)
Lines
In BrainFrame, lines are a type of zone that only have two coordinates.
Similar to regions, total_entered and total_exited represent the number of
objects that have moved across the line. You will be able to see the traffic
data in the BrainFrame client. For each line, there will be an arrow indicating
the "entering" direction of the line.

Similar to regions, you can also get the data through the REST API:
{
  "2": {
    "Street": {
      "zone": {...},
      "tstamp": 1601456309.9824505,
      "total_entered": {
        "person": 20,
      },
      "total_exited": {
        "person": 15,
      },
      "within": [],
      "entering": [],
      "exiting": [],
      "alerts": []
    }
  },
  "Screen": {...},
}
In the example above, 20 people have entered the line named "Street", and 15 people have exited.
As it is difficult to determine the direction of movements using only object
detectors, you will also need an object tracker to enable BrainFrame to analyze
the trajectory of objects. Some object tracker capsules track encoded detections
and will depend on an additional encoding capsule. For example, TrackerPerson
will need Encoder Person to work together. On the other hand,
Tracker Vehicle doesn't need one as it tracks vehicles using an IOU-based
algorithm.
An encoder capsule's name usually starts with Encoder, you can distinguish an
encoder by its output type on our download page. If a
capsule states Encoded: True in its Output field, it's an encoder. Here are
some encoders available on our website:
Encoder PersonEncoder Person Openvino
Similarly, a tracker capsule's name usually starts with Tracker, and states
Tracked: True in its Output field. In addition, if it states Encoded: True
in the Required Input field, that means this capsule needs a corresponding
object encoder to work. Here are some trackers available on our website:
Tracker PersonTracker Vehicle
You can use the following capsules combinations as an example:
Detector Person And Vehicle FastEncoder PersonTracker Person
Or:
Detector Person Vehicle Bike OpenvinoTracker Vehicle
Server Administration ↵
Server Configuration
Introduction
The BrainFrame server uses a docker-compose.yml file to configure
many aspects of its runtime behavior. Some options may be changed by
setting environment variables in a .env file, placed in the same
directory as the docker-compose.yml file.
ls -la "$(brainframe info install_path)/.env"
cat "$(brainframe info install_path)/.env"
Any options not exposed here may be overridden by creating a
docker-compose.override.yml file in the same directory. Configuration
written here will be applied over the original docker-compose.yml.
Port Configuration
BrainFrame makes three ports available to the host environment by
default, the API and documentation on port 80, the Postgres database on
port 5432, and the StreamGateway server on port 8004. If these ports
conflict with other software running on the host machine, they can be
changed by setting the SERVER_PORT, DATABASE_PORT,
STREAM_GATEWAY_PORT, and RABBITMQ_PORT variables in the .env file.
BrainFrame may also proxy video streams to ports in the range 10000-20000. At this time, there is no way to reconfigure these ports.
SERVER_PORT=80
DATABASE_PORT=5432
STREAM_GATEWAY_PORT=8004
RABBITMQ_PORT=5672
Authorization Configuration
By default, BrainFrame does not authorize clients and all clients have admin
permissions. If your server is being deployed in a network where access control
is desirable, authorization can be turned on using the AUTHORIZE_CLIENTS
variable in the .env file.
AUTHORIZE_CLIENTS=true
Warning
The admin user is given a default password of "admin". This should be changed to a secure and unique password for public deployments.
Currently, the admin user's password may only be changed through the REST API.
The following is an example curl command for doing this. Replace [hostname]
with the hostname of the BrainFrame server and [new password] with the desired
password.
curl 'http://[hostname]/api/users' \
    --user 'admin:admin' \
    --request POST \
    --header 'Content-Type: application/json' \
    --data '{
              "id": 1,
              "username": "admin",
              "password": "[new password]",
              "role": "admin"
            }'
User Configuration
BrainFrame is designed to run using the account of the current non-root user. By
default, 1000 is used for both the user ID and group ID, which matches the
default on most Linux systems. These IDs may be adjusted using the UID and
GID variables in the .env file.
UID=1001
GID=1001
To check the IDs of the currently logged in user, run id -u for the UID and
id -g for the GID.
Journal Pruning
BrainFrame records analytics results to a Postgres database. Over a long period of time, this can result in a lot of data. To avoid unbounded storage use, BrainFrame prunes journal entries over time and deletes journal entries that are past a certain age.
Journal pruning behavior is controlled by the "pruning age" and "pruning
fraction" variables. The pruning age controls how old a journal entry
must be before it becomes a candidate for pruning. This value also
controls at what interval pruning is run. The pruning fraction variable
controls what portion of journal entries are pruned each time pruning is
run. The pruning fraction variable is a value between 0 and 1, where 0
results in no pruning, and 1 results in the deletion of all journaling
information past the pruning age. These variables may be configured by
setting the PRUNING_AGE (specified as a duration)
and PRUNING_FRACTION variables in the .env file.
# Start pruning journal entries after 1 hour, and run pruning every hour
PRUNING_AGE=0d1h0m
# Prune 5% of all journal entries that are past the pruning age every run
PRUNING_FRACTION=0.05
All journaling information is deleted after it reaches the journal max
age. This value may be configured by setting the JOURNAL_MAX_AGE
variable (specified as a duration) in the .env
file.
# Keep journaling information for 60 days
JOURNAL_MAX_AGE=60d0h0m
Duration Format
Settings that specify a duration are in the format XdYhZm, where X is
the number of days, Y is the number of hours, and Z is the number of
minutes.
AI Accelerator Configuration
At the moment the only control over AI accelerator is for OpenVINO devices.
It is possible to change the whitelisted devices and their priority with the
OPENVINO_DEVICE_PRIORITY.
# Block any device except for CPU
OPENVINO_DEVICE_PRIORITY=CPU

# Load onto both CPU and HDDL, giving priority to CPU
OPENVINO_DEVICE_PRIORITY=CPU,HDDL

# Load onto both CPU and HDDL, giving priority to HDDL
OPENVINO_DEVICE_PRIORITY=HDDL,CPU
For example, to use a CPU-only setup on an Intel Xeon-based machine without a GPU:
echo "OPENVINO_DEVICE_PRIORITY=CPU" | sudo tee -a "$(brainframe info install_path)/.env" > /dev/null
You can probe hardware inference acceleration devices using BrainFrame CLI devices command.
Deploying a Public Server
Before making a BrainFrame server publicly accessible, some additional configuration is required.
Authorization
By default, BrainFrame does not authorize clients. Authorization should always be turned on for public deployments to prevent unauthorized access. See this section on authorization configuration for more information.
Warning
Be sure that the admin user's default password has been changed before continuing.
Port Forwarding
BrainFrame requires that certain ports are forwarded so that the client and other external programs may establish connections to it. Below is a table of ports BrainFrame uses and their purpose. For ways to reconfigure these ports, see this section on port configuration.
| Port | Purpose |
|---|---|
| 80 | BrainFrame API, dashboard, documentation |
| 8004 | StreamGateway server communication |
| 5533 | RTSP streams for video files |
| 10000-10100 | StreamGateway server video streams |
Warning
BrainFrame also makes a Postgres server available on port 5432, but that port should not be forwarded for security reasons.
Using USTC Docker Mirror
Introduction
If you are located in mainland China, you might have a hard time pulling docker images, however, you can speed things up by using the Docker Mirror hosted by USTC.
Configure Docker Daemon
You can configure the Docker daemon using a JSON file. Usually it's located at
/etc/docker/daemon.json; if it doesn't exist create a new one. Then, add
"https://docker.mirrors.ustc.edu.cn/" to the registry-mirrors array to pull
from the USTC registry mirror by default.
After editing, your /etc/docker/daemon.json should look like this:
{
    "registry-mirrors": ["https://docker.mirrors.ustc.edu.cn/"]
}
If this is not the first time you are editing the daemon.json, there may be
other configuration already there. You can simply add the line above after any
existing configuration.
Then restart dockerd:
sudo systemctl restart docker
Verify Default Registry Mirror
You can verify your changes by:
docker info
If you see the following lines, you have configured your Docker daemon successfully.
Registry Mirrors:
    https://docker.mirrors.ustc.edu.cn/
Offline Deployment
Some customers may prefer to deploy BrainFrame on a machine that does not have internet access. This document describes how that may be accomplished, assuming that a separate machine with internet access is available.
Save Docker Images
Start by deploying BrainFrame on a separate development machine using the instructions found on the Getting Started page.
When BrainFrame is running, open another terminal, and you will see the list of containers we are running for deployment:
docker ps
The list of of containers should look like this:
CONTAINER ID        IMAGE                                            COMMAND                  CREATED             STATUS                     PORTS               NAMES
c462fa89dc72        aotuai/brainframe_core:0.25.2                    "./brainframe_server…"   4 hours ago         Exited (0) 3 hours ago                         release_api_1
54b731bc2a04        aotuai/brainframe_http_proxy:0.25.2              "nginx -g 'daemon of…"   4 hours ago         Exited (0) 3 hours ago                         release_proxy_1
d6ad0f9e0675        aotuai/brainframe_docs:0.25.2                "nginx -g 'daemon of…"   4 hours ago         Exited (0) 3 hours ago                         release_docs_1
4894246049a0        postgres:9.6.17-alpine                        "/entrypoint.sh mysq…"   4 hours ago         Exited (0) 3 hours ago                         release_database_1
ac564e32f7eb        aotuai/brainframe_dashboard:0.25.2           "/run.sh"                4 hours ago         Exited (0) 3 hours ago                         release_dashboard_1
The above containers are the ones we need to save, ignore the other containers just in case you have your own containers running at the same time.
The next step is to save those images, you can do this by running the
docker save command:
docker save IMAGE [IMAGE...] -o OUTPUT
For example, in this case, you should run:
docker save \
    aotuai/brainframe_core:0.25.2 \
    aotuai/brainframe_http_proxy:0.25.2 \
    aotuai/brainframe_docs:0.25.2 \
    postgres:9.6.17-alpine \
    aotuai/brainframe_dashboard:0.25.2 \
    -o brainframe
Now all the images we need are save in BrainFrame under the current directory.
Load Docker Images
Once you have the packaged Docker images, copy it to the offline machine, and load it:
docker load -i brainframe
Ended: Server Administration
Tuning & Advanced Setup ↵
Custom Pipelines
IP Camera streams can be configured with their own custom GStreamer pipelines, allowing for rich configuration of how the stream is processed. This section will not explain the intricacies of GStreamer pipelines as the official website provides excellent documentation on how these work. Instead, included are a few pipeline examples.
BrainFrame does quite a bit of work in the background to ensure that many different IP camera types are supported seamlessly. When using custom pipelines, more intimate knowledge of the IP camera stream is required compared to using BrainFrame normally.
Note that all custom pipelines:
- Must include a
{url}template field. This is where the specified IP camera URL will be inserted into the pipeline. - Must have an
appsinkelement named "main_sink". This is where frames will be extracted from the pipeline for processing. - May optionally include an element named "buffer_src". This is required for
frame skipping to work with custom
pipelines. This name should be given to an element in the pipeline
that sections off frame data from the network before decoding, like
rtph264depay.
To specify a custom pipeline, check the "Advanced Options" checkbox in the stream creation window and enter your pipeline into the "Pipeline" textbox.

Example Pipelines
Cropping the Video Stream
For composite video streams or for scenes that contain uninteresting sections, one may want to crop the video stream before processing. Here is an example of a custom pipeline to accomplish this for an H264 RTSP stream:
rtspsrc location="{url}" ! rtph264depay name="buffer_src" ! decodebin ! videocrop top=x left=x right=x bottom=x ! videoconvert ! video/x-raw,format=(string)BGR ! appsink name="main_sink"
This pipeline uses the videocrop element to crop the video by some configurable value. The "x" values should be replaced with the amount in pixels to crop from each side of the frame.
Lower Latency Streaming
By default, BrainFrame will “buffer” frames in order to ensure a more stable streaming experience. In order to prevent that, try using the pipeline below:
rtspsrc location="{url}" latency=X ! rtph264depay name="buffer_src" ! decodebin ! videoconvert ! video/x-raw,format=(string)BGR ! appsink name="main_sink"
Replace the "X" in latency=X with 0 for no buffering at all. The unit X is in milliseconds.
Rotating the Video Stream
rtspsrc location="{url}" ! rtph264depay ! avdec_h264 ! videoconvert ! videoflip video-direction=x ! videoconvert ! video/x-raw,format=(string)BGR ! appsink name="main_sink"
The "x" value should be the number of degrees to rotate. Try numbers such as 0, 90, 180, and so on.
Hardware Decoding with Multiple Nvidia GPUs
BrainFrame automatically detects when an Nvidia GPU is available and attempts to do hardware video decoding on it. Currently, video decoding is only done on the first available device. This means that if your machine has multiple Nvidia GPUs installed, only one of them will be utilized.
GStreamer dynamically creates decoder elements that allow you to choose which Nvidia GPU the work will be done on. Using H.264 as our example format:
nvh264decuses device 0nvh264device1decuses device 1nvh264device2decuses device 2- ... and so on
By using different decoder elements for each stream's custom pipeline, you can
distribute decoding work across multiple GPUs. For example, if you had fifteen
video streams and three GPUs, you might consider having the first five use
nvh264dec, the next five use nvh264device1dec, and the final five use
nvh264device2dec.
The device IDs referenced here are CUDA device IDs. By default, CUDA orders devices from fastest to slowest, device 0 being the fastest. It is possible to change the way CUDA orders devices via an environment variable. See the official documentation for details.
Here is an example pipeline that uses device 1 to decode an H.264 RTSP stream:
rtspsrc location="{url}" ! rtph264depay name="buffer_src" ! h264parse ! nvh264device1dec ! glcolorconvert ! video/x-raw(memory:GLMemory),format=(string)BGR ! gldownload ! video/x-raw,format=(string)BGR ! appsink name="main_sink"
Warning
Current releases of the BrainFrame Client do not support using NVCODEC hardware decoding. Using these custom pipelines will cause streaming errors in the client as a result. We only recommend these pipelines for advanced use cases.
Frame skipping is a streaming mode available for IP cameras. Using frame skipping significantly increases the number of streams a single BrainFrame instance can handle at the cost of framerate.
Frame skipping allows BrainFrame to decode a significantly smaller amount of frames, cutting down on decoding overhead. As of now, the resulting framerate will depend on the keyframe interval of the video stream, which can often be configured in the settings for an IP Camera or NVR.
Frame skipping can be found under "Advanced Options" when creating an IP camera stream.

If you are specifying a custom pipeline, frame skipping will only work if an element in the pipeline is named "buffer_src". See the page on custom pipelines for details.
Performance Testing with Video Files
Introduction
You can benchmark video streaming and inference performance using the BrainFrame CLI fps-monitor command.
When validating BrainFrame's performance for a given use-case, you may want to use video files to simulate connecting to many IP camera streams. The built-in video file support in BrainFrame is good for some kinds of testing, but is not recommended for performance testing because it has significant overhead when compared to IP cameras.
For usecases like this, BrainFrame ships with a small RTSP server utility. This utility acheives significantly lower overhead by transcoding video files in advance. However, considering the main focus of this exercise is performance testing, we highly recommend running the RTSP server on a separate machine from the one running the BrainFrame server.
Using the RTSP Server Utility
Start by creating a directory containing the video files you would like to test with. Ensure that no other types of files are present in the directory. Then, run the following command:
docker run \
  --network host \
  --volume {video file path}:/video_files \
  aotuai/brainframe_core:0.29.2 brainframe/tools/rtsp_server/main
Replace {video file path} with a fully qualified path to the video file
directory you've created.
The RTSP server will start by transcoding all video files in the directory to a
known good format. This is to prevent video format incompatibilities and can
significantly improve streaming performance for the RTSP server. Once
transcoding is complete, new .mkv files will be created in the video file
directory. Transcoding will not be run again unless new video files are
introduced or the .mkv files are deleted.
When all video files have been transcoded, the RTSP server will start. An RTSP URL will be printed for each video file being streamed.
INFO:root:Video traffic_back_to_front.mkv available at rtsp://0.0.0.0:8554/traffic_back_to_front
INFO:root:Video test_store.mkv available at rtsp://0.0.0.0:8554/test_store
INFO:root:Video two_cool_guys.mkv available at rtsp://0.0.0.0:8554/two_cool_guys
Be sure to replace 0.0.0.0 with the local IP address of the machine that's
running the RTSP server.
Connecting to Many Streams
When doing performance testing at the level of tens to hundreds of streams, it can become burdensome to manage that many video files. Instead, it may be easier to connect BrainFrame to the same video stream multiple times.
BrainFrame does not allow you to connect to the exact same RTSP URL multiple times, as doing so during standard operation is wasteful. However, you can work around this limitation by adding dummy query parameters to the end of the RTSP URL.
rtsp://0.0.0.0:8554/test_store?dummy=1
rtsp://0.0.0.0:8554/test_store?dummy=2
rtsp://0.0.0.0:8554/test_store?dummy=3
rtsp://0.0.0.0:8554/test_store?dummy=4
...
The RTSP server utility is optimized to support many concurrent connections to the same stream. Make sure your local network has the necessary bandwidth to facilitate the scale of testing you plan to complete.
Ended: Tuning & Advanced Setup
Ended: User Guide
Deployment Guide ↵
Deployment Guide
This guide explains how to deploy and configure BrainFrame and its applications in your environment.
What's in this guide
- Prerequisites: compatible cameras, server requirements, and networking, with what you need to get started.
- Config Your IP Cameras: best practices for camera OSD and network settings.
- Config BrainFrame: start BrainFrame and configure the BrainFrame Server.
- Config Talkdown.ai App: deploy and configure the Talkdown.ai App.
- Save BrainFrame Settings: back up and restore BrainFrame settings.
Prerequisites
Before you deploy BrainFrame, make sure you have the following.
- Compatible cameras: any IP camera that supports RTSP. See Camera Compatibility for examples of tested cameras.
- A server: a Linux machine that meets the hardware and software requirements. See Server Hardware.
- Networking: cameras and the server on the same network, with the server reachable from users' devices and the internet. See Networking.
Config Your IP Cameras
These are best practices. They are not required by BrainFrame or its applications.
Camera OSD Configuration
The OSD text is used during the application configuration, as well as for markers in notifications and maps. Please configure the camera's On-Screen Display (OSD) field following the naming convention of the Camera Device ID & Camera Name in the sections below. If the position of the OSD is configurable, it should typically be placed near the top edge of the view to minimize interference with ground-level detections.
Camera Network Configuration
- Enable ONVIF
Some cameras may require a dedicated ONVIF username and password to be configured.
BrainFrame does not use ONVIF protocol to change camera settings. Be aware that some NVR or VMS systems may change camera settings through the ONVIF protocol if the camera is added to those systems.
- Disable Cloud Platform Access
Camera Security Configuration
- Anonymous Login: Disable
- ONVIF Authentication: ON
Camera Video & Imaging Configuration
Video Configuration
- Encode Mode: H.264
- Resolution: 1080P (1920x1080)
- Frame rate (FPS): 20
Imaging Configuration
- Exposure | DayNight Mode: Set to Automatic.
- Daytime: Color Mode
- Nighttime: Monochrome (B&W) IR Mode / Night Mode
- Illumination | IR (Infrared): Uses built-in IR LEDs by default. This allows BrainFrame to control White/Dual light LEDs.
Camera Device ID
This is used to mark the device or location on a map.
- {Region of Interest, Camera, Garage, Indoor, Outdoor}{Floor ID: Basement, Ground, 1, 2, 3, 4}-{Location ID ##}
- Use R for a Region of Interest with no camera installed.
- Use C or G, I, O for cameras installed.
- Examples: CB-10, C1-7, R1-10
Camera Name (Camera Device ID + Semantic Name)
This is used to set up the camera On-Screen Display (OSD) field.
- {Camera Device ID}-{Region Name}-{Optional Sub-Region Name or custom String}-{Location ID ##}
- Example: C1-7-Street-Door-2
Time
Configuring the camera Time & DST:
- Sync Mode: Sync with NTP Server
- Time Zone
- DST
- Enable: On
- Start Time: Apr, 1st Week, Sun 2:00 AM
- End Time: Oct, Last Week, Sun 2:00 AM
Configuring the camera NTP Server:
- NTP Server Address: us.pool.ntp.org, time.windows.com
- Port: 123
- Update Interval(s): 600
Config BrainFrame
Start BrainFrame
Start and stop BrainFrame with the commands below.
brainframe compose up
brainframe compose down
Config BrainFrame
The Talkdown.ai App will read streams, alarms, and alerts from the BrainFrame Server. Configure the BrainFrame Server with the following:
Add cameras to BrainFrame
BrainFrame supports real-time video streaming from Webcams (USB cameras) or any IP camera. In general, any IP camera that is compatible with RTSP is supported.
Add streams, zones, and alarms in the BrainFrame UI:
For proof-of-concept or small deployment projects, users can simply enter the RTSP URL to add a camera to BrainFrame. For large deployments, brainframe-onvif-tools automatically discovers and configures IP cameras that are compatible with ONVIF and other protocols—significantly reducing setup effort and ensuring system-wide consistency.
Download VisionCapsules from AI Marketplace
Use the VisionCapsule AI Marketplace to download VisionCapsules to My VisionCapsules, then load them into BrainFrame OS.
Note:
The following VisionCapsules are recommended: - detector person vehicle bike openvino - detector person administration - tracker vehicle iou
Other VisionCapsules available for worker safety applications: - Detector Safety Gear Openvino - Calculator Object Speed
Other VisionCapsules available for security applications: - classifier person with crowbar (experimental) - classifier person with hoodie (experimental) - ChatGPT Classifier Agent (experimental, third-party account & fee required) - Claude Classifier Agent (experimental, third-party account & fee required)
text / OCR are included automatically for License Plate Recognition.
Smart Zones, Lines, Alarms
Setup Alarms with AWDE Four-Stage deterrence protocol
BrainFrame is capable of setting up Talkdown voice, Warning Lights, and PTZ with multiple Smart Lines and Zones within the same camera or across multiple cameras. This allows a user to set up an alarm system using a four-stage deterrence strategy.
| AWDE Stages | Voices | Lights | PTZ | Zones & Lines | Duration | Start-End Time |
|---|---|---|---|---|---|---|
| Awareness | You’re on camera. | - | - | Assets unreachable | > 5 secs | 00:00:00-23:59:59 configurable |
| Warning | Leave the area. | - | - | Assets reachable | > 10 secs | 00:00:00-23:59:59 configurable |
| Demand for Compliance | Leave now or we call 911. | ON | - | Assets reachable | > 20 secs | 00:00:00-23:59:59 configurable |
| Escalation with Human-in-the-loop | Siren & callout. | ON | ON | Assets reachable | > 30 secs | 00:00:00-23:59:59 configurable |
Setup Alarms for Perimeter Protection
Users can set up Alarms with Smart Lines and Zones for perimeter protection. We recommend following this naming convention for large deployments:
| Items | Names |
|---|---|
| Lines | LINE-{LINE NAME} |
| Zones | ZONE-{ZONE NAME} |
| Alarms | ALRM-{DETECTION}-{ATTRIBUTE}-{AWDE SUFFIX} |
Check the BrainFrame Client UI to make sure alerts can generate properly with the configured Alarms. Use the naming convention above when configuring Reactions in the app.
Setup Alarms for Tailgating
The number of vehicles in a Zone can be used to trigger a Tailgating alarm.
Config Talkdown.ai App ↵
Config Talkdown.ai App
The Talkdown.ai App is a reference design for application implementation based on BrainFrame OS. These instructions explain how to deploy and configure the Talkdown.ai App on a new server using pre-built images from Docker Hub.
Before you begin, complete the steps in Prepare.
Prepare
Gmail credentials and service account files
The app sends emails from a Gmail account and monitors replies for commands. gmail_credentials.json is required for Google sign-in. service_account.json lets the app manage Google Pub/Sub resources without requiring the Gmail user to have project Editor permissions. Generate these files if you do not have them.
gmail_credentials.jsonservice_account.json
Create the directory below and place gmail_credentials.json in it before starting the app. Add service_account.json if you use a service account for Pub/Sub.
- Create the necessary directories on the new machine.
# Run from the directory containing docker-compose-released.yml
mkdir -p gmail
Use BrainFrame CLI to find out your {install_path}:
brainframe info install_path
- Copy
gmail_credentials.jsonand, if applicable,service_account.jsoninto the gmail subdirectory you just created. The final paths on your server are{install_path}/gmail/gmail_credentials.jsonand{install_path}/gmail/service_account.json.
You can use tools like scp or rsync to copy the files from your local machine to the new server. For example:
# Example using scp from your local machine
scp /path/to/your/local/gmail_credentials.json user@<NEW_MACHINE_IP>:{install_path}/gmail/
scp /path/to/your/local/service_account.json user@<NEW_MACHINE_IP>:{install_path}/gmail/
Have user email addresses ready
- Notification email addresses (for storage and post-incident investigation)
- Human-in-the-loop email addresses (for real-time response)
- Report email addresses (for management)
Connect Talkdown.ai App to BrainFrame Server
Once the app is running, it needs to be pointed at the BrainFrame server. In a standard deployment, the Reaction Server and the BrainFrame Server are the same server.
- Open the Web UI: Go to
http://<NEW_MACHINE_IP>:3500in your browser. - Navigate to the "Server" Tab.
- Fill in the Server Addresses:
- Reaction Server Address: This should already be correct (
http://<NEW_MACHINE_IP>:3501). - BrainFrame Server Address: Enter the full URL of your BrainFrame server (e.g.,
http://<NEW_MACHINE_IP>). DO NOT USEhttp://localhost; use the network card IP address instead.
- Reaction Server Address: This should already be correct (
- Click "Save & Check Connections". The status indicators at the top should turn green and show "Connected".
Config Sound
Navigate to the Sounds tab in the UI to configure the following:
- Upload recorded sound files for common deterrence use cases.
- Generate TTS Audio according to your use cases.
Note:
Talk down message examples:
- FrontDoor.aac: This is private property; this area is recorded 24/7. If you are not a resident or authorized visitor, leave immediately or you will be reported.
- PackageRoom.aac: This package room is for authorized personnel only and is recorded 24/7. Unauthorized entry is prohibited. If you are not authorized, exit immediately or you will be reported.
- Garage.aac: This garage is under surveillance and is being recorded 24/7. If you are not a resident or authorized visitor, leave immediately or you will be reported.
- GarageEntrancePedestrian.aac: Attention: You are in a monitored area. Pedestrian access is not permitted. If you need assistance with the garage door, please contact management. If you continue to linger, this video recording will be reported to management.
- vehicle_tailgating.aac: Please do not tailgate into the resident-only parking area. Your license plate and image are being recorded.
- police_siren_711a.aac
Config Gmail
Navigate to the Storage & Settings tab in the UI to configure the following:
- Configure EmailLabelForThisMachine. This will be the prefix of the email subject.
- On the Server tab, under Email Configuration, click "Sign in with Google" to authorize the account that will send emails.
WARNING!
- Sign-in must be completed on the server itself using
http://localhost:3500in the browser.- You may see a Google verification warning if the OAuth app configured in
gmail_credentials.jsonhas not been verified.
Config AWDE Four-Stage Notifications and Deterrence
Config Reaction Name, Triggering Time & Interval
Navigate to the Reactions tab in the UI to configure the following for each alarm: * Add a Reaction with a proper Name. * Set Fire Only if Alert is Going On Longer Than (sec). * Set Alert Update Interval (sec). * Set Start Time and End Time.
Config Email & SMS Notifications
Navigate to the Reactions tab in the UI to configure the following for each alarm:
- Select Notification.
- Check Send Email and add Email Addresses.
- Stage AWDE: Fill in recipient email addresses. Picture notification emails can be used for post-event investigation purposes.
- Stage E: Fill in email addresses for human-in-the-loop escalation.
- Check Send SMS and add SMS Numbers.
- Stage AWD: Leave SMS Numbers empty.
- Stage E: Optionally, fill in SMS numbers.
Config Deterrence
Camera Talkdown SoundEffect
Navigate to the Reactions tab in the UI to configure the following for each alarm:
- Select SoundEffect.
- Select the Camera & Speaker Model. Configure the Speaker URL if needed.
- Check Play Sound, then select Sound.
- Set Duration Sec.
Currently, the speakers of the following Camera & Speaker models are certified:
- Dahua
- Bullet Camera N45EF63
- Uniview
- MultiView Dual-light PTZ IP Camera IPC9312LFW-AF28-2X4
- Tri-Guard Turret IP Camera IPC3634SS-ADF28KMC-I1
- Tri-Guard Fixed Dual-light Bullet IP Camera IPC2B15SS-ADF28KMC-I1
- Outdoor IP Speaker IPS302030-S
Camera Warning with LED Strobe Light
Navigate to the Reactions tab in the UI to configure the following for each alarm:
When adding a Reaction, select SoundEffect.
- Check the Warning with LED box.
The Warning with LED checkbox is available for these Uniview camera models:
- Tri-Guard Turret IP Camera IPC3634SS-ADF28KMC-I1
- MultiView Dual-light PTZ IP Camera IPC9312LFW-AF28-2X4
Camera Deterrence with Siren & PTZ
When a siren sound is playing, PTZ will be activated on cameras with PTZ support.
Currently, the PTZ features of the following Uniview Camera models are certified:
- MultiView Dual-light PTZ IP Camera IPC9312LFW-AF28-2X4
Email commands escalation with Siren & PTZ by human
When a siren sound plays, if email notifications are configured, the user will receive an email. The user can reply with any of the following commands:
- stop — Stops the currently playing sound.
- siren — Plays a police siren.
- say [message] — Play the typed text as speech. (Example: say Please leave the area immediately)
- mute [minutes] — Mutes the speaker for a specified duration in minutes. (Example: mute 30. Default: 30 minutes)
- unmute — Unmutes the speaker if it was previously muted.
The Talkdown.ai App uses Text-to-Speech (TTS) to play voice messages sent via the say command. If the email command is Siren, PTZ (Pan-Tilt-Zoom) will be activated on compatible cameras.
Please configure PoliceSirenSoundId under Storage & Settings | Settings. This sound will be triggered by the siren command listed above.
Configure Voice Alerts for the SOC (Security Operation Center)
Navigate to the Reactions tab in the UI to configure the following for each alarm:
This is similar to the Camera Talkdown SoundEffect, except you select AI Server Speaker Default Driver for the Camera & Speaker Model. The sound will then be played through the AI Server Speaker.
Note:
Set up a Multi-room Audio System on the following OSs, so the Voice Alerts can broadcast to other Machines and Mobile Devices: - Linux - Windows - MacOS - Android
Config email addresses for management reports
Navigate to the Users tab in the UI to configure the following:
- Add contacts with the Admin type and email addresses to receive Daily Reports.
Config Network Video Recorder (NVR)
Navigate to the Storage & Settings tab in the UI to configure the following:
- Configure VIDEO_RECORDER_ADDRESS and VIDEO_RECORDER_MODEL.
Setup Maps & Locations
Navigate to the Maps & Locations tab in the UI.
- Upload a Map.
- Draw Semantic Locations.
Maintenance
Setup Auto-Pruning
Navigate to the Storage & Settings tab in the Web UI. Enable Daily Pruning and set Data Retention (Days) based on available storage. Common configurations are:
- 7 days
- 30 days
- 90 days
Manual Pruning
Navigate to the Storage & Settings tab in the Web UI. Users can perform manual pruning at any time.
Export (Backup) & Import (Restore) App configuration from UI
Navigate to the Storage & Settings tab in the Web UI. Users can use Export Settings and Import Settings.
Ended: Config Talkdown.ai App
Save & Restore BrainFrame Settings
Use brainframe-apps CLI to backup and restore BrainFrame settings
Ended: Deployment Guide
BrainFrame Applications ↵
BrainFrame Applications
BrainFrame OS comes with applications and tools for managing your video analytics deployment.
Applications
Enter the IP address of the BrainFrame server in a browser to open the BrainFrame Web Client and access BrainFrame features: add video streams, configure capsules, draw zones, create alarms, and view detections.
Click Developer at the bottom left of the main menu to bring up the Developer References menu. Click a menu item to open the other BrainFrame applications and resources:
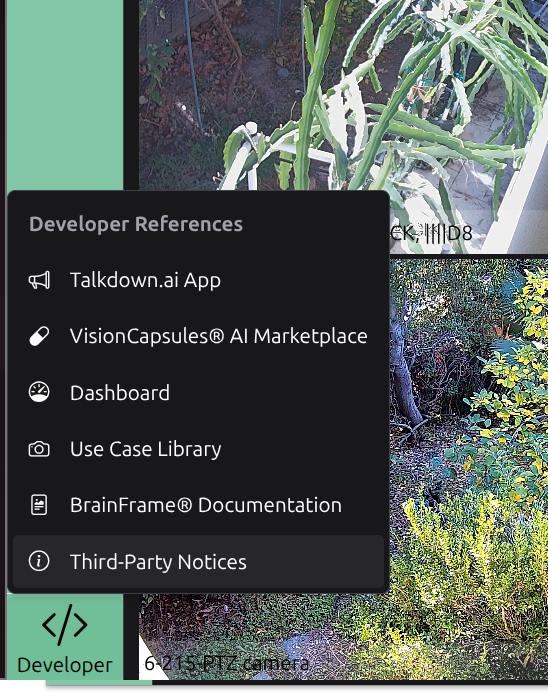
| Menu item | Opens |
|---|---|
| Talkdown.ai App | The Talkdown.ai App: react to BrainFrame alarms with email alerts, sounds, voice messages, and NVR clips. |
| VisionCapsules® AI Marketplace | The AI Marketplace: browse, download, and load VisionCapsules. |
| Dashboard | The Web Dashboard: inspect BrainFrame data. |
| Use Case Library | The Use Case Library: turn sample videos and images into RTSP streams for demos and testing. |
| BrainFrame® Documentation | This documentation. |
| Third-Party Notices | The licenses of the third-party software that BrainFrame uses. |
Command-line tools
- BrainFrame CLI: install and manage BrainFrame from the terminal.
- Dev Tools: onvif tools, REST API Apps, system tools, and capsule tools.
Web Client
The BrainFrame Web Client is the browser interface of BrainFrame OS. Use it to add video streams, load capsules, draw zones and lines, create alarms, and watch live detections. Nothing needs to be installed on your computer.
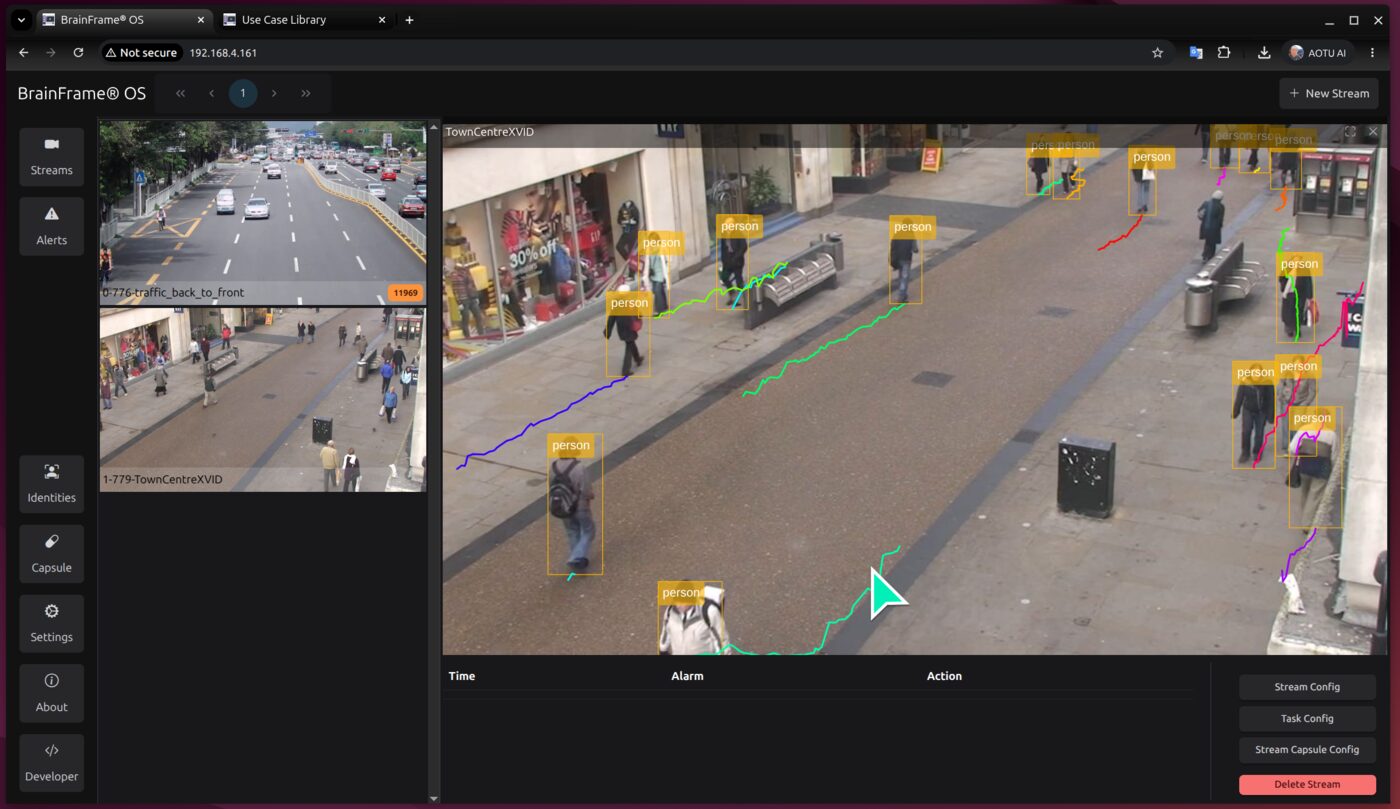
Open the Web Client
Enter the IP address of the BrainFrame server in a browser:
http://<your-server-ip>
Tip
Use the server's network IP address rather than localhost. This lets the other applications that run in
containers, such as the Talkdown.ai App, reach BrainFrame at the same address.
The main menu on the left has these entries:
| Menu | Purpose |
|---|---|
| Streams | Show your video streams. |
| Alerts | Review the alerts that alarms have triggered. |
| Identities | Manage the identities that BrainFrame can recognize. |
| Capsule | Load, enable, and configure capsules for all streams. |
| Settings | Change how the Web Client displays video and detections. |
| About | Show the BrainFrame version. |
| Developer | Open the Developer References menu, described in BrainFrame Applications. |
Add a Stream
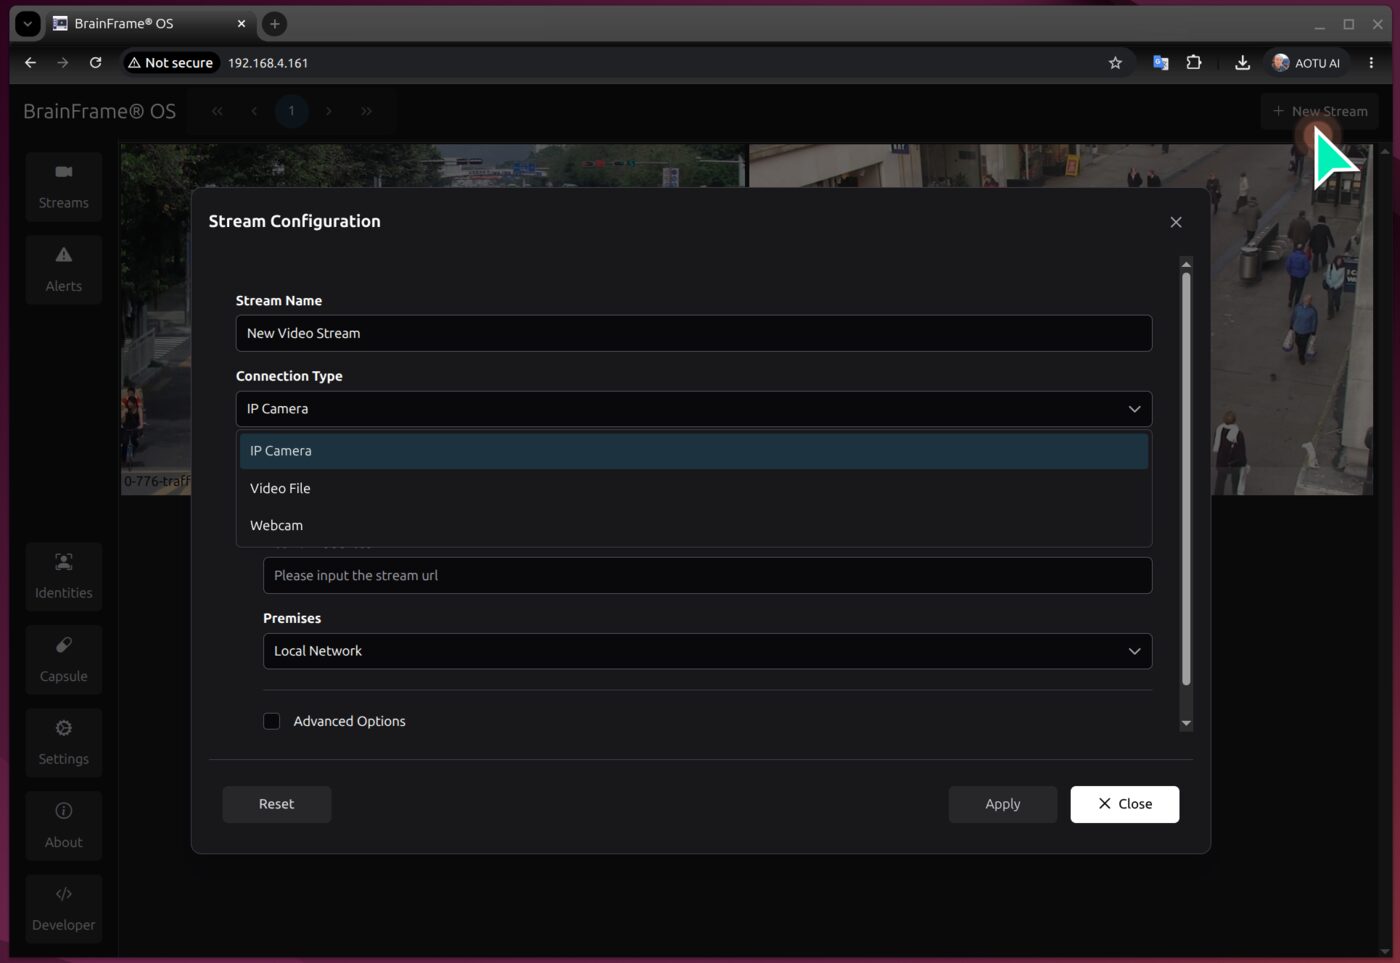
- Click + New Stream.
- Give the stream a name.
- Enter the address of the video source, for example the RTSP URL of an IP camera. IP cameras, local video files, and webcams are supported.
- Confirm to add the stream.
Advanced users can write their own GStreamer pipeline instead of using a URL.
To see the details of a stream, such as its connection type and network address, click the stream and then Stream Config. For more on streams and their options, see Streams. For help with camera URLs, see Connecting to IP Cameras.
Tip
To add many cameras at once, see brainframe-onvif-tools and REST API Apps.
View Streams
New streams appear in a grid of thumbnails. Click a stream to open the Player View, which shows the live video in the middle and your list of streams on the left. Use the buttons at the lower right to open Stream Config, Task Config, and Stream Capsule Config, or to delete the stream.
Media modes
BrainFrame has three media modes. They trade video quality against hardware use. Choose them in Settings > Streams, separately for the thumbnail view, the player view, and the task configuration view.
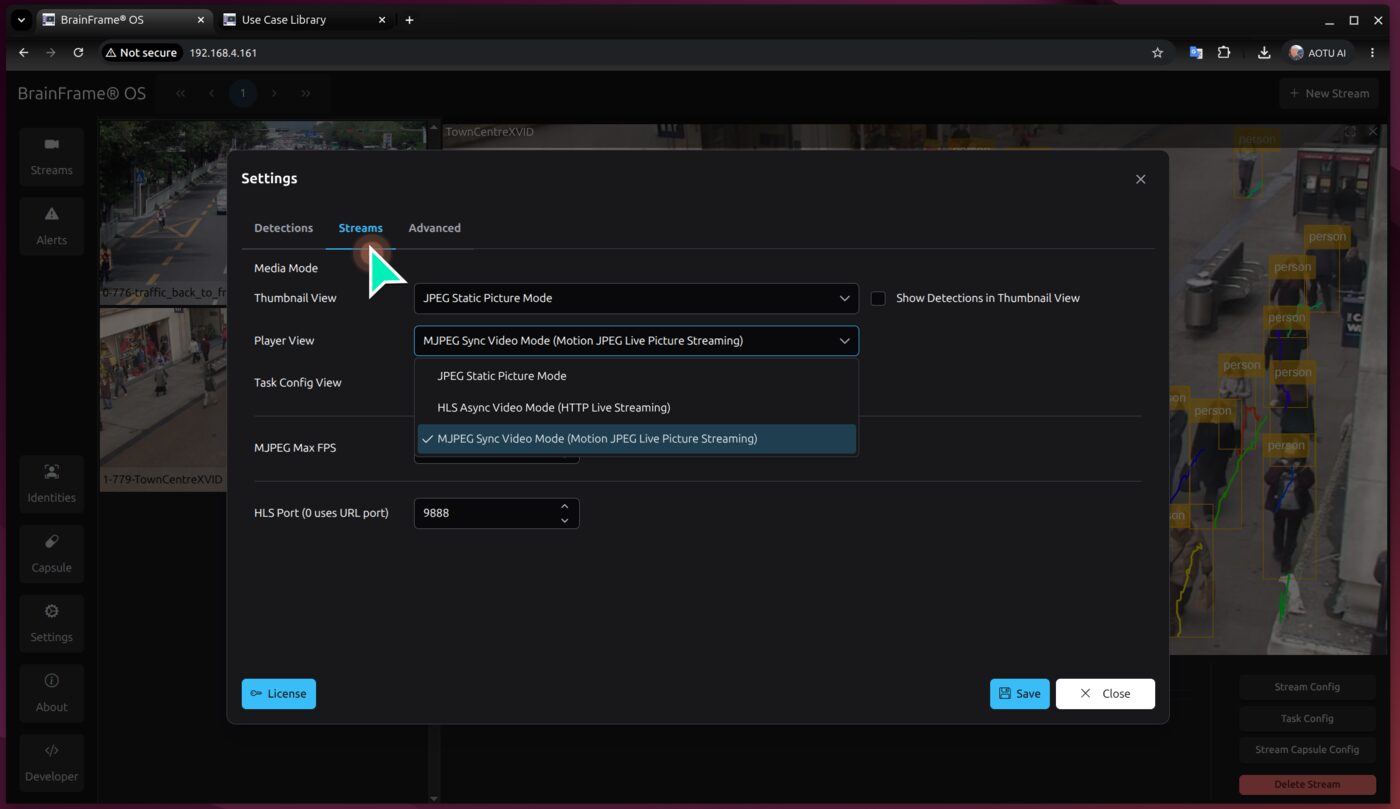
| Mode | Description |
|---|---|
| MJPEG Sync Video Mode | Each video frame is shown together with its own inference results, so the detections always match the picture. This is the default for the player view. |
| JPEG Static Picture Mode | Shows still pictures instead of video. It turns off the heavy video decoding and rendering, which leaves more processing power for inference. Use it for large deployments, or where you do not need to watch live video. |
| HLS Async Video Mode | Plays a smooth live video stream by separating the video from the inference results. This uses less computing power, but the detections can lag behind the picture slightly. |
Select Show Detections in Thumbnail View to draw detections on the thumbnails, so you can see the analytics of every stream at once. The same dialog also sets the MJPEG maximum frame rate and the HLS port.
Choose what to display
When many capsules run together, the overlay on the video can become crowded. Open Settings to choose which information to draw on the video.
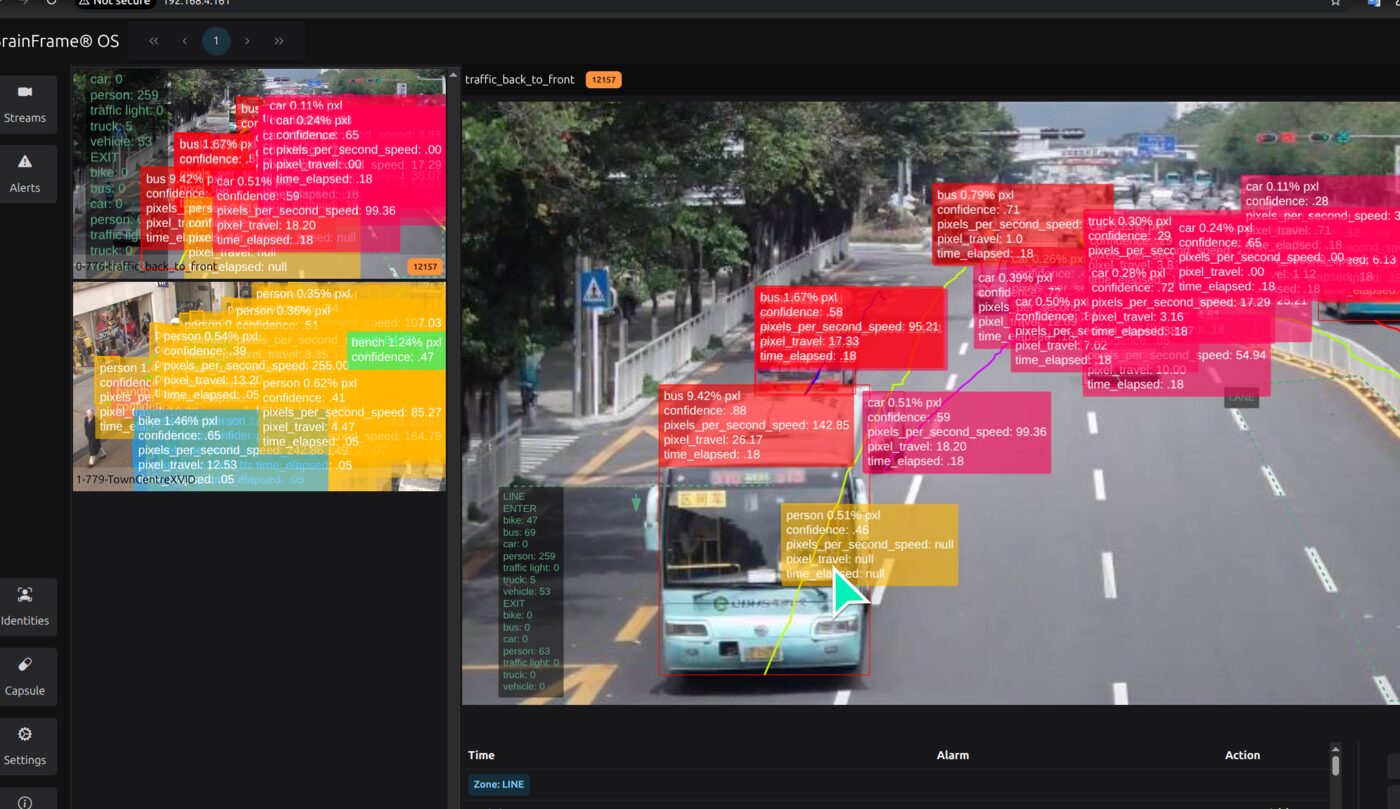
Load and Configure Capsules
Capsules are the AI models that BrainFrame runs. You can download capsules from the VisionCapsules marketplace and load them into BrainFrame.
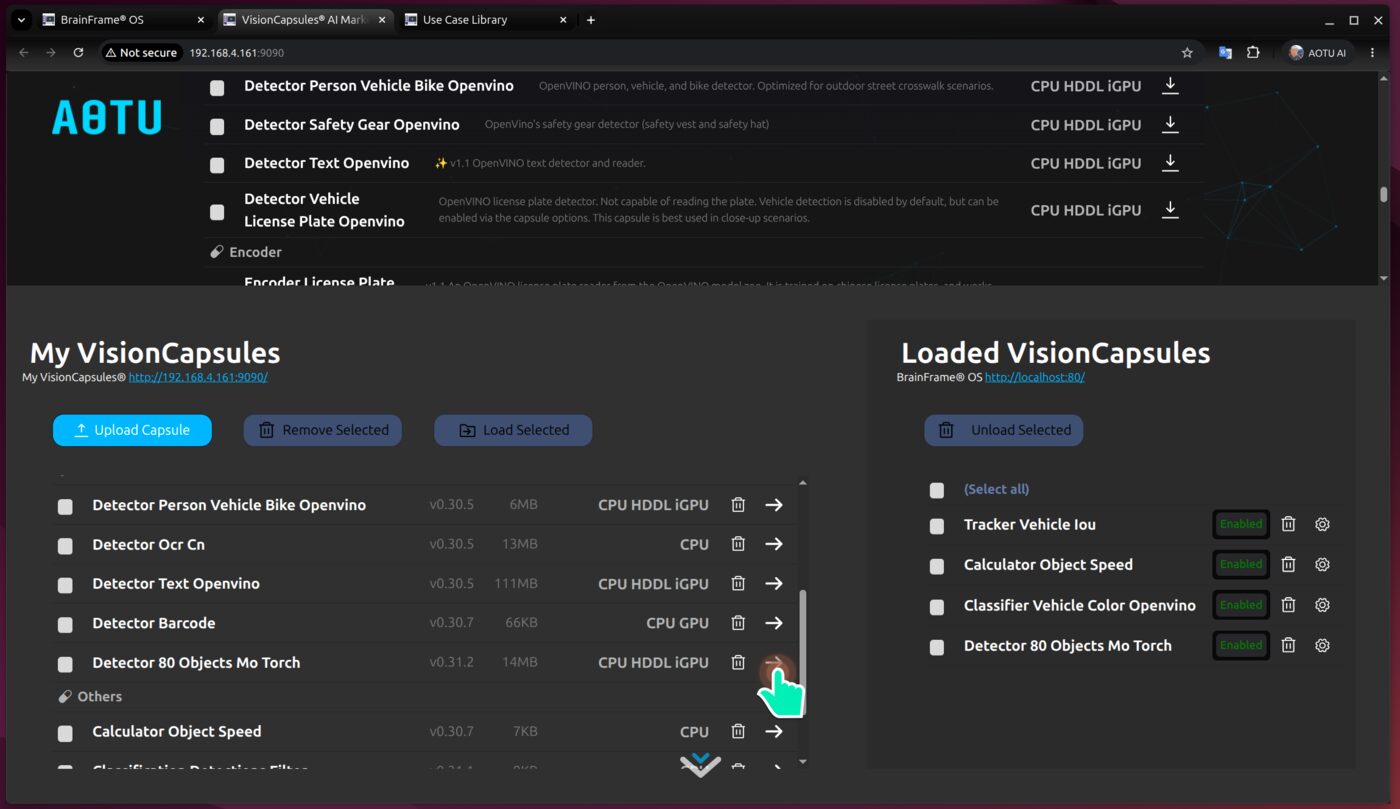
- Hover over a capsule to see details, such as the objects it can detect.
- Download a capsule, then load it into BrainFrame.
- A loaded capsule can be turned on or off without unloading it. Use the settings gear to adjust its options.
For the traffic example in this guide, four capsules are loaded: a person, vehicle, and bike detector, a vehicle IOU tracker, an object speed calculator, and a vehicle color classifier.
Click Capsule on the main menu to enable, disable, and configure capsules for all streams. To set a capsule only for one stream, open the stream and click Stream Capsule Config. After you turn a capsule on or off, or change an option, click Apply, and then OK.
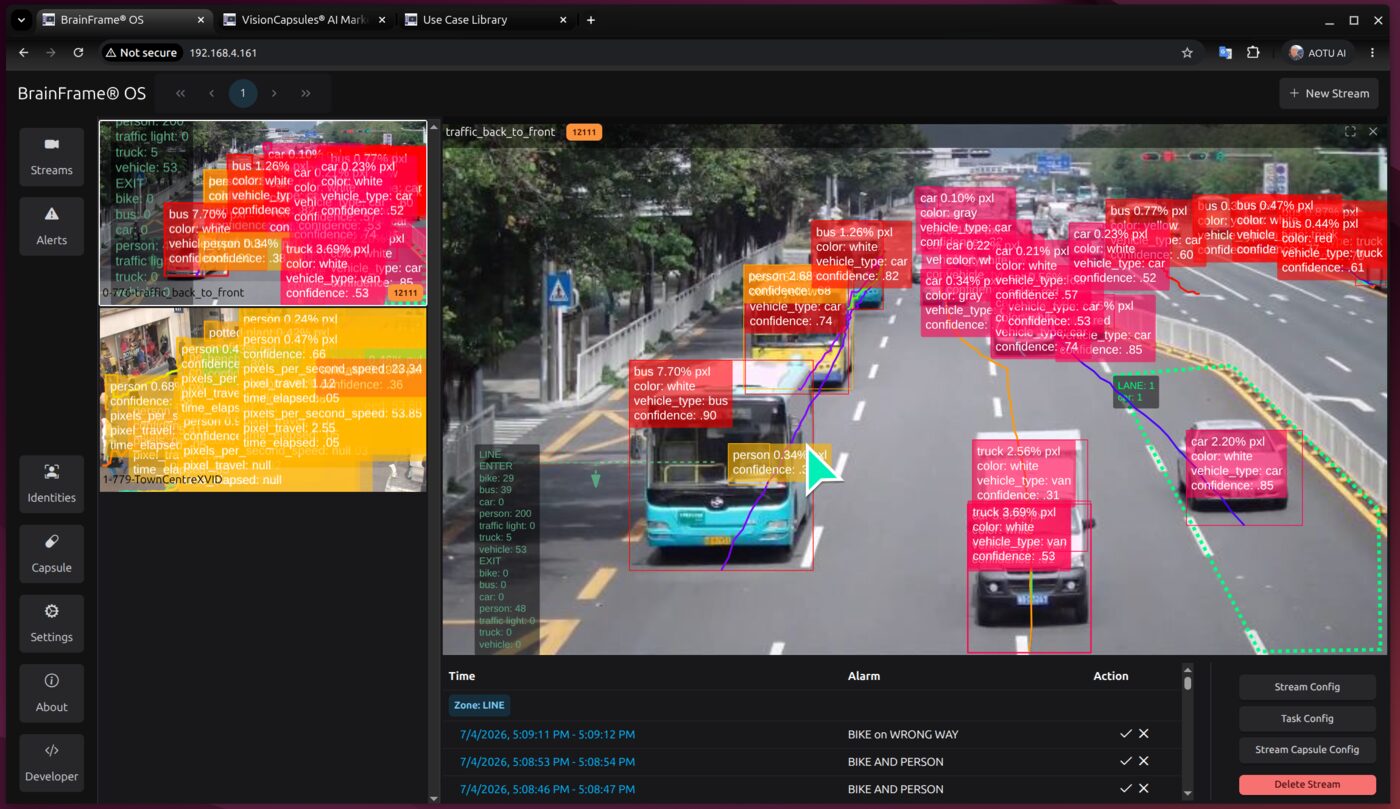
The detections update immediately. In this example, the color disappears from the bounding box when the color classifier is off, and the trajectory behind the vehicle disappears when the tracker is off. See Capsule Options for details.
Zones and Lines
Zones and lines select where in the video BrainFrame looks for events. They let you count objects that cross a line, find vehicles that go in the wrong direction, monitor speed, or measure how long an object stays in an area.
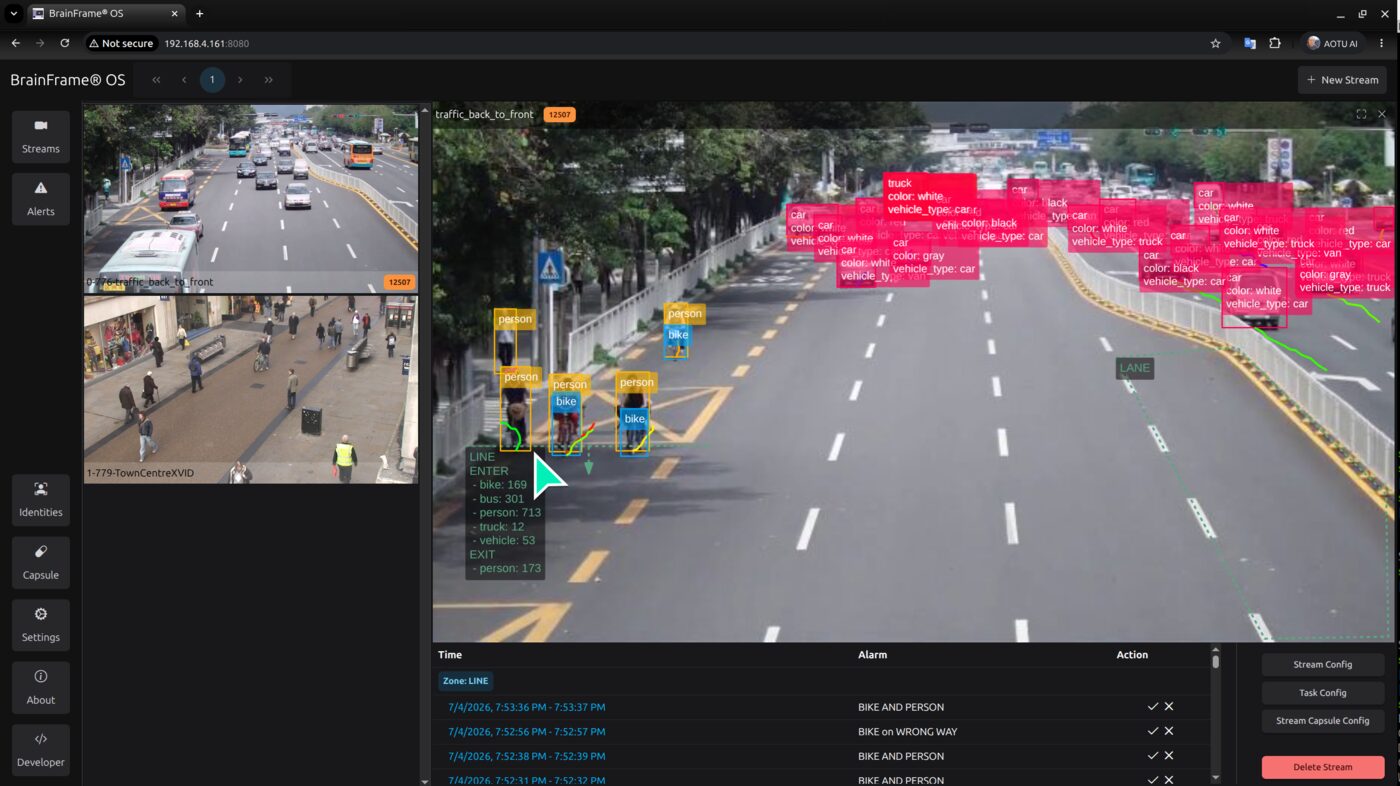
To add one:
- Open the stream and click Task Config.
- Click + Region or + Line.
- Name it, then draw it on the video with your mouse. For a region, draw a polygon.
- Click Confirm. The zone is active at once.
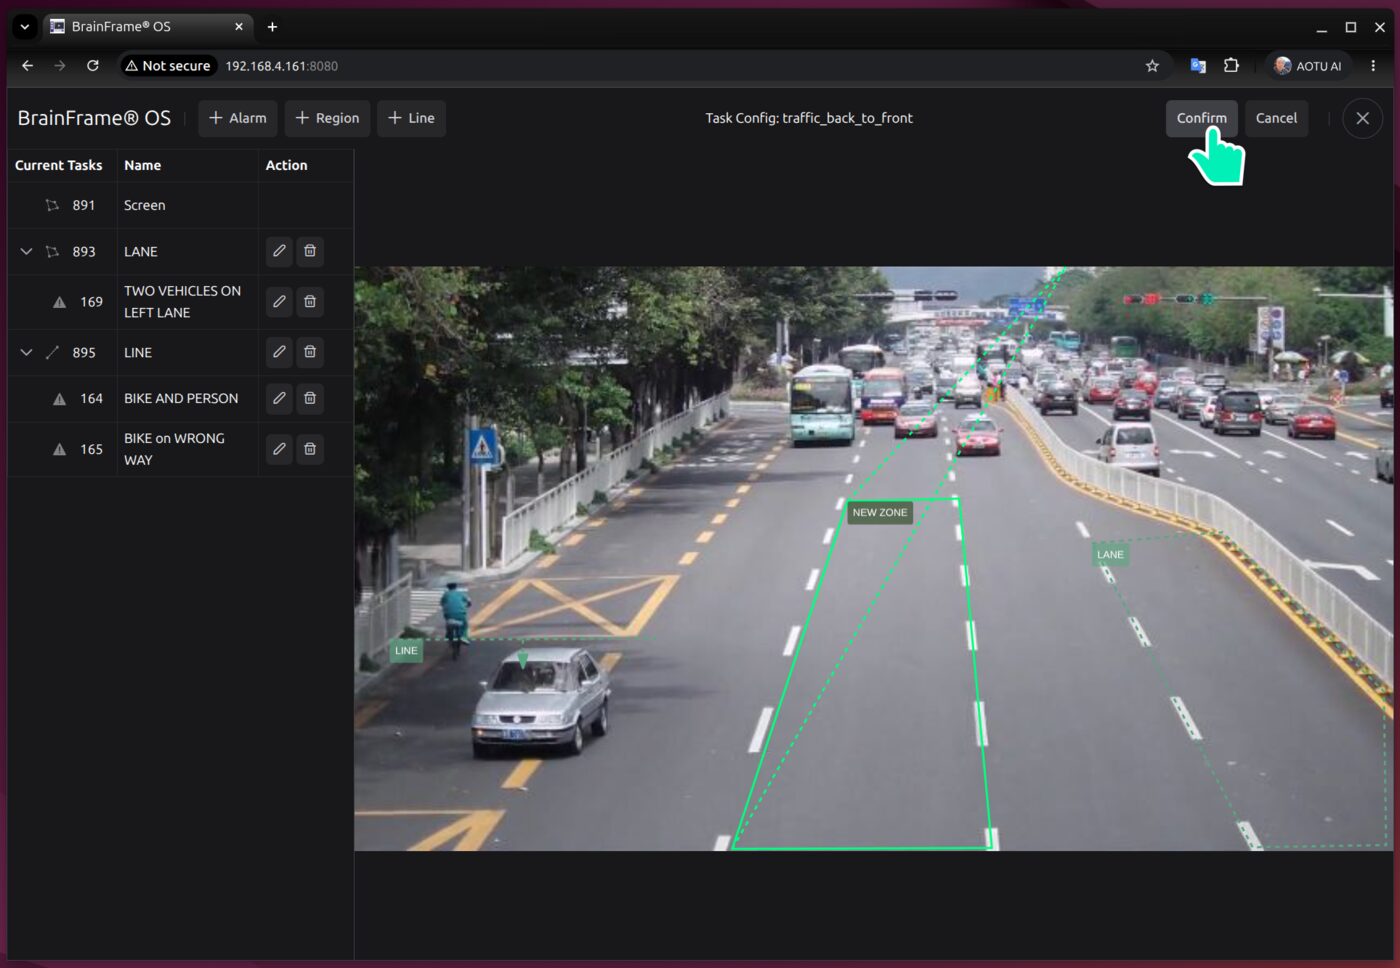
See Zones for more.
Alarms
An alarm triggers when the objects in a zone meet a condition.
- In Task Config, click + Alarm.
- Select the zone to monitor.
- Choose the Count Based or Rate Based type. A count-based alarm triggers on how many objects are in the zone. A rate-based alarm triggers on how quickly objects enter or leave.
- Set the condition: the comparison, the number, the object type, and, if needed, an attribute such as a color.
- Set how long the condition must hold, within what time window, and the times of day when the alarm is active.
- Click Save, then Confirm.
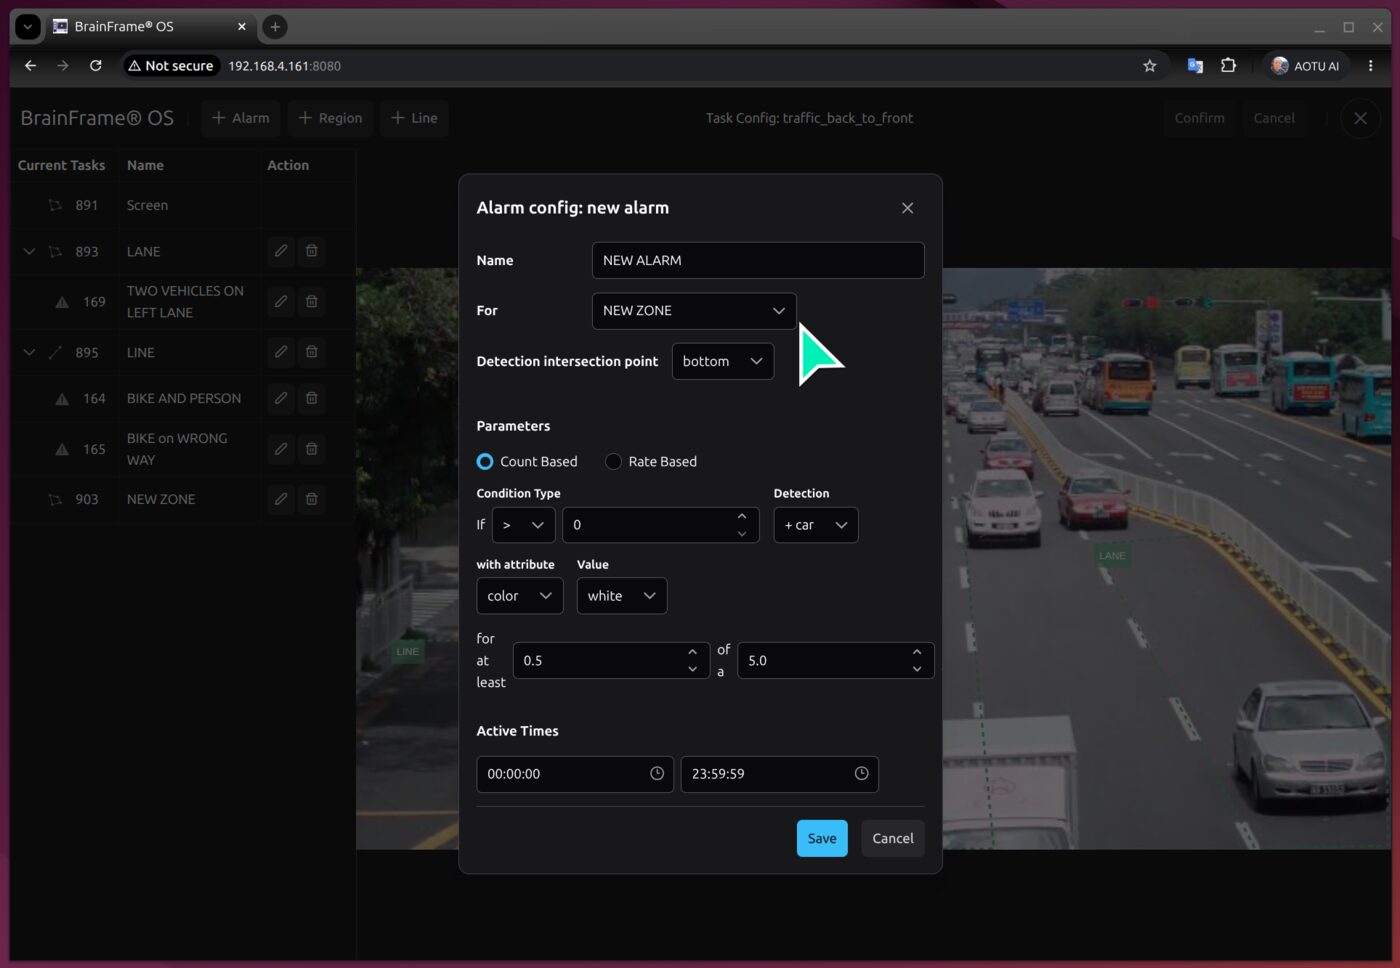
Triggered alarms are listed under Alerts. See Alarms for more.
Alarms can start real-world actions, such as email, sirens, and voice messages, through an application like the Talkdown.ai App.
Use the Data in Your Own Applications
- REST API: all live results, such as zone statuses, are available through the BrainFrame REST API. See the REST API reference. To find the zone status, open inference and then Get zone statuses, and see the data under Responses.
- Database: the results are stored in an SQL database. You can query it, or connect a dashboard to it. See Database Description.
Check the Version
Click About to see the version that is running. To check for new releases, see Downloads. To upgrade, see brainframe-cli.
Hardware
The server hardware decides how many streams and capsules you can run at once. See Server Hardware.
AI Marketplace
The VisionCapsules® AI Marketplace is a web application for managing the capsules of a BrainFrame server. It is installed with BrainFrame. Use it to:
- Browse and download capsules that are published on the aotu.ai website.
- Upload capsule files (
.cap) that you built or received. - Load capsules into the BrainFrame server, and unload them.
- Enable or disable loaded capsules, and change their options.
For what a capsule is, see Capsule Options. To write your own capsule, see the VisionCapsule documentation.
Open the AI Marketplace
To open the AI Marketplace, type the IP address of the BrainFrame OS server in a browser to open the BrainFrame Web Client. Once connected, click the Developer button at the bottom left to bring up the Developer References menu, then click VisionCapsules® AI Marketplace.
You can also open it directly in a browser:
http://<your-server-ip>:9090
The page has two parts. The top part, Explore VisionCapsules, is the marketplace. Scroll down, or click the arrow at the bottom of the page, to open the lower part, which has two lists:
| List | Contents |
|---|---|
| My VisionCapsules | The capsule files that are stored on the server. These are capsules you downloaded or uploaded. They are not yet running. |
| Loaded VisionCapsules | The capsules that the BrainFrame server has loaded. Only loaded capsules can run on streams. |
Note
The two lists in the lower part need a browser window at least 1460 pixels wide. On a narrower window they are replaced by a warning.
A capsule moves through three steps: download it from the marketplace into My VisionCapsules, load it into BrainFrame, and then enable it for your streams.
Download Capsules
The marketplace lists the capsules grouped by type: Classifier, Detector, Encoder, Tracker, OCR, and Others. Each row shows the capsule name, its description, and the hardware it runs on. Capsules marked with ✨ are recommended as production-ready.
| Hardware | Meaning |
|---|---|
CPU |
Runs on any processor. |
GPU |
Runs on NVIDIA GPUs. |
iGPU |
Runs on Intel integrated graphics, through OpenVINO. |
HDDL |
Runs on MyriadX devices, through the OpenVINO HDDL plugin. |
Hover over a capsule name to see its details, such as the input it needs and the detections it produces.
To download:
- Click the download icon at the end of a row to download one capsule.
- Or tick the check boxes of several capsules, and click Download Selected.
Downloaded capsules appear in My VisionCapsules. A capsule that is already there can not be downloaded again. Remove it first if you want to download it again.
Note
The list of capsules is read from aotu.ai/docs/downloads, so the server needs access to the internet to show the marketplace and to download capsules. On a server with no internet access, upload capsule files instead, as described below. See Offline Deployment.
Upload a Capsule
To add a capsule file that you have on your computer:
- In My VisionCapsules, click Upload Capsule.
- Choose the
.capfile. - Enter the Version, for example
v0.30.8. This is required, and is used to keep different versions of the same capsule apart. - Select the Chipset that the capsule supports.
CPUis always selected. AddiGPU,HDDL, orGPUif the capsule uses them. - Click the upload button of the dialog.
A file with the same content as a capsule already in My VisionCapsules is rejected as a duplicate.
Load Capsules into BrainFrame
In My VisionCapsules:
- Click the right arrow at the end of a row to load one capsule.
- Or tick several capsules and click Load Selected.
The capsule is sent to the BrainFrame server. Loading can take a while, because the server prepares the model. A progress message is shown, and the page cannot be used until it finishes. When it is done, the capsule appears in Loaded VisionCapsules.
If the BrainFrame server can not be reached, loading fails with an error. Check that the server is running.
Manage Loaded Capsules
Each loaded capsule has these controls:
| Control | Action |
|---|---|
| Enabled / Disabled | Turn the capsule on or off for all streams. A disabled capsule stays loaded. |
| Trash icon | Unload the capsule from BrainFrame. |
| Gear icon | Open the capsule's options, to change its settings. |
To unload several capsules, tick them and click Unload Selected.
The options are the same as those in the Web Client. Changes take effect for all streams. To set options for one stream only, use the stream's capsule configuration in the Web Client. See Capsule Options.
Note
Capsules that BrainFrame loaded from its capsule directory, rather than through the AI Marketplace, are shown in the list too. They can be enabled, disabled, and configured, but they can not be unloaded here. To remove them, remove the files from the capsule directory.
Remove Capsules from My VisionCapsules
To delete a capsule file from the server, click the trash icon in its row, or tick several and click Remove Selected. This removes the file only. A capsule that is already loaded stays loaded until you unload it.
Where the Data Is Kept
The AI Marketplace runs as the marketplace service in the BrainFrame docker-compose.yml. It listens on port 9090.
The downloaded capsule files and the list of capsules are stored in the BrainFrame data volume, in the
volumes/marketplace directory, and are kept when BrainFrame is restarted.
The AI Marketplace manages the BrainFrame server that it runs alongside, and connects to it through the BrainFrame REST API.
Use Case Library
The Use Case Library turns video files and pictures into simulated IP cameras. It stores a collection of sample videos, publishes each of them as a live RTSP stream, and can add the streams to BrainFrame in one step. Use it to demonstrate a use case, test capsules and alarms, or build a test system with many "cameras" without any camera hardware.
For each file, the library provides:
- An RTSP stream that looks like an IP camera to BrainFrame and to other RTSP clients, such as VLC.
- An HLS stream that plays in a web browser.
- A loop: the video plays again from the start when it ends, so the "camera" never goes offline.
Note
The Use Case Library is a separate application. It is not part of the BrainFrame server, and it runs in its own container.
To open the Use Case Library, type the IP address of the BrainFrame OS server in a browser to open the BrainFrame Web Client. Once connected, click the Developer button at the bottom left to bring up the Developer References menu, then click Use Case Library.
Install
You need Docker on the machine that will host the library. This can be the BrainFrame server or another machine on the same network.
The library runs as the Docker image aotuai/stream-simulator, and uses these ports:
| Port | Use |
|---|---|
| 7090 | The web interface. |
| 7554 | RTSP streams. |
| 7888 | HLS streams. |
Using the ide_cli script of the project:
sudo ./ide_cli init   # create the data directory and pull the image
./ide_cli up          # start the library
./ide_cli down        # stop it
./ide_cli logs        # follow the logs
Or with Docker Compose, using the docker-compose.yml of the project:
docker compose up -d
ide_cli up finds the IP address of the machine on its own and uses it in the stream URLs. To use a different address
or host name, set VC_SERVER_HOST (see Settings). The library stores its data in
/var/local/stream-simulator, so your videos and tags are kept when the container is replaced.
Open the web interface in a browser:
http://<library-host>:7090
The Library Page
The page lists the media in the library, grouped into sections (see Organize with Tags). Each row shows:
| Item | Description |
|---|---|
| ID | The number of the stream. It is used in the stream URLs. |
| File Name | The name of the file, with a thumbnail, its tags, and its resolution and video codec. Click the name to play the original video. An Image badge marks a stream made from a picture. |
| Size, Duration | The size and length of the file. |
| HLS Stream | The HLS address. Click the play icon to watch the stream in the browser. |
| RTSP Stream | The RTSP address. Click it to copy it to the clipboard. |
| Information icon | The properties of the stream. |
| Tag icon | Edit the tags of the stream. |
| Number badge | How many RTSP clients are watching the stream now. The badge is green when at least one client, such as BrainFrame, is reading it, and gray when none is. |
| Arrow icon | Add this stream to BrainFrame. |
| Warning icon | The stream could not be verified. Point to it to see the reason. |
The stream addresses follow this pattern:
rtsp://<library-host>:7554/mocked_stream_<ID>
http://<library-host>:7888/mocked_stream_<ID>
Add Media
Upload a file
- Click Upload Media.
- Click Open and choose a file. Videos can be
.mp4or.avi. Pictures can be.jpg,.jpeg,.png,.webp,.bmpor.gif. - For a video from a fisheye camera, select Fisheye. The video is then flattened into six normal views.
- For a picture, set the clip length, from 2 to 300 seconds (default 10). The picture is turned into a video that loops, so the length only sets the size of one loop.
- Click Upload. A progress message is shown while the file is processed.
Spaces in the file name are replaced by underscores. A file with the same name as one already in the library is rejected. Pictures can be up to 25 MB, and a GIF uses only its first frame.
Every file is converted once, when it is added, into an MP4 video (H.264, with no B-frames and a key frame every two seconds), which suits RTSP clients and BrainFrame. The original file is kept.
You can also copy files into the resources folder in the data directory. The library checks that folder about once a
minute and publishes new files. It supports .mp4, .avi, .webm, .mkv, .mov, and the picture types above. If
you delete a file from the folder, its stream is removed.
Add media from a web address
- Click Add Media URL.
- Paste the address. YouTube, Google Drive, and Kaggle links are supported, as well as direct links to a video or a picture.
- For a picture, set the clip length. It is ignored for videos.
- Click OK.
The address is added to the active configuration (see Share a Library), and appears in the list as an entry that is not downloaded yet. Select the entry and click Fetch Media to download it. A progress message shows in its row, and the entry becomes a normal row when it finishes.
Bulk tagging and Add Videos to BrainFrame are not available for entries that are not downloaded yet.
Remove media
Select the rows and click Remove Selected Videos. This deletes the files and their streams.
Add Streams to BrainFrame
- Select one or more rows, and click Add Videos to BrainFrame. To add a single stream, click the arrow icon in its row.
- Check the list of streams. The dialog does not allow addresses that use
localhostor127.0.0.1, because BrainFrame would not be able to reach them. If you see this error, setVC_SERVER_HOSTto the address of the library machine, and restart the library. - Enter the BrainFrame OS Server Url. It starts as the address you used to open the library.
- Click Apply.
For each stream, the library creates an IP camera stream in BrainFrame, with the file name as the stream name and the RTSP address as its URL. It then starts analyzing the stream. The BrainFrame server must be reachable and be a compatible version, or an error is shown.
The library remembers which BrainFrame servers each stream was added to. Such streams are published all the time. Other streams start only when a client reads them, and stop after a period with no readers. The first connection to an idle stream can therefore take a few seconds.
You can also copy the RTSP address and add the stream by hand in the Web Client, or add many streams at once with REST API Apps.
Tip
Use the library to try the examples in other parts of this documentation without a camera. For example, add a traffic video, load capsules from the AI Marketplace, and then draw zones and create alarms.
Organize with Tags
Tags describe what a video shows, so that you can find a video for a use case. A tag has four parts:
Vertical | Category | Use Case | Asset & Events
For example, Transportation & Smart Cities | Traffic Flow & Congestion Management | Vehicle Counting & Classification.
The library groups rows into sections by their tag, and a video with several tags appears in each section.
The standard verticals are:
- Manufacturing & Industrial
- Retail & Hospitality
- Transportation & Smart Cities
- Enterprise & Smart Buildings
- Physical Security & Operations
You can also type your own values.
| Action | How |
|---|---|
| Tag one video | Click the tag icon in its row, choose or type the parts, click Add Tag, then Save. |
| Tag several videos | Select the rows, click Add Tags, choose the tag, and click Apply. |
| Remove tags | Click the x on a tag in the row, or select rows and click Remove Tags. |
| Save tags to a file | Click Export Config. A JSON file is downloaded. |
| Load tags from a file | Click Import Config. |
Select the box in a section header to select every row in the section.
Share a Library
The Media Sources button controls where the library gets its list of remote media from. This list is called a configuration seed. A seed is a shared file that lists media addresses and their tags, so that several people can use the same library without copying video files.
- Click Media Sources.
- Select Public configuration seed to use the public seed. Clear it to enter the address of your own seed.
- Click Pull config from seed. Choose the configuration from the list and click OK.
- Fetch the media you need with Fetch Media.
If you add addresses or change tags, the name of the active configuration is shown in red with "unsaved local changes". Click Push config back to seed to share your changes. Files that you uploaded from your computer are never part of a seed.
If you use YouTube, Google Drive, or Kaggle sources, the same dialog sets the credentials the library needs:
- Kaggle: your Kaggle user name and API key, from kaggle.com/settings/api.
- Google Drive: an OAuth client ID and secret, and then Connect Google Account.
Credentials are saved in the library. Use Clear Credentials or Disconnect to remove them.
When the public seed is active, the list is shown in a lighter, gray theme, and the watermark text is the public one. This makes it clear that you are not looking at your private library.
Settings
The library is configured with environment variables. With ide_cli, edit the variables at the top of the script.
With Docker Compose, edit the environment section.
| Variable | Description | Default |
|---|---|---|
VC_SERVER_HOST |
The address that is used in the stream URLs. Set it to the IP address or host name that BrainFrame and your browser use to reach the library. | The address of the machine (ide_cli) |
VC_SERVER_PORT |
The port of the web interface. | 7090 |
RTSP_PORT |
The port of the RTSP streams. | 7554 |
HLS_PORT |
The port of the HLS streams. | 7888 |
TITLE |
The title at the top of the page. | Use Case Library |
WATERMARK_TEXT |
The text that is drawn faintly over the list. | A confidentiality notice |
PUBLIC_WATERMARK_TEXT |
The watermark that is used while the public seed is active. | CONNECTED TO PUBLIC MEDIA SOURCES. |
If you change a port, also change the matching port mapping of the container.
Troubleshooting
The Apply button is disabled in the Add to BrainFrame dialog.
A stream address contains localhost or 127.0.0.1. Set VC_SERVER_HOST to the machine's network address and
restart the library.
BrainFrame cannot open the stream. Check that the BrainFrame server can reach the library on port 7554, and that no firewall blocks it. Open the RTSP address in VLC to test it. A warning icon in the row means the library could not verify the stream. Point to it to see why.
An upload is rejected. A file with the same name may already be in the library, or the file type is not supported.
A video is slow to appear. The library converts each new video once. Large files, and fisheye videos, take longer.
Talkdown.ai
The Talkdown.ai App (also called the Alert Reaction App) connects to your BrainFrame server and turns BrainFrame alarms into real-world actions. When an alarm triggers, it can send email alerts, play sounds and voice messages, and fetch video clips from your network video recorder (NVR).
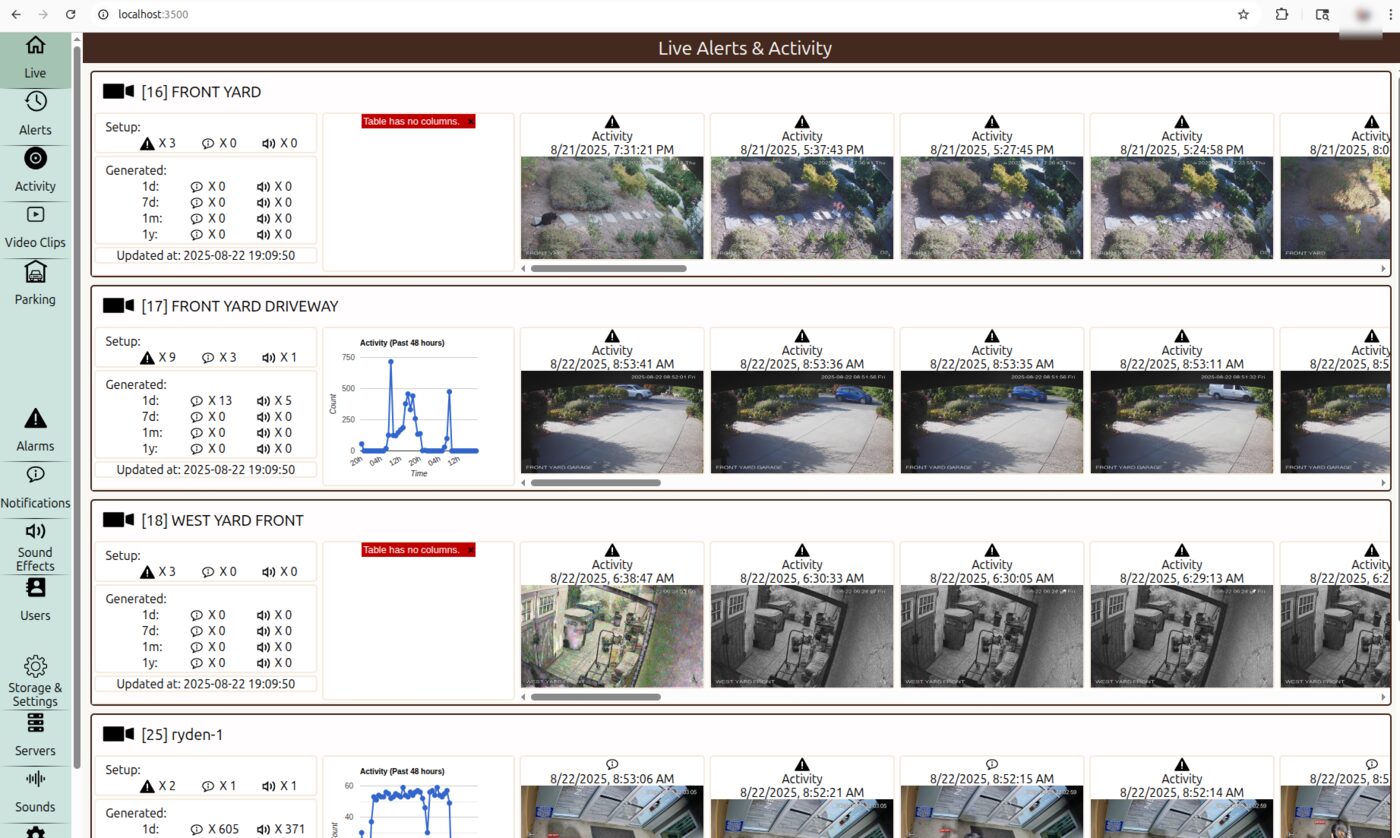
To open the Talkdown.ai App, type the IP address of the BrainFrame OS server in a browser to open the BrainFrame Web Client. Once connected, click the Developer button at the bottom left to bring up the Developer References menu, then click Talkdown.ai App.
Note
Before you use the app, install and configure BrainFrame and the Talkdown.ai App by following the deployment guide.
Open the app at http://<your-server-ip>:3500. The tabs on the left are described below. They fall into three groups:
monitoring, alarm reactions, and system configuration.
Monitor
Live
The Live tab is the main dashboard. It gives a real-time overview of the activity, notifications, and sound effects for each of your camera streams.
Alerts
The Alerts tab is the log of every alert that was triggered, with all of its notifications and sound effects. Filter by camera, reaction type, and date to look into a specific event.
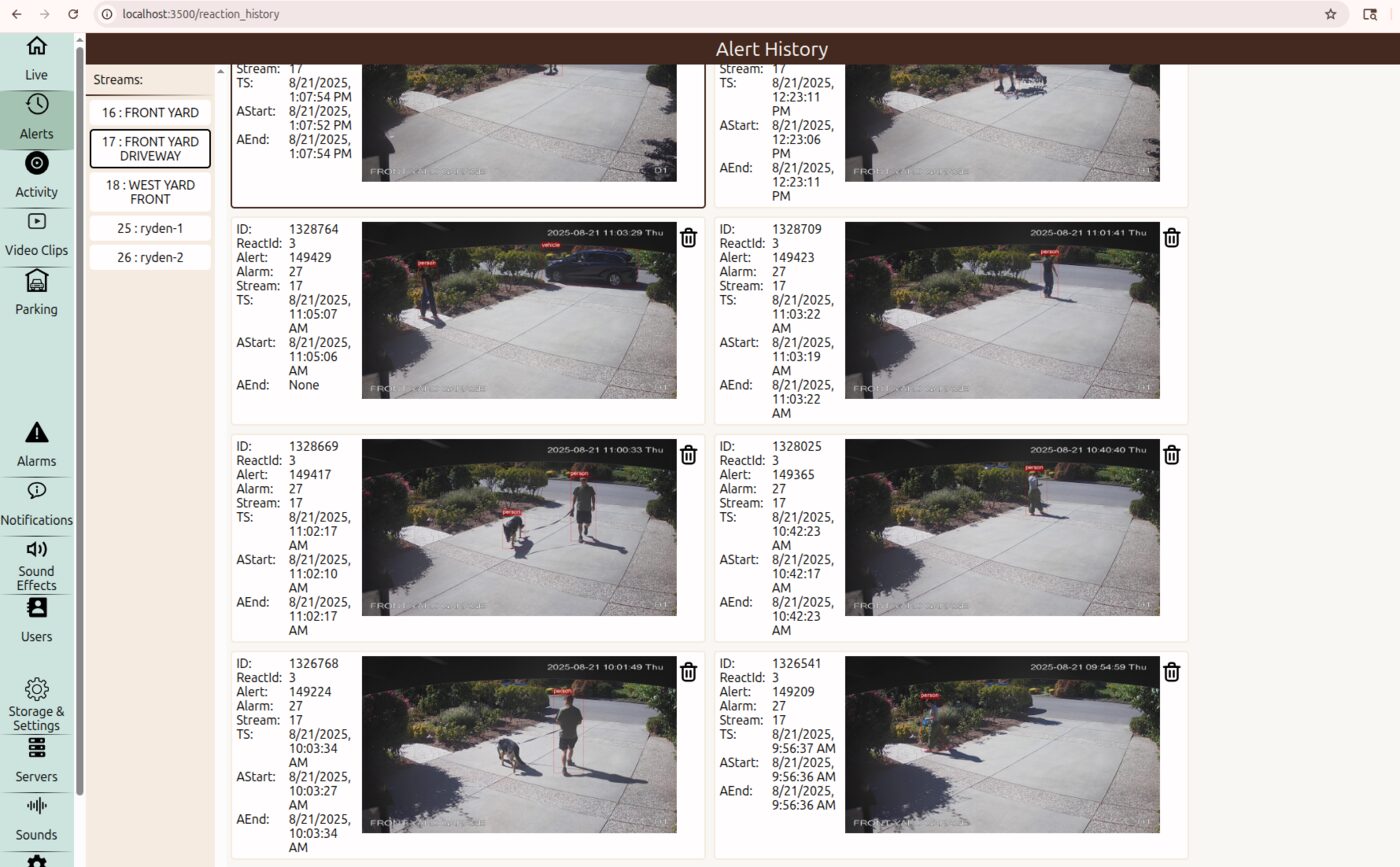
Activity
The Activity tab shows every event that BrainFrame detected, such as an object entering or leaving a zone, including events that did not trigger a reaction. Use it to review everything the system has seen.
Video Clips
The Video Clips tab lists the video segments recorded from your NVR when an alert was triggered. To use it, set up the recorder in Config NVR.
Parking
The Parking tab lets you upload a map of a parking lot and mark individual parking spaces to monitor their status. See Maps & Locations.
Set Up Reactions
Alarms
The Alarms tab is where you connect a BrainFrame alarm to the actions you want. Each row is an alarm from BrainFrame. Click the plus (+) button on a row to add one or more notifications or sound effects to it. The row expands to list them, and you can edit or delete each one.
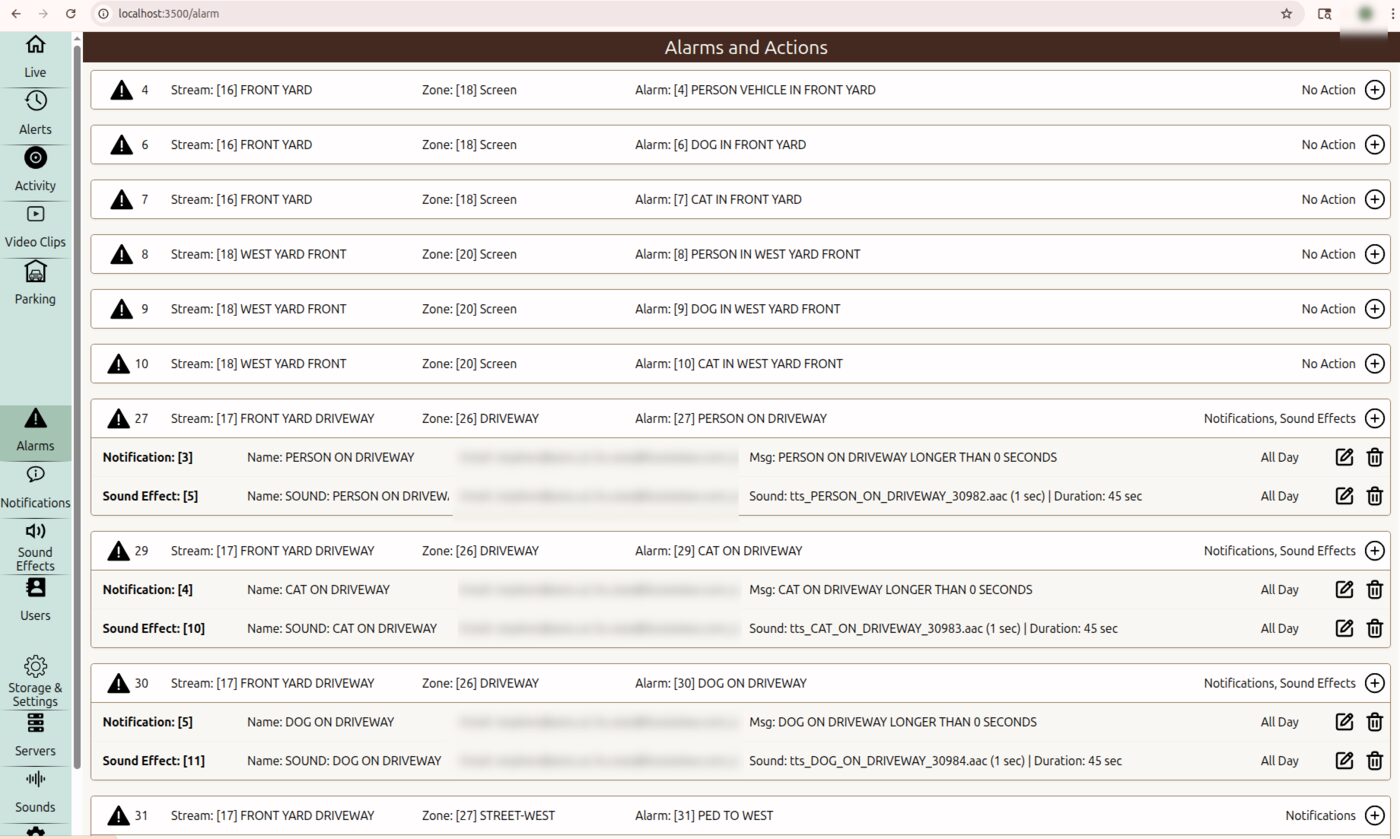
Alarms are created in BrainFrame. See Alarms.
Notifications and Sound Effects
You create notifications and sound effects from the Alarms tab. The Notifications and Sound Effects tabs list every action that you configured, across all alarms.
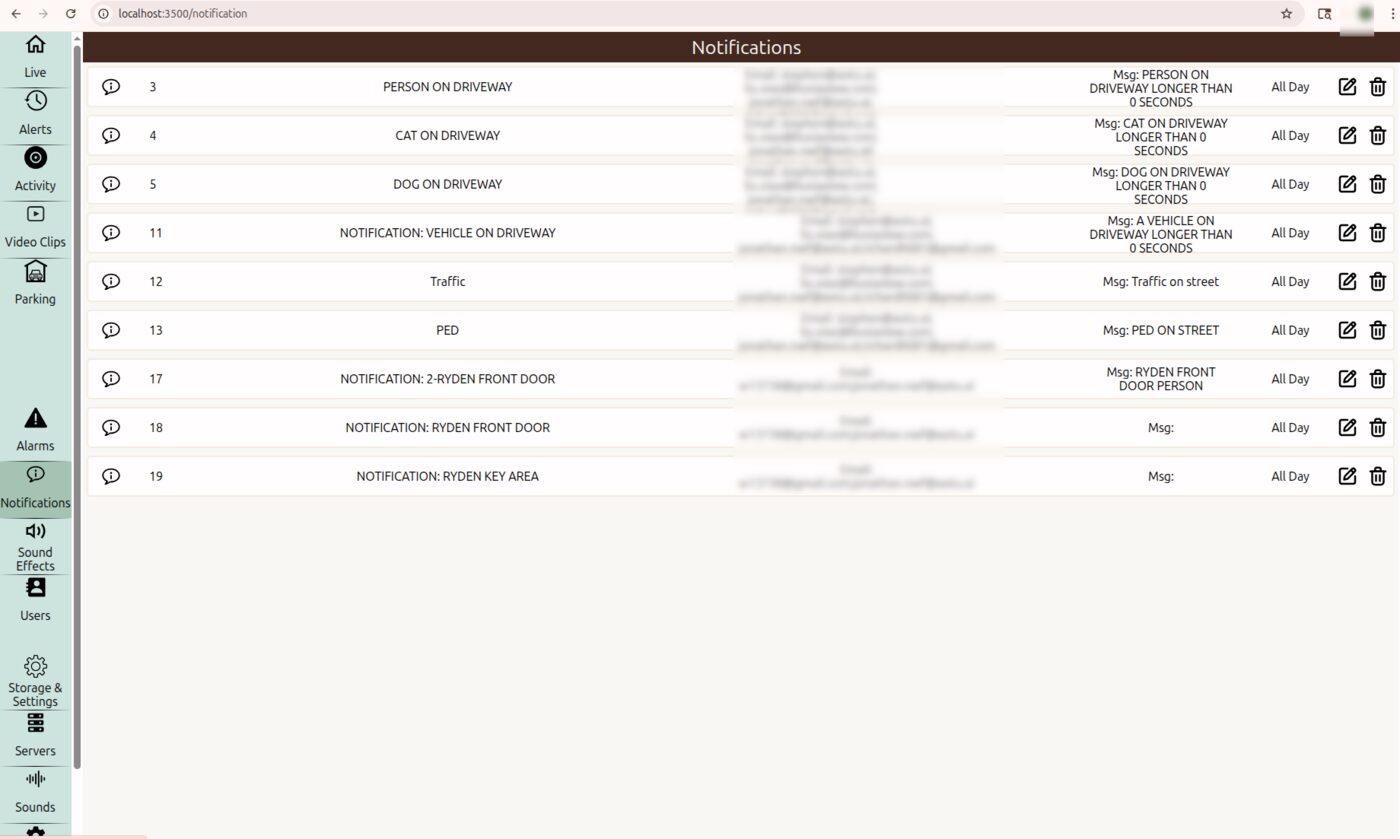
For a four-stage notification and deterrence workflow, see AWDE Four-Stage Deterrence.
Users
The Users tab is a directory of contacts, with names, phone numbers, and email addresses. You can select these contacts as the recipients of notifications.
Sounds
The Sounds tab is the library of audio clips. Upload your own sound files, such as a warning message, or use text-to-speech to generate audio from text. Sound effects play these clips. See Config Sound and Voice Alerts for SOC.
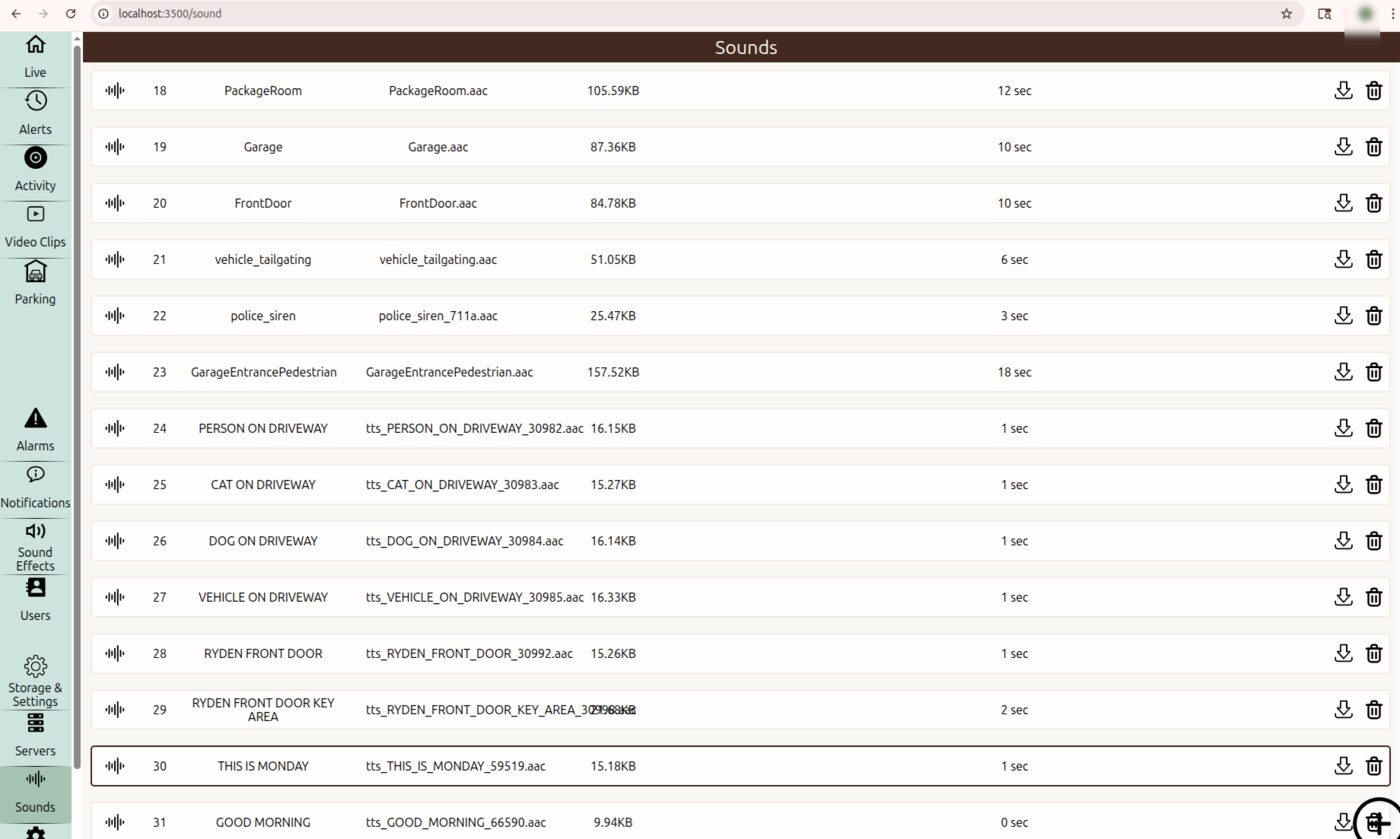
Configure the System
Storage & Settings
The Storage & Settings tab holds the system-wide settings.
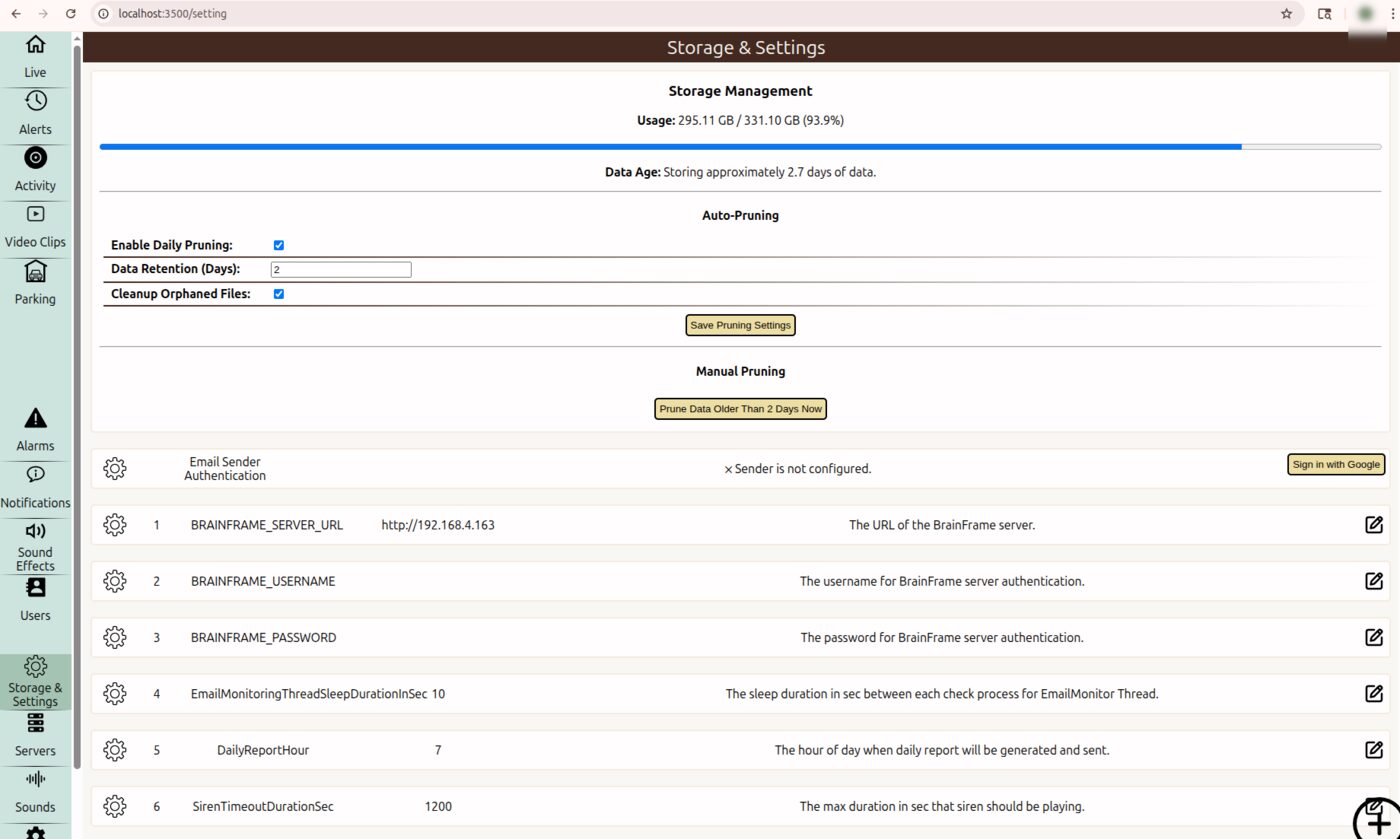
- Storage management and auto-pruning: shows the disk use and how many days of data are kept. Turn on daily pruning, set the number of days of data to keep, and choose whether to clean up orphaned files. You can also prune old data immediately. See Maintenance.
- Site name: set a unique site name. It is used as the prefix of the subject line of every email.
- Video recorder: if you have an NVR, set its IP address and model. See Config NVR.
- Volume: set the master volume for each type of audio, such as sirens and voice announcements.
- Email sender: you must authorize the app to send email. See below.
Authorize email sending
-
Click Sign in with Google. A new browser tab opens and asks you to choose an account.
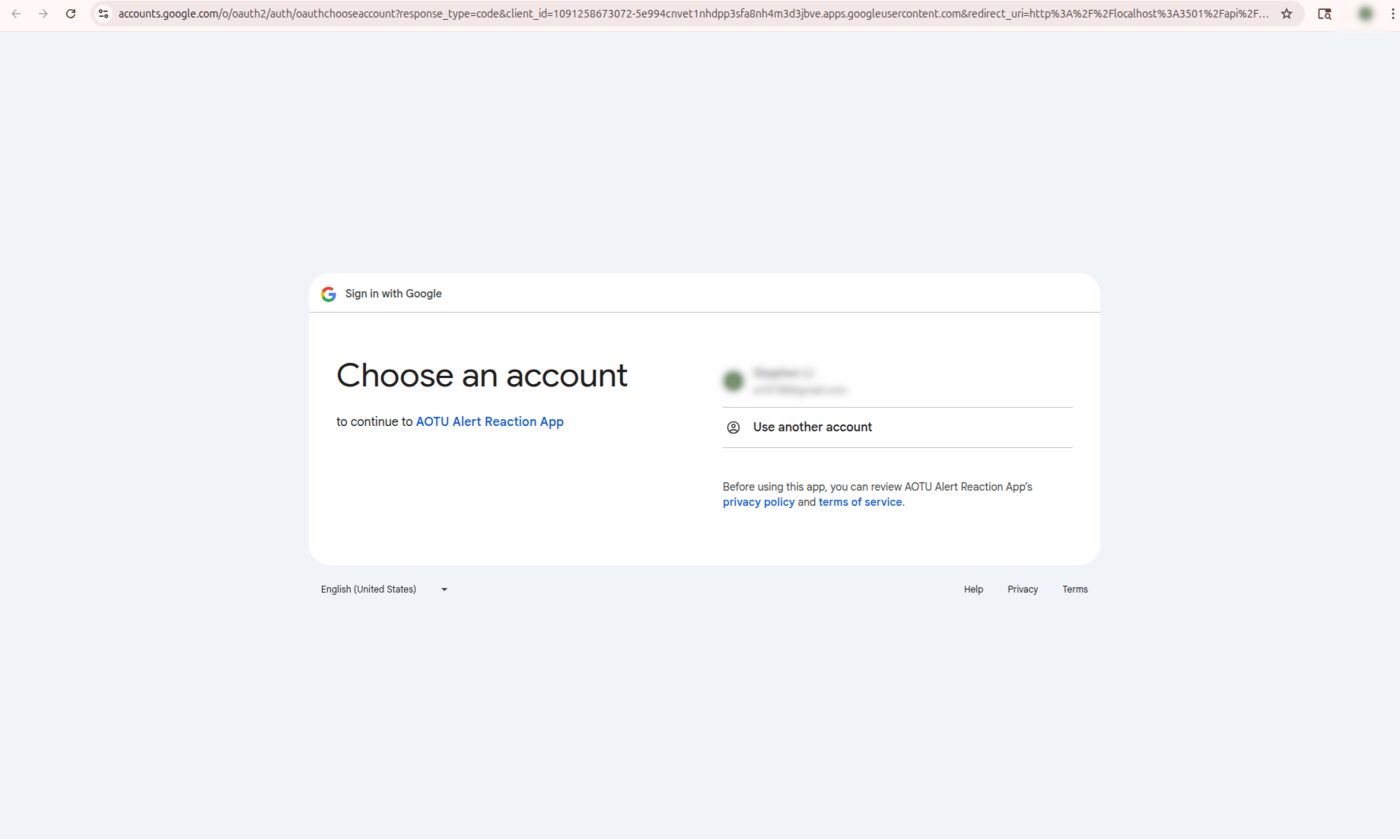
-
Google asks for permission to read, compose, and send email from your Gmail account, and to view and manage Pub/Sub topics and subscriptions. Click Allow.
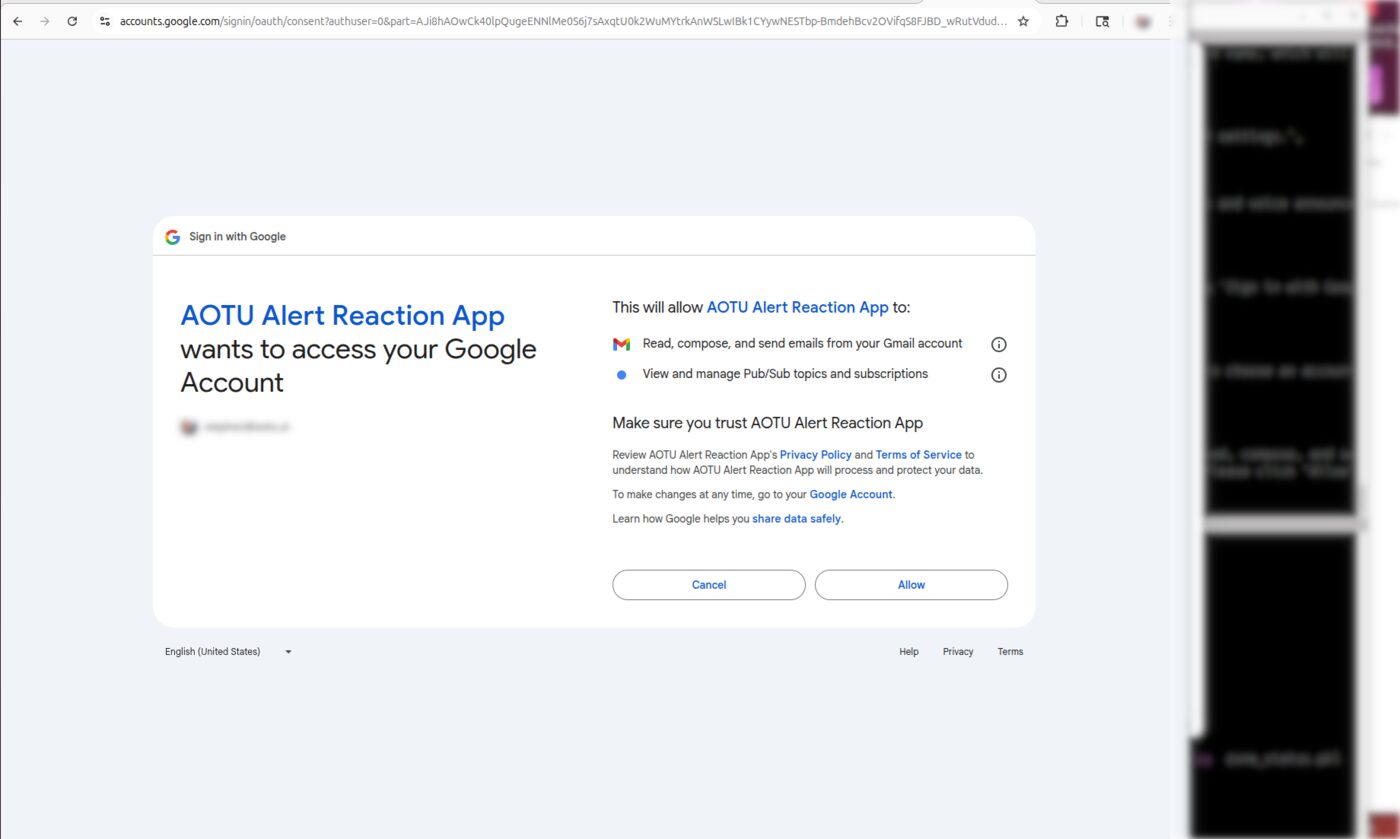
-
A page confirms that authentication was successful. Close the tab.
Warning
Complete the authorization on the server itself, using http://localhost:3500. If you do it from another computer,
Google shows an "Access blocked" error. For the files you need first, see Prepare
and Config Gmail.
When it succeeds, the status changes to Sender is configured and ready. Use Re-authorize if the credentials expire. Use Sign out to disconnect the account. You are asked to confirm first.
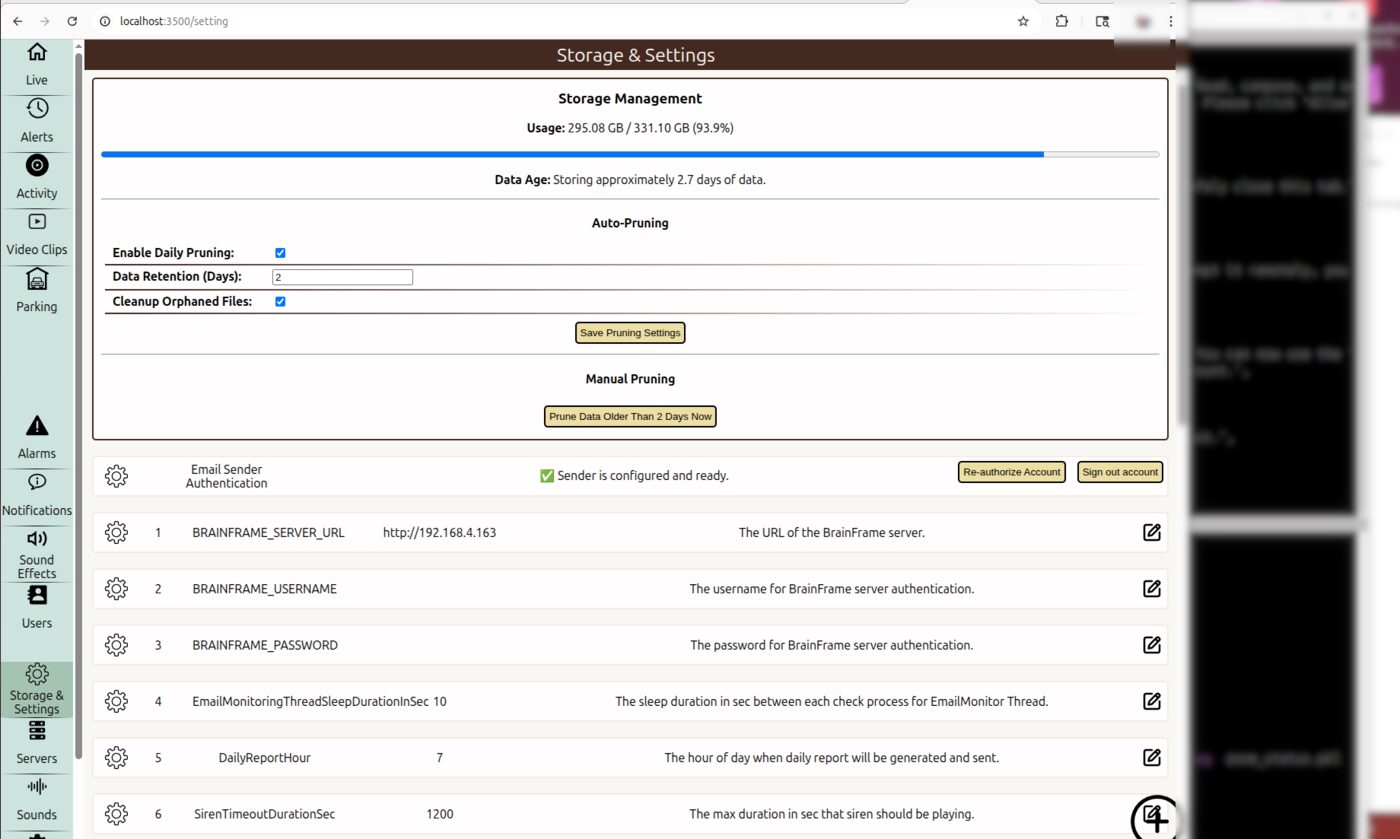
Servers
The Servers tab sets the addresses of the Alert Reaction backend and your BrainFrame server, and shows the state of each connection. See Connect to BrainFrame Server.
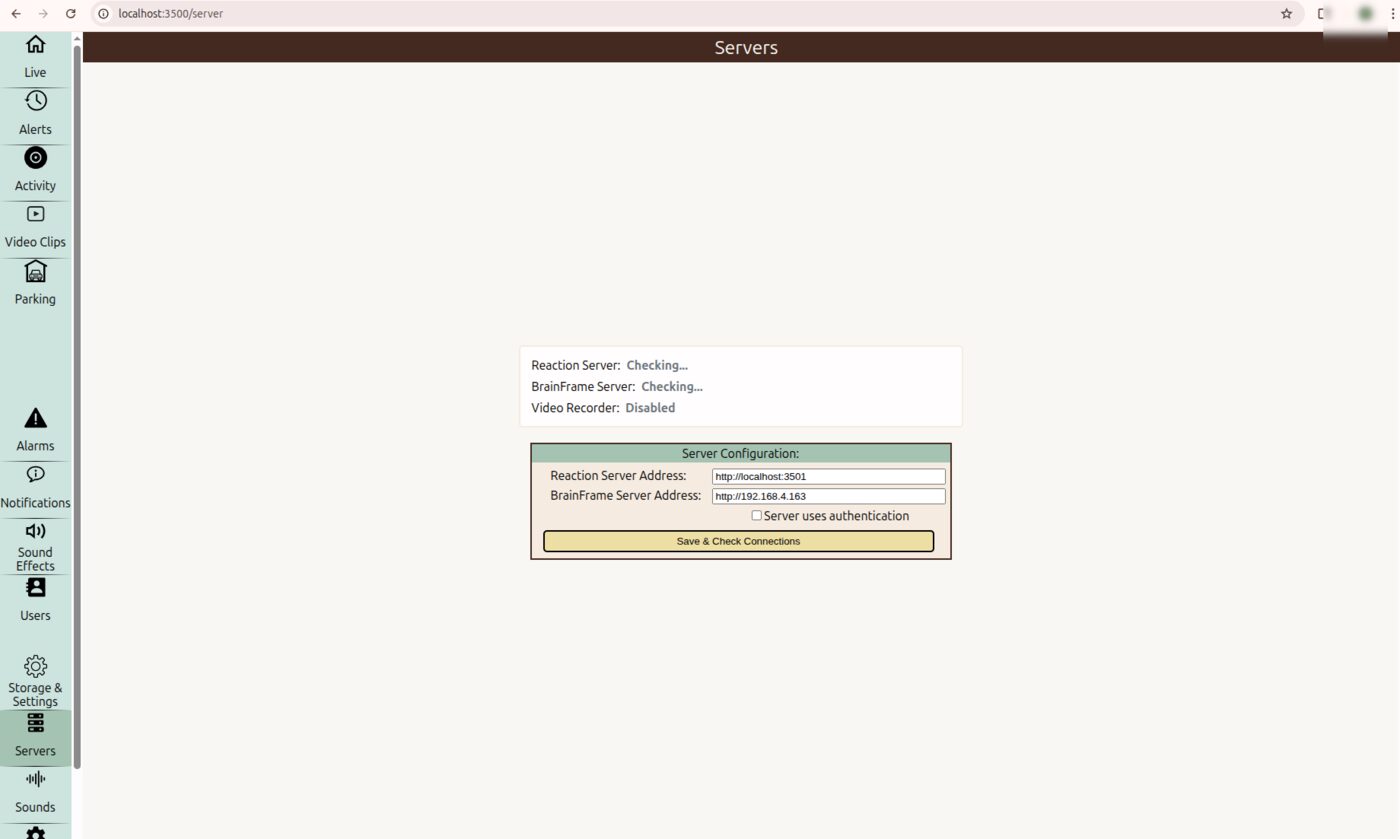
Language
Switch the user interface between English and Chinese.
Licenses
Lists the licenses of the open-source libraries that the app uses.
Introduction
To open the Dashboard, type the IP address of the BrainFrame OS server in a browser to open the BrainFrame Web Client. Once connected, click the Developer button at the bottom left to bring up the Developer References menu, then click Dashboard.
BrainFrame uses a powerful dashboarding tool called Grafana in order to allow highly customizable realtime visualizations of the BrainFrame Database and API.
With a little SQL knowledge it is possible to quickly get analytics for any specific problem you need solved.
The default login / pass for the dashboard is admin, admin.
Dashboards
A Dashboard contains various Panels which visually display information about
the BrainFrame database. BrainFrame populates automatically with dashboards, such
as the Stream Uptime dashboard, which shows graphs of which cameras are being
processad and when they have been connected / disconnected.
Creating a Graph
First, create a dashboard by clicking the + on the sidebar. Then, give your dashboard a name by clicking the gear icon on the top right.
Now, it's time to add a Panel. Click the graph icon on the top bar, so you see this:

Let's start by adding a query. Click "Add Query", then click the pencil to edit the query as SQL.

For an example query, the following query will give a simple graph of the number of people who entered or exited the "Front Door" Zone over time
SELECT zone_status.tstamp as time,
       total_count.count_enter AS entered,
      total_count.count_exit AS exited FROM zone_status
LEFT JOIN total_count ON total_count.zone_status_id=zone_status.id
LEFT JOIN zone ON zone_status.zone_id=zone.id
WHERE
  total_count.class_name='person' AND
  zone.name='Front Door' AND
  zone_status.id >= (SELECT id FROM zone_status WHERE tstamp >= $__unixEpochFrom() ORDER BY tstamp ASC LIMIT 1) AND
  zone_status.id <= (SELECT id FROM zone_status WHERE tstamp < $__unixEpochTo() ORDER BY tstamp DESC LIMIT 1)
You might notice that the last two lines of the query are fairly complicated. These lines
are intended to allow the query to limit results only to results between two timestamps,
and to do so in a very efficient way. The macros $__unixEpochFrom() and $__unixEpochTo()
retun the current timestamps that the dashboard user is currently requesting.
Thus, feel free to copy paste the following filter into any slow query in order to limit results in a SQL efficient way:
WHERE
  zone_status.id >= (SELECT id FROM zone_status WHERE tstamp >= $__unixEpochFrom() ORDER BY tstamp ASC LIMIT 1) AND
  zone_status.id <= (SELECT id FROM zone_status WHERE tstamp < $__unixEpochTo() ORDER BY tstamp DESC LIMIT 1) AND
  "< ANY OTHER CONDITIONALS FOR THE QUERY >"
BrainFrame CLI
The BrainFrame Command Line Interface (CLI) is used to install, update, and manage the lifecycle of the BrainFrame
server and system. Its command, brainframe, starts and stops the BrainFrame server, and manages other related
controls.
Command Structure
The command is structured as
brainframe [Sub-Command] [Arguments]
To view a list of sub-commands, you can use
brainframe --help
To view help for a specific sub-command, you can use
brainframe [Sub-Command] --help
Using Tools with a Remote Server
The tools that talk to a BrainFrame server, such as brainframe-apps and brainframe-sys-tools, assume that the
server is running on the same machine. If the server is on another machine, give its address with
--server-url SERVER_URL.
Command: brainframe
The BrainFrame server consists of several smaller microservices, which are containerized using Docker. The
lifecycle and control of those services are delegated to Docker Compose, which orchestrates the containers. The
brainframe command installs the server, starts and stops it, updates it, backs up its data, and removes it.
brainframe <command> [options]
| Command | Purpose |
|---|---|
install |
Install the BrainFrame server. |
compose |
Start, stop, and inspect the server using Docker Compose. |
update |
Update the server to a new version. |
info |
Show where BrainFrame is installed and which version it is. |
backup |
Back up the server's data. |
uninstall |
Remove the server. |
shell |
Open a shell that has the BrainFrame command line tools. |
self-update |
Update the CLI itself, when it was installed as a standalone binary. |
For instructions on the installation of the CLI, please refer to our getting started guide. To update the CLI to the latest version, run:
sudo -H pip3 install --upgrade brainframe-cli
Note
The latest version of the CLI needs Python 3.10 or newer. On a system with an older Python, such as Ubuntu 20.04,
pip installs the newest older version of the CLI instead.
Permissions
install,backup, anduninstallmust be run as root, for example withsudo.composeandupdateneed permission to use Docker. This means being root or a member of thedockergroup.updatealso needs write access to the install directory, which is given to thebrainframegroup, so usesudoor be a member of that group.- If you installed the CLI with
pipas a regular user,sudo brainframemay not find it. Usesudo $(which brainframe)instead.
The installer can add your user to the docker and brainframe groups. Log out and back in, or reboot, for the
change to take effect.
Install location and data location
BrainFrame uses two directories:
| Directory | Contents | Default | Environment variable |
|---|---|---|---|
| Install path | docker-compose.yml and its related configuration, such as .env |
/usr/local/share/brainframe |
BRAINFRAME_INSTALL_PATH |
| Data path | The data that the server writes at runtime: the database, stored files, and capsules | /var/local/brainframe |
BRAINFRAME_DATA_PATH |
If you install to custom locations, brainframe install prints export lines for these variables. Add them to your
~/.bashrc, so that later brainframe commands can find the installation. Because sudo does not pass environment
variables on, use sudo -E when a command needs them. To print the locations in use, run brainframe info.
install
Installs the BrainFrame server. It downloads the server's docker-compose.yml, downloads the server's Docker images,
and offers to start the server.
sudo brainframe install
With no options, the installer asks about each setting. It can install Docker if it is missing, add your user to the
docker and brainframe groups, and choose the install and data directories.
To install without questions, for example in a script, give any option. The command then runs non-interactively, and anything you leave out takes its default value.
sudo brainframe install --noninteractive --version v0.31.16
| Option | Description |
|---|---|
--noninteractive |
Do not ask questions. |
--version VERSION |
The version to install, such as v0.31.16, or latest. Default: latest. |
--install-path PATH |
Where to install the docker-compose.yml. Default: /usr/local/share/brainframe. |
--data-path PATH |
Where the server writes its data. Default: /var/local/brainframe. |
--install-docker |
Install Docker if it is not present. |
--add-to-group |
Add the current user to the brainframe group. |
--add-to-docker-group |
Add the current user to the docker group. |
Note
Installing Docker automatically is only offered on operating systems that the CLI officially supports. On other systems, install Docker first by following the instructions in Get BrainFrame.
compose
Runs a Docker Compose command on the BrainFrame installation. It can be run from any directory. Everything after
compose is passed to Docker Compose, using the installed docker-compose.yml, the docker-compose.override.yml
and .env files if they exist.
Starting the server
brainframe compose up -d
If you remove the -d flag, it will attach the logs stream to your terminal,
and allow you to close the server when you Ctrl+C.
Stopping the server
brainframe compose down
Restarting the server
brainframe compose restart
To apply changes to docker-compose.override.yml or .env, stop the server with brainframe compose down, and then
start it again with brainframe compose up -d.
Streaming logs
To view all logs, run:
brainframe compose logs -f
To view logs just for the core service, run:
brainframe compose logs -f core
Other commands
Any Docker Compose command works, for example brainframe compose ps to list the services, or
brainframe compose exec database psql -U user -d brainframe to open a database shell.
Note
brainframe compose down adds the --volumes flag for you, which also removes the Docker volumes defined by
BrainFrame. The server's data is kept in the data path on the host, and is not deleted. To stop the server
without removing the volumes, add --except-volumes.
update
Updates the server to a new version. It downloads the new docker-compose.yml, downloads the new Docker images, and
then offers to restart the server to apply the update.
sudo brainframe update
To update to a specific version:
sudo -E brainframe update --version v0.31.16
If you give any option, the command runs non-interactively, so add --restart to restart the server when the update
finishes. Without --restart, the new version starts the next time that you stop and start the server.
sudo brainframe update --restart
| Option | Description |
|---|---|
--version VERSION |
The version to update to, or latest. Default: latest. |
--restart |
Restart the server after the update, in non-interactive mode. |
--noninteractive |
Do not ask questions. |
-f, --force |
Install the requested version even if it is the same as, or older than, the installed version. |
Warning
Downgrading BrainFrame is not supported, and can cause data loss or instability when the data was written by a
newer version. Back up your data first with brainframe backup.
Early access partners can download from the staging server by setting the BRAINFRAME_STAGING=yes,
BRAINFRAME_STAGING_USERNAME, and BRAINFRAME_STAGING_PASSWORD environment variables.
info
Shows where BrainFrame is installed and which version is installed.
brainframe info
install_path: /usr/local/share/brainframe
data_path: /var/local/brainframe
server_version: v0.31.16
To print only one value, name the field. This is useful in scripts:
brainframe info install_path
brainframe info data_path
brainframe info server_version
backup
Backs up the server's data directory. The server must be stopped for the backup, so the command stops it first.
sudo brainframe backup
By default, the backup is saved in a new directory named with the current date and time, under backups in the data
path, for example /var/local/brainframe/backups/2026-01-31_10-30-00. The backups directory itself is not copied.
To save the backup in another location, for example on an external drive:
sudo brainframe backup --destination /mnt/backup/brainframe-2026-01-31
The backup uses rsync, which is installed on most systems. Use --install-rsync if it is missing.
| Option | Description |
|---|---|
--destination PATH |
The directory to save the backup in. |
--noninteractive |
Do not ask for confirmation before stopping the server. |
--install-rsync |
Install rsync if it is missing. |
Note
The server is not restarted after the backup. Start it again with brainframe compose up -d.
uninstall
Removes the BrainFrame server. It stops the server, deletes the server's Docker images, and deletes the install directory. It does not remove the CLI itself.
sudo brainframe uninstall
By default, the data path is kept. To also delete the data the server has produced, answer yes when asked, or use
--delete-data.
| Option | Description |
|---|---|
--delete-data |
Also delete the data path, including the database and any backups saved in it. This cannot be undone. |
--noninteractive |
Do not ask for confirmation. |
Warning
With --noninteractive, the command does not ask you to confirm. Use --delete-data only when you are sure that
you no longer need the data.
shell
Opens a shell in a Docker container that has the BrainFrame command line tools installed, such as
brainframe-apps and
brainframe-sys-tools. You do not need to install the tools with pip.
brainframe shell
Your current directory is mounted in the container at /host, which is also the starting directory, so the files you
create there are saved on your machine. The container is removed when you exit the shell. Docker must be installed
and your user must be allowed to use it.
self-update
Updates the CLI itself. This is only for the standalone binary version of the CLI. If you installed the CLI with
pip or a package manager, update it with that tool instead.
brainframe self-update
Dev Tools ↵
brainframe-onvif-tools
brainframe-onvif-tools finds IP cameras and network video recorders (NVRs) on your local network, retrieves
their details through the ONVIF protocol, and checks that their RTSP video streams can be
opened. The result is a config.csv inventory file that brainframe-apps can use to add all
of the cameras to BrainFrame in one step.
It is designed for bulk setup on Linux. For adding a single camera by hand, see Connecting to IP Cameras.
Installation
pip install brainframe-onvif-tools
Requirements
- Python 3.9 or newer (tested on Python 3.10).
ffprobe, which is part of FFmpeg, for thevalidatecommand. On Ubuntu, install it withsudo apt install ffmpeg.- The machine must be on the same network as the cameras.
Commands
| Command | Purpose |
|---|---|
discover |
Find ONVIF devices on the network and write their addresses to config.csv. |
scan |
Log in to each discovered device and read its manufacturer, model, serial number, and stream details. |
validate |
Confirm that each RTSP stream opens, fill in the RTSP URL and credentials, and take a snapshot. |
fix |
Apply per-model stream pipeline patches to config.csv. |
update-ip |
Update camera IP addresses in a BrainFrame settings file after the cameras' addresses change. |
All commands are run as brainframe-onvif-tools <command> [options]. To see the options of a command, run
brainframe-onvif-tools <command> --help.
Typical Workflow
# 1. Find the cameras on the network
brainframe-onvif-tools discover --auto

# 2. Log in to each camera and read its details
brainframe-onvif-tools scan

# 3. Verify the RTSP streams and take snapshots
brainframe-onvif-tools validate

# 4. Add the cameras to BrainFrame
brainframe-apps add-stream --stream-urls config.csv
Run the commands from the same directory every time. They read and write config.csv,
camera_onvif_info.json, and credentials.txt in the current directory by default. To use a different directory,
set the APP_HOME environment variable.
discover
Finds ONVIF-capable devices and writes their addresses to config.csv.
brainframe-onvif-tools discover
When run without options, the command shows a menu of discovery methods and the network interfaces it found. Choose one or more, separated by commas. Press Enter to accept the default, WS-Discovery.
To run without prompts, use --auto. This runs WS-Discovery, SADP discovery for Hikvision cameras, and a scan of
every local subnet:
brainframe-onvif-tools discover --auto
To also scan a specific subnet, for example one that is not directly attached to this machine:
brainframe-onvif-tools discover --subnet 192.168.20.0/24 --subnet 192.168.30.0/24
| Option | Description |
|---|---|
--auto |
Run WS-Discovery, SADP discovery, and scan all local subnets, with no prompts. |
--subnet CIDR |
Also scan this subnet, for example 192.168.1.0/24. Can be given more than once. |
--output OUTPUT |
The file to write. Default: config.csv. |
If config.csv already exists, it is renamed to config.csv.old before the new file is written. Any earlier
config.csv.old is replaced. Keep a copy of the file if you need to retain more than one previous version.
You can edit config.csv after this step to remove devices that you do not want to scan or add to BrainFrame.
scan
Contacts each device in config.csv over ONVIF, trying the device's ports and a short list of credentials, and
records what it finds.
brainframe-onvif-tools scan
For each device, the command tries the following, in order:
- The credentials listed in
credentials.txt, oneusername,passwordpair per line. - Anonymous access.
On first use, the command creates a credentials.txt file in the current directory. Edit it to list the credentials
that your cameras use.
Warning
Keep credentials.txt short, with at most three entries. The scanner tries each entry in turn, and some cameras
lock out an address after several failed logins.
If all of your cameras use the same login, you can supply it on the command line instead. In that case, only this login is tried:
brainframe-onvif-tools scan --user admin --password PASSWORD
To check a single camera and print everything the camera reports as JSON, without reading or changing config.csv:
brainframe-onvif-tools scan --host 192.168.1.10 --user admin --password PASSWORD
| Option | Description |
|---|---|
--host HOST |
Scan one device, for example 192.168.1.10, and print the result. Does not use config.csv. |
--user USER |
Use only this username, instead of the entries in credentials.txt. |
--password PASSWORD |
The password for --user. Required when --user is given. |
--input INPUT |
The device list to read and update. Default: config.csv. |
--output OUTPUT |
The file to save detailed ONVIF information to. Default: camera_onvif_info.json. |
--sort-by-serial-number |
Sort the results by serial number instead of IP address. |
--debug |
Print detailed error messages. |
The command updates each device's row in config.csv with its credentials, manufacturer, model, serial number,
audio capabilities, video encoding settings, system time, and on-screen display (OSD) text. It also saves the full
details of every device to camera_onvif_info.json.
validate
Confirms that each camera's RTSP streams can be opened, records the working RTSP URL in config.csv, and saves a
snapshot of each camera.
brainframe-onvif-tools validate
validate reads camera_onvif_info.json, so run scan first. It uses the credentials found by scan. To use a
different login for all cameras, use --user and --password.
| Option | Description |
|---|---|
--input INPUT |
The config.csv file to update. Default: config.csv. |
--json_file JSON_FILE |
The ONVIF inventory file to read and update. Default: camera_onvif_info.json. |
--snapshot-dir SNAPSHOT_DIR |
The directory for snapshots. Default: snapshots. |
--skip-snapshots |
Do not take snapshots. |
--user USER |
Use this username instead of the credentials found by scan. |
--password PASSWORD |
The password for --user. Required when --user is given. |
--model-csv MODEL_CSV |
A table of known camera models and their RTSP URLs. Default: the file in the current directory, otherwise the one included with the package. |
--override |
When a camera's manufacturer and model are in the model table, replace the RTSP URL in config.csv with the one from the table, even if a working URL was already found. |
The validate command also updates the results in camera_onvif_info.json. After it finishes, config.csv
contains the validated RTSP URL, with the credentials embedded, for each camera that passed.
fix
Some camera models need a custom video pipeline to stream reliably. The fix command applies these settings from a
patch file to the matching cameras in config.csv. The settings are stored in the json column and are applied to
the stream when brainframe-apps add-stream adds it.
brainframe-onvif-tools fix --dry-run
brainframe-onvif-tools fix
The patch file, onvif_patches.json by default, is a list of patches. Each patch matches cameras by manufacturer and
model. In the pipeline, {url} is replaced by the camera's RTSP URL:
[
  {
    "manufacturer": "HIKVISION",
    "model": "DS-2CD2342WD-I",
    "onvif_patch": {
      "pipeline": "rtspsrc location=\"{url}\" latency=2000 protocols=tcp ! queue ! rtph264depay name=\"buffer_src\" ! h264parse ! avdec_h264 ! videoconvert ! video/x-raw,format=BGR ! appsink name=\"main_sink\""
    }
  }
]
| Option | Description |
|---|---|
--patch PATCH |
The patch file. Default: onvif_patches.json. |
--input INPUT |
The config.csv file to update. Default: config.csv. |
--dry-run |
Show which cameras would be updated, without changing the file. |
update-ip
Cameras that get their address from DHCP can change IP address. After you run discover again, use update-ip to
update the addresses in a BrainFrame settings file saved with brainframe-apps save-settings, so that the saved
streams point to the cameras' new addresses.
brainframe-onvif-tools update-ip --dry-run
brainframe-onvif-tools update-ip
The command compares the new config.csv with the previous config.csv.old that discover created. Cameras are
matched by serial number when it is known, and otherwise by unchanged IP address. The mapping is saved to
ip_changes.json, and the addresses in the settings file are replaced.
For the best results, run scan and validate after each discover, so that serial numbers are available.
| Option | Description |
|---|---|
--input INPUT |
The new device list. Default: config.csv. |
--old OLD |
The previous device list. Default: the input file name with .old appended, for example config.csv.old. |
--mapping MAPPING |
Where to save the IP address mapping. Default: ip_changes.json. |
--settings SETTINGS |
The BrainFrame settings file to update. Default: settings.json. |
--skip-compare |
Do not compare the lists. Use the existing mapping file. |
--dry-run |
Show what would change, without changing the file. |
The config.csv File
config.csv is a text file with one camera per line. The tags on the first and last lines tell brainframe-apps
which actions to apply to the cameras:
<add_stream, load_settings, start_analyzing>
# ip:port,username,password,manufacturer,model,serial_number,audio_in,audio_out,auth_required,encoding,width,height,framerate,bitrate,system_datetime,rtsp_url,osd,json
192.168.1.10:80,admin,PASSWORD,HIKVISION,DS-2CD2342WD-I,ABC123456,yes,no,yes,h264,1920,1080,30,4096,,rtsp://admin:PASSWORD@192.168.1.10:554/Streaming/Channels/101,Front Door,
</>
| Column | Description |
|---|---|
ip:port |
The camera's address and ONVIF port. |
username, password |
The credentials found by scan. |
manufacturer, model, serial_number |
Read from the camera. |
audio_in, audio_out |
Whether the camera has an audio input or output. |
auth_required |
Whether the camera requires a login. |
encoding, width, height, framerate, bitrate |
The main stream's video settings. |
system_datetime |
The camera's clock when it was scanned. |
rtsp_url |
The RTSP URL, with credentials. Set by validate. |
osd |
The camera's on-screen display text. brainframe-apps add-stream uses it as the stream name. |
json |
Stream options, such as a custom pipeline. Set by fix, or edit it by hand. |
Lines that start with # or < are ignored when streams are added.
Warning
config.csv, credentials.txt, and camera_onvif_info.json contain camera passwords in plain text. Restrict
access to them and do not share them.
Troubleshooting
discover finds no devices.
Run discover --auto and check that the machine is on the same network as the cameras. If the cameras are on another
subnet, add it with --subnet. Some cameras have ONVIF turned off by default. Enable it in the camera's settings.
scan reports that no working ONVIF port was found.
Check that ONVIF is enabled on the camera, and that the credentials are listed in credentials.txt or given with
--user and --password. Some cameras need a separate ONVIF account. Run with --debug for more detail.
validate reports that ffprobe is not installed.
Install FFmpeg, for example sudo apt install ffmpeg.
validate reports that a stream was rejected.
Check the camera's password, and that the camera's RTSP service is enabled. Then run validate again. If the camera's
manufacturer and model appear in the model table, try --override.
brainframe-apps
brainframe-apps is a set of command line tools that manage a BrainFrame server through its REST API. Use it to
add and remove streams, start and stop analysis, manage zones, alarms, and capsules, process images, read live zone
statuses, and back up or restore the server's configuration. Because it uses the REST API, it can manage a server on
the same machine or on another machine.
Installation
pip install brainframe-apps
Requires Python 3.9 or newer (tested on Python 3.10).
Usage
brainframe-apps <command> [options]
To list the options of a command, run brainframe-apps <command> --help.
Commands
| Command | Purpose |
|---|---|
add-stream |
Add IP camera streams or a video file to BrainFrame. |
delete-stream |
Delete streams from BrainFrame. |
list-stream |
List the streams on the server. |
start-analyzing |
Start AI analysis on streams. |
stop-analyzing |
Stop AI analysis on streams. |
get-zone-statuses |
Show live zone statuses, detections, and alarms. |
process-image |
Run the server's capsules on an image file. |
capsule-control |
List, load, enable, disable, unload, and configure capsules. |
zone-control |
List, add, delete, save, and load zones. |
alarm-control |
List, add, delete, save, and load alarms. |
identity-control |
List, add, and delete identities. |
license-control |
Show or set the server license. |
user-control |
Sign in a user of a BrainFrame cloud deployment. |
save-settings |
Save the server's configuration to a file. |
load-settings |
Restore a saved configuration to a server. |
Common Options
Most commands accept these options:
| Option | Description |
|---|---|
--server-url SERVER_URL |
The address of the BrainFrame server. Default: http://localhost. |
--stream-url STREAM_URL |
Act on one stream, identified by its URL. For a video file, use its storage ID. |
--stream-urls STREAM_URLS |
Act on the streams listed in a file. Default: stream-urls.csv. |
If the server is not on the machine where you run the command, set --server-url, for example
--server-url http://192.168.1.50.
Warning
Commands that take a stream list read stream-urls.csv from the current directory when it exists, and act on
those streams. If the file does not exist and you give no --stream-url, some commands act on all streams
on the server. This is how delete-stream deletes every stream. Check which directory you are in before you
run it.
The Stream List File
The stream list is a CSV file with one stream per line. This is the same format as the config.csv file written by
brainframe-onvif-tools, so you can pass that file with --stream-urls config.csv.
- Only lines that contain an
rtsp://URL are used. Blank lines and lines starting with#or<are ignored. - The first value that starts with
rtsp://is the stream URL. - The value after the URL is the stream name. If it is empty, the URL is used as the name.
- The value after the name is optional stream options as JSON, for example a custom pipeline.
- The word
localhostin a line is replaced with this machine's IP address.
rtsp://admin:PASSWORD@192.168.1.10:554/stream1,Front Door
rtsp://admin:PASSWORD@192.168.1.11:554/stream1,Back Door
Managing Streams
add-stream
Adds streams to BrainFrame. Choose one source:
# Add every stream in a list file
brainframe-apps add-stream --stream-urls config.csv

# Add one IP camera
brainframe-apps add-stream --stream-url rtsp://admin:PASSWORD@192.168.1.10:554/stream1 --stream-name "Front Door"

# Upload a video file from this machine and add it as a stream
brainframe-apps add-stream --video-file video.mp4
| Option | Description |
|---|---|
--stream-urls STREAM_URLS |
A file listing the streams to add. Default: stream-urls.csv. |
--stream-url STREAM_URL |
The URL of one stream to add. |
--stream-name STREAM_NAME |
The name of the stream added with --stream-url. Default: the URL. |
--video-file VIDEO_FILE |
A video file to upload and add. |
delete-stream
Deletes streams from the server.
# Delete one stream
brainframe-apps delete-stream --stream-url rtsp://admin:PASSWORD@192.168.1.10:554/stream1

# Delete the streams in a list file
brainframe-apps delete-stream --stream-urls config.csv
Warning
If no stream list file exists in the current directory and you do not give --stream-url, delete-stream
deletes all streams on the server.
list-stream
Lists the streams on the server.
brainframe-apps list-stream
brainframe-apps list-stream --show-capsules
| Option | Description |
|---|---|
--show-capsules |
Also show each stream's capsules. |
start-analyzing and stop-analyzing
Start or stop AI analysis on streams. With no stream specified, they act on the streams in stream-urls.csv if the
file exists, and otherwise on all streams.
brainframe-apps start-analyzing
brainframe-apps stop-analyzing
brainframe-apps start-analyzing --stream-url rtsp://admin:PASSWORD@192.168.1.10:554/stream1
| Option | Description |
|---|---|
--keyframe-only |
Analyze only keyframes of the stream. |
Reading Results
get-zone-statuses
Shows live zone status from the server. For each stream it reports the detections in each zone, entering and exiting objects, and alarm activity.
brainframe-apps get-zone-statuses
brainframe-apps get-zone-statuses --stream-id 3 --detection person --zone Screen
| Option | Description |
|---|---|
--stream-id STREAM_ID |
Show only this stream. |
--detection DETECTION |
Show only these detection classes, as a comma-separated list, for example person,chair. |
--zone ZONE |
Show only these zones, as a comma-separated list, for example Screen,LINE_DESK. Default: all zones. |
--alarm ALARM |
Show only these alarms, as a comma-separated list. |
--n-samples N_SAMPLES |
The number of recent samples to keep. Default: 100. |
--alert-totals-interval SECONDS |
How often to refresh each zone's total alert count. Default: 10. |
--time |
Include the time and timestamp columns in each line. |
--capture-events FILE |
Write zone status records that contain entering, exiting, or alert activity to this file, for diagnosis. |
--capture-limit CAPTURE_LIMIT |
With --capture-events, stop after this many records. Default: 20. |
process-image
Runs the capsules enabled on the server on a PNG image, and draws the detections on the image. It uses the capsule configuration of one stream when you specify it, and otherwise the server's global capsule configuration.
brainframe-apps process-image --image-path frame.png
brainframe-apps process-image --image-path frame.png --stream-id 3
| Option | Description |
|---|---|
--image-path IMAGE_PATH |
The PNG image to process. Required. |
--stream-id STREAM_ID |
Use the capsules enabled on this stream. |
--stream-url STREAM_URL |
Use the capsules enabled on the stream with this URL. |
The annotated image is saved next to the original, with _detections added to the name. For example, frame.png
produces frame_detections.png. The command also opens the image in a window, so it needs a graphical display. Press
q in the window to exit.
Configuring the Server
capsule-control
Manages the capsules on the server.
# List streams and their capsules
brainframe-apps capsule-control --cmd list

# Upload and load a capsule file from this machine
brainframe-apps capsule-control --cmd load --capsule-filename my_capsule.cap

# Enable or disable a capsule, on the whole server or on one stream
brainframe-apps capsule-control --cmd enable --capsule-name detector_person
brainframe-apps capsule-control --cmd disable --capsule-name detector_person --stream-id 3

# Set capsule options, as JSON. The option names depend on the capsule.
brainframe-apps capsule-control --cmd configure --capsule-name detector_person --options '{"OPTION_NAME": VALUE}'
| Option | Description |
|---|---|
--cmd CMD |
One of list, load, unload, enable, disable, or configure. Default: list. |
--capsule-name CAPSULE_NAME |
The capsule to act on. For enable, disable, and unload, omitting it applies the command to all capsules. |
--capsule-filename CAPSULE_FILENAME |
The capsule file to load. Used with load. |
--options OPTIONS |
The capsule options as a JSON string. Used with configure. |
--stream-id STREAM_ID |
Apply the command to this stream only. Otherwise it applies globally. |
zone-control
Manages zones and lines on streams. Identify the stream with --stream-id, --stream-name, or --stream-url.
The zone definition for add is a JSON object. coords is a list of [x, y] pixel positions in the stream's frame.
A line has two points, and a zone can have three or more. Set alarms to an empty list and id to null. Add
alarms afterwards with alarm-control.
brainframe-apps zone-control --cmd list
brainframe-apps zone-control --cmd add --stream-id 3 --zone-name ZONE-Door \
    --options '{"coords": [[0, 0], [640, 0], [640, 720], [0, 720]], "alarms": [], "id": null}'
brainframe-apps zone-control --cmd delete --stream-id 3 --zone-name ZONE-Door

# Save all zones to a file, and restore them later
brainframe-apps zone-control --cmd save --file zones.json
brainframe-apps zone-control --cmd load --file zones.json
| Option | Description |
|---|---|
--cmd CMD |
One of list, add, delete, save, or load. Default: list. |
--stream-id, --stream-name, --stream-url |
The stream to act on. |
--zone-name ZONE_NAME |
The name of the zone to add or delete. |
--options OPTIONS |
The zone definition as a JSON string. Required for add. It must contain coords, alarms, and id. |
--file FILE |
The file to save to or load from. Default: zones.json. |
alarm-control
Manages the alarms of zones. Alarms belong to a zone, so identify both the stream and the zone.
In the example below, the alarm triggers when more than zero people are in the zone for at least half of a 5-second
window. test can be >, <, =, or !=. intersection_point is the point of each detection that must be inside
the zone: bottom, top, left, right, or center. To copy an existing alarm, save the alarms to a file and look
at its contents.
brainframe-apps alarm-control --cmd list
brainframe-apps alarm-control --cmd add --stream-id 3 --zone-name ZONE-Door --alarm-name ALRM-person \
    --options '{"count_conditions": [{"test": ">", "check_value": 0, "with_class_name": "person", "with_attribute": null, "window_duration": 5.0, "window_threshold": 0.5, "intersection_point": "bottom", "id": null}], "rate_conditions": [], "use_active_time": false, "active_start_time": "00:00:00", "active_end_time": "23:59:59", "id": null}'
brainframe-apps alarm-control --cmd delete --stream-id 3 --zone-name ZONE-Door --alarm-name ALRM-person

# Save all alarms to a file, and restore them later
brainframe-apps alarm-control --cmd save --file alarms.json
brainframe-apps alarm-control --cmd load --file alarms.json
| Option | Description |
|---|---|
--cmd CMD |
One of list, add, delete, save, or load. Default: list. |
--stream-id, --stream-name, --stream-url |
The stream to act on. |
--zone-name ZONE_NAME |
The zone that holds the alarm. |
--alarm-name ALARM_NAME |
The name of the alarm to add or delete. |
--options OPTIONS |
The alarm definition as a JSON string. Required for add. See the example above. |
--file FILE |
The file to save to or load from. Default: alarms.json. |
identity-control
Manages the identities that capsules can recognize.
brainframe-apps identity-control --cmd list
brainframe-apps identity-control --cmd add --image-path face.png --unique-name EMP-001 --nickname "Alex" --class-name person
brainframe-apps identity-control --cmd delete_all
| Option | Description |
|---|---|
--cmd CMD |
One of list, add, or delete_all. Default: list. |
--image-path IMAGE_PATH |
The PNG image of the identity, for add. |
--unique-name UNIQUE_NAME |
The identity's unique name, for add. |
--nickname NICKNAME |
The identity's nickname, for add. |
--class-name CLASS_NAME |
The identity's class, for add. Default: person. |
Warning
identity-control --cmd delete_all deletes every identity on the server.
license-control
Shows the server's license, or installs a license from a file.
# Show the license state and terms
brainframe-apps license-control

# Install a license
brainframe-apps license-control --license-file license.txt
user-control
Signs a user in to a BrainFrame cloud deployment. Use --username and --password for the domain user, or supply
OAuth2 tokens with --access-token and --refresh-token. Use --bfm-https-cert to give the certificate of the
BrainFrame management server.
Backing Up and Restoring
save-settings and load-settings
save-settings writes the server's configuration to a JSON file. load-settings applies a saved file to a server,
so you can back up a server, copy its configuration to another server, or restore it after a reinstall.
brainframe-apps save-settings --setting-file settings.json
brainframe-apps load-settings --setting-file settings.json --stream-urls config.csv
The saved file includes:
- Global capsule options and whether each capsule is active.
- The configuration of each stream.
- The zones and alarms of each stream.
- The capsule options and active state of each stream.
load-settings first restores the global capsule options. It then restores the zones, alarms, and capsule settings
of the streams you name with --stream-url or --stream-urls. A stream is matched by its URL, and it must already
exist on the server, so add the streams with add-stream first. Camera credentials in the URLs are
ignored when matching.
| Option | Description |
|---|---|
--setting-file SETTING_FILE |
The settings file. Required for load-settings. Default for save-settings: settings.json. |
--stream-urls STREAM_URLS |
For load-settings, the file listing the streams to restore. Default: stream-urls.csv. |
--stream-url STREAM_URL |
For load-settings, restore this one stream. |
Note
Capsule files are not part of the settings file. Load the capsules onto the server before you load the settings.
brainframe-sys-tools
brainframe-sys-tools is a set of tools for monitoring a BrainFrame system and diagnosing deployment problems. It
measures inference speed, watches system resources, restarts BrainFrame when it stops responding, collects system
information for support, and opens SSH tunnels for remote access.
The tools are intended to run on the BrainFrame server, or on a machine that can reach it.
Installation
pip install brainframe-sys-tools
Requires Python 3.9 or newer (tested on Python 3.10).
Usage
brainframe-sys-tools <command> [options]
To list the options of a command, run brainframe-sys-tools <command> --help.
Note
Command names are written with hyphens, for example fps-monitor.
Commands
| Command | Purpose |
|---|---|
fps-monitor |
Measure the inference speed of each stream. |
perf-monitor |
Monitor CPU, memory, GPU, storage, and temperatures. |
service-monitor |
Watch BrainFrame and restart it when it stops responding. |
sys-info |
Collect system and BrainFrame information into a file. |
ssh-tunnel |
Open an SSH reverse tunnel to a remote server. |
fps-monitor
Shows the inference output speed, in frames per second (FPS), of each stream. The speed is measured through the BrainFrame REST API, alongside several diagnostic measurements.
brainframe-sys-tools fps-monitor
brainframe-sys-tools fps-monitor --server-url http://192.168.1.50 --duration 60

All time-based measurements (Buf, Age, Dsync, and Drift) are in seconds. They are calculated from the monitor's own history of recent results.
| Measurement | Meaning |
|---|---|
| Buf (local buffer duration) | How much time the monitor's history covers: the time between receiving the newest and the oldest zone status in the buffer. By default the buffer holds 100 samples. Once it is full, it acts as a sliding window, and Buf settles at the number of seconds taken to receive the last 100 frames. |
| Age (data freshness) | How long ago the monitor received the most recent zone status. |
| Dsync (pipeline latency) | The difference between the time the monitor received the latest zone status and the timestamp of its video frame. Dsync is only meaningful if the clocks of the two machines are synchronized. |
| Drift (stream clock drift) | The elapsed frame time minus the elapsed local time since monitoring began. A value that keeps growing more negative shows that stream processing is falling behind real time. |
| Option | Description |
|---|---|
--server-url SERVER_URL |
The BrainFrame server. Default: http://localhost. |
--refresh-interval SECONDS |
How often the display refreshes. Values that are too low can reduce accuracy. Default: 0.5. |
--times-hist-len COUNT |
The number of zone status samples to collect before results are displayed. Default: 100. |
--duration SECONDS |
The time span shown in the speed plot. Default: 30. |
--out OUT |
The file where the FPS history is saved. Default: brainframe_fps_history. |
--no-screen |
Print the results as plain text instead of using the full-screen terminal display. |
--version |
Show the version of the tool. |
The FPS history is appended to the output file, so you can review it later.
perf-monitor
Shows live system resource usage in the terminal.
brainframe-sys-tools perf-monitor
The monitor reports:
- System uptime
- CPU usage and temperature
- Memory usage, and the processes using the most memory
- Storage
- Intel integrated GPU (iGPU) usage
- NVIDIA GPU usage and temperature
- Board and NVMe drive temperatures
Some measurements need extra tools on the machine. If a tool is missing, that measurement is not shown.
| Measurement | Needs |
|---|---|
| NVIDIA GPU usage | nvidia-smi, which is installed with the NVIDIA driver. |
| Temperatures | sensors, from the lm-sensors package. |
| iGPU usage | intel_gpu_top, from the intel-gpu-tools package. It also needs sudo. |
A log file named <timestamp>_perf_monitor.log is written to the current directory, so you can review the history
after the session.
| Option | Description |
|---|---|
--memory |
Always show the top memory-consuming processes. |
service-monitor
Checks that BrainFrame is responding, and restarts it when it is not. This is useful for unattended systems.
brainframe-sys-tools service-monitor --log-path ~/bf-logs --interval 30 --threshold 90 --log-save
At each interval the monitor asks the server for its version and the latest zone statuses. If the server does not
answer within the threshold, the monitor restarts BrainFrame by running brainframe compose down followed by
brainframe compose up -d.
The monitor does not start BrainFrame by itself unless you give --start-now. A stale zone status is reported in the
heartbeat log, but it does not trigger a restart.
| Option | Description |
|---|---|
--server-url SERVER_URL |
The BrainFrame server. Default: http://localhost. |
--interval SECONDS |
How often to check the server. Default: 120. |
--threshold SECONDS |
How long to wait for a response before the server is considered unavailable and restarted. Default: 360. |
--log-path LOG_PATH |
The directory for log files. It must already exist. Default: the current directory. |
--start-now |
Start BrainFrame when the monitor starts. |
--log-save |
Before each restart, also save the BrainFrame logs and the system information. |
--restart-cron CRON |
Also restart BrainFrame on a schedule, written as a five-field cron string. |
The --restart-cron string has five fields: minute, hour, day of month, month, and day of week. An asterisk means
"every". Day of week is numbered from 0 for Monday to 6 for Sunday, following the APScheduler library. For example,
0 0 * * 3 restarts BrainFrame at midnight every Thursday.
The monitor writes these files to the log directory. The timestamp is the time the monitor, or the current monitoring session after a restart, started:
| File | Contents |
|---|---|
<timestamp>_brainframe_heartbeat.log |
Each heartbeat check and each restart. Always written. |
<timestamp>_brainframe.log |
The output of the brainframe compose commands run by the monitor. |
<timestamp>_sys.info |
System information collected before a restart. Written with --log-save. |
The monitor runs in the foreground. Run it in tmux, screen, or a system service if it must keep running after you
log out. The user running the monitor must be able to run brainframe compose commands.
sys-info
Collects information about the machine and the BrainFrame installation, prints it, and saves it to a file. Attach the file when you ask for support.
brainframe-sys-tools sys-info
brainframe-sys-tools sys-info --file my-server.info
| Option | Description |
|---|---|
-f FILE, --file FILE |
The file to save to. Default: sys.info. |
The report includes:
- The current date and time, in local time and UTC, and the uptime
- The Linux distribution, kernel, and C library version
- CPU, memory, and disk information
- NVIDIA driver and GPU details, and Intel GPU devices
- The Docker configuration and running containers
- The BrainFrame installation: its paths,
.env,docker-compose.yml, and loaded capsules - The BrainFrame server's version, license, capsules, and streams, read from the REST API on
localhost - The network address of the machine, and whether it can reach
aotu.ai
Warning
The report contains the contents of BrainFrame's configuration files and the stream configuration, which can include camera URLs and credentials. Review the file before you share it.
ssh-tunnel
Opens an SSH reverse tunnel, so that a remote server can reach a service on this machine. For example, it lets support staff open the BrainFrame web interface of a system that is behind a firewall.
brainframe-sys-tools ssh-tunnel -s ssh.example.com -u ubuntu -r 8088:localhost:80
With this command, a user on ssh.example.com can open localhost:8088 to reach port 80 of this machine. Press
Ctrl+C to close the tunnel.
| Option | Description |
|---|---|
-s SERVER_URL, --server-url SERVER_URL |
The SSH server to connect to. Always set this to your own server. |
-u USER, --user USER |
The user name on the SSH server. Default: ubuntu. |
-p PORT, --port PORT |
The SSH server port. Default: 22. |
-r RULE, --remoteforward RULE |
A forwarding rule, written as remote_port:localhost:local_port. Required. Repeat the option for more rules. |
-i FILE, --identity_file FILE |
The SSH private key file. |
-o OPTION, --option OPTION |
An SSH client option, for example -o ServerAliveInterval=120. Repeat the option for more. By default ExitOnForwardFailure=yes is set. |
Warning
A reverse tunnel gives the remote server access to the forwarded services on this machine. Only forward the ports you need, use a server that you trust, and close the tunnel when you are done.
openvisioncapsule-tools
openvisioncapsule-tools helps VisionCapsule developers package and test capsules, and check which inference
hardware is available on a machine. For how to write a capsule, see the
VisionCapsule documentation.
Installation
pip install openvisioncapsule-tools
This tool is tested on Python 3.9.
Usage
openvisioncapsule-tools <command> [options]
To list the options of a command, run openvisioncapsule-tools <command> --help.
Note
Unlike the other BrainFrame command line tools, the command names of openvisioncapsule-tools are written with
underscores, for example capsule_packaging.
Commands
| Command | Purpose |
|---|---|
capsule_packaging |
Package capsule directories into .cap files, or unpackage a .cap file. |
capsule_inference |
Run a capsule on local images to test it. |
devices |
List the inference hardware and software frameworks on this machine. |
capsule_packaging
Packages capsules for distribution, or unpackages a capsule file to see its contents.
Package capsules
--capsule-dir is a directory that contains one subdirectory for each capsule. Every subdirectory is packaged into a
.cap file in the same location. For example, packaging a directory my_capsules/ that contains
detector_example/ creates my_capsules/detector_example.cap.
openvisioncapsule-tools capsule_packaging --capsule-dir my_capsules/
To encrypt the packaged capsules, add a key. You need the same key to unpackage or load them.
openvisioncapsule-tools capsule_packaging --capsule-dir my_capsules/ --capsule-key YOUR_KEY
Unpackage a capsule
openvisioncapsule-tools capsule_packaging --capsule-file my_capsules/detector_example.cap --capsule-key YOUR_KEY
The capsule is extracted to a directory with the same name as the file, without the .cap extension. Leave out
--capsule-key for a capsule that was packaged without a key.
| Option | Description |
|---|---|
--capsule-dir CAPSULE_DIR |
The directory that contains the capsule directories to package. |
--capsule-file CAPSULE_FILE |
The .cap file to unpackage. |
--capsule-key CAPSULE_KEY |
The encryption key used to package or unpackage. |
Give either --capsule-dir or --capsule-file. If you give neither, the command prints its help.
capsule_inference
Runs a capsule on images on your computer, without a BrainFrame server. Use it to check a capsule while you develop it.
openvisioncapsule-tools capsule_inference --capsule my_capsules/detector_example --images photo.jpg
--capsule can be either an unpackaged capsule directory or a packaged .cap file. If you give a directory, the
tool packages it to a .cap file next to it before it runs.
--images takes one or more image files, or directories. For a directory, the .png, .jpg, and .jpeg files in
it are used.
openvisioncapsule-tools capsule_inference --capsule my_capsules/detector_example --images photo1.jpg photo2.jpg
openvisioncapsule-tools capsule_inference --capsule my_capsules/detector_example --images test_images/
Testing classifiers
A classifier, or other capsule that works on detections found by another capsule, needs an input detection. Use
--detection to give the class name. The whole image is passed to the capsule as a detection of that class.
openvisioncapsule-tools capsule_inference --capsule my_capsules/classifier_example --images face.jpg --detection face
Capsule options
The tool saves the capsule options it used to options.json in the current directory, with the default value for
each option. To test other values, edit the values in this file and run the command again. The file is read on each
run.
Output
For each image, the tool prints the capsule's load time, the available detection class names, the options in use, the processing time, and the results. If a display is available, it also shows the image with the detections drawn on it. Press a key to move to the next image.
| Option | Description |
|---|---|
--capsule CAPSULE |
The capsule directory or .cap file. Required. |
--images IMAGES [IMAGES ...] |
The images, or directories of images, to run. |
--detection DETECTION |
The class name of the input detection, for capsules that need one. |
--options OPTIONS |
The file that holds the capsule options. Default: options.json. |
--capsule-key CAPSULE_KEY |
The key of an encrypted capsule. Use brainframe for capsules signed for BrainFrame. |
devices
Lists the inference hardware and software frameworks that are available on the machine. Use it to find out which accelerators your capsules can use, and to include in support requests.
openvisioncapsule-tools devices
The output includes:
- The CPU model and count, the Python version, the Linux distribution, and the kernel version
- The NVIDIA GPU model, driver, and CUDA version
- The Intel OpenVINO version, the Intel OpenCL driver version, and the OpenVINO devices that were found
- The PyTorch (
torch) version and its GPU devices - The TensorFlow version, and its CPU and GPU devices
- The VisionCapsule (
vcap) version, and the devices and priority order that VisionCapsules use
Ended: Dev Tools
Ended: BrainFrame Applications
Developer Guide ↵
Technical Introduction
Terminology
The BrainFrame documentation uses terms that are common in video analytics but may have different meanings in other fields. We also use a few generic terms to describe specific BrainFrame concepts. If you are new to video analytics or are ever confused by a term, please take a look at this guide.
| Term | Meaning |
|---|---|
| Stream | The live stream that is being fed to the Client or to the Server. A stream is video of some sort, from a video file, webcam, or IP camera. |
| Detection | A machine learning detection consists of a bounding box, represented by coords, and a class_name (e.g., person, car, dog). Additionally, a detection can include classification attributes, formatted as a category:value pair, along with extra key:value pairs stored as extra_data for customization. |
| Zone | A region or a line configured by the user within the frames of a video stream. By default, the server automatically configures the entire frame as a region named screen. |
| Region | A spatial area represented by polygon coords. It can represent a specific physical space, such as a door or an area on the floor. The server automatically counts detections within, entering, or exiting this region. |
| Line | A boundary represented by coords. The server automatically counts detections that cross (entering or exiting) this line, as well as detections currently positioned on (within) it. |
| Alarm | A set of conditions (rate_conditions or count_conditions) that must occur in a stream in order for an alert to be raised. |
| Alert | An instance of a specific Alarm occurring. Alerts have a start_time and an end_time. You can see a log of alerts under the In-Focus view for a stream. Alert can be verified by human input, setting verified_as to true or false. |
| Journaling | Writing analysis results to a SQL database. |
Architecture Diagram

Real-time inference results: Zone Statuses
BrainFrame Applications receive real-time inference results as zone statuses from the GET /api/streams/statuses API. Zone statuses are coalesced and published as a complete state snapshot to all subscribed clients. This happens at a bounded rate (defaults to 20 FPS). The applications receive these continuously via a streaming multipart JSON HTTP response through GET /api/streams/statuses. Some of the useful information contained in zone statuses are:
tstamptotal_entered/total_exited(per object type)zone:name,coordsalarms:name,active_start_time,active_end_timecount_conditionswith_class_name,with_attribute(category,value)test,intersection_point,check_valuewindow_duration,window_threshold
rate_conditionswith_class_name,with_attribute(category,value)test,intersection_point,change,direction(entering,exiting,entering_or_exiting)duration
within,entering,exiting arrays:class_name,coordswith_identity:id,unique_name,nickname,metadatachildrenattributes,extra_datatrack_id
alertsalarm_id,zone_id,stream_idstart_time,end_timeverified_as
Info
Zone status entering and exiting arrays will be empty without tracking. These arrays are independent of the entering, exiting, and entering_or_exiting parameters of an alarm's rate_conditions.direction.
Users can observe object detections inside a zone or crossing a line, and see triggered alerts in real time on the BrainFrame Client video overlay. This includes tracking trajectories, entry and exit directions, and counting the number of detections within a zone. The information displayed on the BrainFrame Client UI maps to the REST API as shown in the following tables:
For Zone:Alarm
| Detection Type | UI Representation | Scope | REST API Endpoint | REST API Field |
|---|---|---|---|---|
| Alerts | Total # of all alarms | Since DB Creation | /api/alerts | Total-Count |
| Alert Trigger | Timer, Highlight Zone | During Active | /api/streams/statuses | alerts, end_time |
| Alert Direction | Highlight Arrow (enter only) | During Active | /api/zone_alarms | rate_condition.direction |
For Zone:Line
| Detection Type | UI Representation | Scope | REST API Endpoint | REST API Field |
|---|---|---|---|---|
| Trigger | Timer, Highlight Zone | Crossing | /api/streams/statuses | entering, exiting or within |
| Direction | Highlight Arrow (enter only) | Crossing | /api/streams/statuses | entering |
| ENTER | Total # Per class_name | Since Bootup | /api/streams/statuses | total_entered |
| EXIT | Total # Per class_name | Since Bootup | /api/streams/statuses | total_exited |
| WITHIN | Total # Per class_name | Current Frame | /api/streams/statuses | len(within) |
For Zone:Region
| Detection Type | UI Representation | Scope | REST API Endpoint | REST API Field |
|---|---|---|---|---|
| Trigger | Timer, Highlight Zone | Current Occupancy | /api/streams/statuses | within |
| Direction | Highlight Arrow (enter only) | Crossing | /api/streams/statuses | entering |
| ENTER | Total # Per class_name | Since Bootup | /api/streams/statuses | total_entered |
| EXIT | Total # Per class_name | Since Bootup | /api/streams/statuses | total_exited |
| WITHIN | Total # Per class_name | Current Frame | /api/streams/statuses | len(within) |
Zone (Line or Region)
Applications can create Zones using Zone Control and Alarm Control, and then receive the detection results via the GET /api/streams/status or GET /api/streams/statuses endpoints.
Detections can be within, entering, or exiting a zone (line or region). Every frame will be analyzed to update the within, entering, and exiting arrays for publishing through the zone statuses REST API.
When the within array contains detections within a Zone:Region, the BrainFrame Client renders the region as "active" (lighting up), and displays the class_name and number of detections next to the boundary of the region whenever the incoming Zone Statuses payload indicates that its within array contains at least one detection.
When tracking is enabled, the entering or exiting arrays may contain detections with directions against a Zone:Line. The BrainFrame Client renders the zone (line only) as "active" (lighting up), and displays the class_name (e.g., person, car, dog), and total_entered/total_exited of the detections under "ENTER" and "EXIT" next to the line whenever the incoming Zone Statuses payload indicates that its entering or exiting array contains at least one detection.
Alarms and Alerts
Applications can set count-based or rate-based alarms for a zone (line or region) via POST /api/zone_alarms endpoint or retrieve via GET /api/zone_alarms endpoint. BrainFrame services continuously evaluate these alarms using internal algorithms. When an alarm is triggered:
-
The alert is published to the REST API in real-time as active (ongoing) or inactive alerts inside the Zone Statuses, and is available through GET /api/streams/statuses endpoint.
-
Alert Lifecycle: When an alarm triggers, the generated Alert object receives a
start_time. Itsend_timeremains null (ongoing) until the condition evaluates toFalse, at which point theend_timeis stamped, and the alert becomes inactive. -
Line Crossings are determined by comparing the bounding box's bottom center (or other intersection_point) from the previous frame to the current frame against the line coordinates. A temporal debounce filter is applied to ensure a single track_id does not trigger multiple crossings if it jitters over the line.
-
The alert is written to the database, and is available for querying through GET /api/alerts.
Here is a comparison of alarms for a zone (line or region):
| API Field / Feature | Line: Count Based | Line: Rate Based (Default) | Region: Count Based (Default) | Region: Rate Based |
|---|---|---|---|---|
| Condition Class | count_conditions |
rate_conditions |
count_conditions |
rate_conditions |
| Depends on tracking | No | Yes | No | No |
active_start_time, active_end_time |
Default to null |
Default to null |
Default to null |
Default to null |
with_class_name |
Target object class | Target object class | Target object class | Target object class |
with_attribute |
category:value |
category:value |
category:value |
category:value |
test against |
>, <, =, != check_value |
>=, <= change |
>, <, =, != check_value |
>=, <= change |
Alarm trigger: intersection_point |
Base point touches or crosses the line based on proximity | Base point crosses the line | Base point falls inside the polygon's boundaries | Base point falls inside the polygon's boundaries |
direction |
- | entering, exiting, entering_or_exiting |
- | entering, exiting, entering_or_exiting |
| Time Evaluation Window | Evaluates the current frame. window_duration, window_threshold are ignored |
Evaluates changes of all frames that occurred over the specified duration: Default to 1.0s, Min 0.05s, Max 30s |
Evaluates all frames that occurred over the specified window_duration: Default to 5s, Max 30s. window_threshold Default to 0.5 |
Evaluates changes of the current frame against all past frames within the specified duration: Default to 1.0s, Min 0.05s, Max 30s |
Info
Line: Rate Based Alarm depends on tracking.
Tracking
Tracking is provided by tracker capsules; for example, the tracker_vehicle_iou capsule is available from the VisionCapsule AI Marketplace. Tracking works through the following stages:
-
Per Frame Match: When a detection occurs, the tracker compares detections between consecutive frames. If there is a match, it initializes a track. When using Intersection Over Union (IOU), a match is determined by the
min_iou_for_iou_matchparameter. -
Tracking Initialization: When a detection match occurs, the tracker creates a tentative track.
-
Tracking Start: After seeing a tentative track for a consecutive number of frames (
min_track_length), the track becomes confirmed. Tracking Start triggers atrack_idto be added to thewithin,entering, orexitingarrays of zone statuses. The BrainFrame Client renders a trajectory on the video frame UI, colored per object type. -
Track Loss: If a detection leaves the frame or is occluded, the tracker increments a "miss" counter. The BrainFrame Client hides the trajectory from the video frame UI.
-
Tracking Removed: If a tracked vehicle is not matched to a detection in subsequent frames, its internal misses counter increments. Once misses exceeds
max_misses, the track is marked as deleted by the tracker. Further down the pipeline, the SceneTracker clears tracking history entirely if no matches occur after a period of time.
Python API
Introduction
The BrainFrame Python API is a wrapper around the REST API to make it easier for Python applications to integrate with BrainFrame. The Python API is completely open source and available on Github. Reference documentation and examples for the Python API can be found on ReadTheDocs.
Applications not written in Python can interact with BrainFrame directly through the REST API.
Installation
The BrainFrame Python API is available on Pip for Python 3.6 onward.
pip3 install brainframe-api
We recommend installing the Python API in a virtualenv to avoid interference with other projects on the same system.
Database Description
Introduction
This document is a guide for those interested in writing queries for BrainFrame's SQL database. Included are examples of common queries and an explanation of each table and their columns. This document is intended for those with a basic understanding of SQL.
BrainFrame hosts Postgres in a container and makes it available to the host machine through the default port, 5432. Use the command below to access it:
brainframe compose exec database psql -U user -d brainframe
Relationship Diagram
The following is a visual of how BrainFrame's various tables relate to each other. This is a useful reference when writing queries that span multiple tables. Click the image to enlarge it.

Example Queries
Below are some queries intended to be used as examples for common tasks. Fields that must be filled in are wrapped in brackets.
Getting the number of detections right now in a zone for a class
This query finds the number of detections that are currently in a zone, filtered by a class. If you want to know how many people are currently in the "Couch Area" zone, for instance, this is the query to use.
SELECT COUNT(*) FROM detection
    JOIN detection_zone_status ON detection.id = detection_zone_status.detection_id
    WHERE detection_zone_status.zone_status_id=(SELECT id FROM zone_status
        WHERE zone_status.zone_id=[your zone_id here]
            ORDER BY zone_status.tstamp DESC LIMIT 1)
    AND detection.class_name=[class_name];
Getting the traffic history of a zone
This query gets cumulative data on how many objects of the given class name have entered and exited the zone. This could be used to build a graph of traffic in the zone.
SELECT total_count.count_enter, total_count.count_exit FROM total_count
    JOIN zone_status ON zone_status.id=total_count.zone_status_id
    WHERE zone_status.zone_id=[your zone_id here]
    AND total_count.class_name=[your class name here];
Getting the last zone that an identity was seen in
This query finds the last zone that an identity was found in.
SELECT * FROM zone
    JOIN zone_status ON zone_status.zone_id = zone.id
    JOIN detection_zone_status ON detection_zone_status.zone_status_id = zone_status.id
    JOIN detection ON detection.id=detection_zone_status.detection_id
    JOIN identity ON identity.id=detection.identity_id
    WHERE identity.unique_name = [your unique name here]
    ORDER BY zone_status.tstamp DESC
    LIMIT 1;
Getting the number of times a zone alarm has been triggered
This query counts the total amount of times a zone alarm has been triggered given its' alarm ID.
SELECT COUNT(*) FROM alert WHERE alert.zone_alarm_id = 1
Get the number of people entering or exiting a specific zone, with timestamps
This will return the rows for the following columns: tstamp, count_enter, count_exit
SELECT zone_status.tstamp, total_count.count_enter, total_count.count_exit
FROM total_count
      LEFT JOIN zone_status ON zone_status.id = total_count.zone_status_id
WHERE zone_status.zone_id =
     (SELECT zone.id FROM zone WHERE zone.name = 'YOUR_ZONE_NAME_HERE')
 AND total_count.class_name = 'person'
ORDER BY zone_status.tstamp;
Get the total number of entering and exiting detections of a specific class for all time for a zone
SELECT total_count.count_enter FROM total_count
    JOIN zone_status ON zone_status.id=total_count.zone_status_id
    WHERE zone_status.zone_id=[your zone id here]
    AND total_count.class_name=[your class name here]
    ORDER BY zone_status.tstamp DESC LIMIT 1;
Tables: For Analysis
zone_status
This is an important table for SQL queries. It holds a point in time for a specific stream. The tstamp and zone_id are the key to finding specific detection in a certain place at a certain time.
| Column | Description |
|---|---|
| id | A unique identifier. |
| zone_id | The zone that this status is for. There is also a zone_id field that is the ID of this zone. |
| tstamp | The Unix timestamp of when this status was recorded. |
detection
An object that has been detected in a video stream.
| Column | Description |
|---|---|
| parent_id | A parent detection, if any. For instance, a face detection might have a parent that is a person detection. |
| class_name | The class name of the detection. it describes what the detection is. Ie, "person", "cat", or "dog" |
| identity_id | The identity that this detection is recognized as, if any. For example, if class_name is "face" and there is a face recognition capsule, and that capsule recognized the detection as someone known, it will be attached with an identity. |
| extra_data_json | This is a json of form {'key': VAL, 'key2': 'VAL'} where the values can be of any json encodable type. It is intended to carry capsule-specific and/or customer-specific information without tying it too closely to the brainframe product. |
| coords_json | A JSON-encoded array of arrays specifying where in the frame the detection is. In the format: [[x1,y1], …] |
| track_id | A nullable UUID string. Detections that have the same track_id refer to the same object according to the tracking algorithm being used. This can be used to find the path of a single object throughout a video stream. If null, then the detection has not been successfully tracked. |
identity
A table for storing a known specific person or object, that other tables can link information about.
| Column | Description |
|---|---|
| id | A unique identifier. |
| unique_name | Some uniquely identifying string of the object, like an employee number or an SSN. |
| nickname | A display name for the identity which may not be unique, like a person’s name. |
| metadata_json | Any additional user-defined information about the identity. |
alert
An alert that tells the user an alarm's condition has been met.
| Column | Description |
|---|---|
| id | A unique identifier. |
| zone_alarm_id | The alarm this alert came from. |
| start_time | The Unix timestamp of when this alarm started. |
| end_time | The Unix timestamp of when this alarm ended. May be null if the alert is still ongoing. |
| verified_as | If True, this alert was verified as legit. If False, the alert was a false alarm. If None, it hasn’t been verified yet. |
total_count
The total number of a certain class of object that has entered or exited a zone at some time. There are zero or more of these per ZoneStatus.
| Column | Description |
|---|---|
| id | A unique identifier. |
| zone_status_id | The zone status that this total count is for. |
| class_name | The name of the class of object that we're keeping count of. |
| count_enter | The amount of objects that have "entered" the zone. |
| count_exit | The amount of objects that have "exited" the zone. |
capsule
A capsule loaded through the REST API.
| Column | Description |
|---|---|
| name | The unique name of the capsule |
| data_storage_id | The data storage row that holds the capsule data |
| source_path | Path to the capsule's source code on the developer machine, or null if no source is available |
Tables: For Configuration Storage
premises
This defines a physical area with an internal local network of some sort. This could be a Mall, an office building, a shop, etc. The idea of a Premises is to keep track of which local network a camera or edge device might be running in, in order to forward results through a gateway to a central cloud server.
| Column | Description |
|---|---|
| id | A unique identifier. |
| name | The human readable name for which this premises this table refers to. |
stream_configuration
This defines a video stream and how BrainFrame should connect to it.
| Column | Description |
|---|---|
| id | A unique identifier. |
| premises_id | Nullable. If not null, it represents the premises for which this camera is streaming from. |
| name | The name of the video stream as it appears to the user on the UI. |
| connection_type | The type of connection being defined. This has to do with whether or not the video comes from a file, webcam, or IP camera. |
| connection_options_json | A JSON object that contains configuration information about how to connect to the stream. |
| runtime_options_json | A JSON object that contains configuration information which changes the runtime behavior of the stream. |
| metadata_json | A JSON object that contains any additional information the user may want associated with this stream. |
global_capsule_configuration
This table is automatically created when BrainFrame loads a capsule that didn’t exist before.
| Column | Description |
|---|---|
| name | The (unique) name of the capsule that this configuration refers to. |
| option_values_json | A json with the option values that this capsule exposes Format: { "option_key": "option_value", "other_option": 0.75 } |
| is_active | The default value for this capsule (on or off). It is overridden by the stream_capsule_configuration if the value is not null. |
stream_capsule_configuration
This table will be created when the a specific stream has options modified for a capsule. The table is intended to ‘patch’ an existing global_capsule_configuration to modify behavior of a capsule for a specific stream.
| Column | Description |
|---|---|
| global_configuration_name | The global_capsule_configuration that this stream_capsule_configuration is patching |
| stream_id | The stream_configuration that this stream_capsule_configuration is modifying capsule options for. |
| option_values_patch_json | A json that can be empty, but also can modify the global capsule configuration by simply having a key: modified_value pair. {} or { "option_key": "modified option value" } |
| is_active | Overrides the global_capsule_configuration is_active value if this value is not null. That means that, if is_active is True on the stream_capsule_configuration, then the global_capsule_configuration is ignored. If is_active is null on the stream_capsule_configuration, then the global_capsule_configuration is used. |
attribute
An Attribute refers to classifications, and are used to describe detections. For example, there may be a category of classification such as "gender". A particular detection might have an attribute with category "gender" and value "male".
| Column | Description |
|---|---|
| category | The category of attribute. ("gender", "car_type", etc). This attribute is a key. |
| value | The value of the attribute. ("male", "prius", etc). This attribute is a key. |
zone
A space in a video stream to look for activity in.
| Column | Description |
|---|---|
| id | A unique identifier |
| name | The name of the zone as it appears to the user. |
| stream_id | The ID of the stream that this zone is for. |
| coords_json | Two or more 2D coordinates defining the shape of the zone in the stream. Defined as a two-dimensional JSON array, or "null" if the zone applies to the entire frame. |
zone_alarm
Defines a set of conditions that, if they take place in a zone, should trigger an alarm to the user.
| Column | Description |
|---|---|
| id | A unique identifier |
| name | The name of the alarm as it appears to the user. |
| use_active_time | If true, then alarms only happen between start_time and end_time. If false, then they can happen at any time. |
| active_start_time | The time to start monitoring the stream at every day. Only used if use_active_time is true. Stored in the format "HH:MM:SS". |
| active_end_time | The time to start monitoring the stream at every day. Only used if use_active_time is true. Stored in the format "HH:MM:SS". |
| zone_id | The zone that this alarm is assigned to watch. There is also a zone_id field that is the ID of this zone. |
zone_alarm_count_condition
A condition that must be met for an alarm to go off. Compares how many of some object is in a zone against a test value.
| Column | Description |
|---|---|
| id | A unique identifier |
| zone_alarm_id | The zone alarm that this condition applies to. |
| test | The test condition, either ">", "<", "=", "!=". |
| check_value | The value to apply the test condition to. |
| with_class_name | The name of the class to count in the zone. |
| attribute_id | An optional attribute that the object must have to be counted. (nullable) |
| window_duration | The size of the sliding window used for this condition. A larger sliding window size may reduce false positives but increase latency. |
| window_threshold | A value between 0.0 and 1.0 that controls what portion of the sliding window results must evaluate to true for the alarm to trigger. |
| intersection_point | The point on the detection to use when calculating if the detection is in the zone. Either "bottom", "top", "left", "right", or "center". |
zone_alarm_rate_condition
A condition that must be met for an alarm to go off. Compares the rate of change in the count of some object against a test value.
| Column | Description |
|---|---|
| id | A unique identifier |
| zone_alarm_id | The zone alarm that this condition applies to. |
| test | The test condition, either '>=' or '<='. |
| duration | The time period with which the change in object count happens, in seconds. |
| change | The change in object count that happens within a period of time. |
| direction | The direction of movement, either 'entering' the zone, 'exiting' the zone, or 'entering_or_exiting'. |
| with_class_name | The name of the class of objects to look for in the zone. |
| attribute_id | An optional attribute that the object must have to be counted. |
| intersection_point | The point on the detection to use when calculating if the detection is in the zone. Either "bottom", "top", "left", "right", or "center". |
encoding
A vector encoding of some data that defines an identity. For example, an encoding for a human face that can be compared to other encodings to identify if it is the same human face.
| Column | Description |
|---|---|
| id | A unique identifier |
| identity_id | The identity that this encoding describes |
| class_name | The name of the class that this encoding is of. |
| vector_json | A JSON-encoded array of values. The amount of values will depend on the class name of the identity this encoding is attached to. |
Tables: For Linking
alert_frame
Links an alert to a data_storage table containing the first frame in the video where this alert happened.
| Column | Description |
|---|---|
| id | A unique identifier |
| alert_id | The alert this frame is for. |
| data_storage_id | The data_storage table that contains the frame. |
zone_status_alert
Links a zone_status to an alert that was in progress at the time of the zone_status.
| Column | Description |
|---|---|
| zone_status_id | The zone_status being linked to. |
| alert_id | The alert being linked to. |
detection_zone_status
Links zone statuses to the detections that happened in them.
| Column | Description |
|---|---|
| detection_id | The linked detection. |
| zone_status_id | The linked zone_status. |
| transition_state | The location of the detection relative to the zone |
detection_attribute
Links detections to the attributes that describe them.
| Column | Description |
|---|---|
| detection_id | The linked detection. |
| attribute_id | The linked attribute. |
encoding_data_storage
Links encodings to the data that was used to create the vector. This tends to be an image.
| Column | Description |
|---|---|
| data_storage_id | The linked data_storage |
| encoding_id | The linked encoding |
Tables: Miscellaneous
data_storage
References some external file found elsewhere.
| Column | Description |
|---|---|
| id | A unique identifier. |
| name | The name of the file, used to find it in storage. |
| hash | A SHA256 hash of the data. |
| mime_type | The mime type of the file being stored. |
user
Contains information on user accounts.
| Column | Description |
|---|---|
| id | A unique identifier. |
| username | The user's unique username. |
| password_hash | The user's password, hashed with argon2. |
| role | The user's role, which controls what permissions they have. |
Tutorials ↵
Tutorials
Introductions
These tutorials are written with the goal of helping developers better understand the architecture of BrainFrame, how to interact with BrainFrame using our APIs, and the required steps to build a capsule.
You can find all the example scripts and resources on our website or the tutorial repository.
Connecting to IP Cameras
Introduction
This tutorial provides tips on how to connect IP cameras to BrainFrame. BrainFrame is expected to work with any IP camera that is compatible with RTSP. To make setup easier, we recommend IP cameras that support ONVIF as well. ONVIF is a complementary standard that allows IP cameras to be automatically discovered on a local network by tools like ONVIF Device Manager, among other things. For more information, see the ONVIF website.
The BrainFrame CLI includes a tool called brainframe-onvif-tools, which is designed for professionals to discover, scan, and validate ONVIF-compatible cameras connected on the local network.
If you are having trouble getting your IP camera connected to BrainFrame, please feel free to contact us on our forum. Please include the make and model of your IP camera, as well as the RTSP URL you are attempting to connect with.
What is RTSP?
RTSP is the most common protocol that IP cameras use to communicate with other applications, like BrainFrame. To connect to an RTSP-compatible IP camera, we need to get its RTSP URL.
RTSP URLs are in the following format:
rtsp://{username}:{password}@{ip address}:{port}/{path}
The values in curly braces represent fields that need to be filled in. A full RTSP URL might look something like this:
rtsp://admin:mypassword@10.0.0.104:553/streams/0
Let's break down each portion of the RTSP URL and discuss how you might find its value for your IP camera.
Username and Password
Most IP cameras require a username and password to prevent unauthorized access. These values can be configured in the IP camera's settings. If you haven't changed these values, your IP camera may be using its default username and password. These defaults can be found in the camera manual or on aggregation websites like security.world.
IP Address
When an IP camera connects to your router, it will be assigned an IP address. An ONVIF discovery tool can discover compatible IP cameras on your network and provide you with their IP addresses. Otherwise, you may find the IP camera on your router's configuration page under its list of connected devices.
Some IP cameras may request a static IP address from the router. If, for whatever reason, that static IP address is unavailable, the IP camera may not successfully connect to your router. Device vendors provide special tools to interact with their IP cameras when in this state, often as a smartphone app or desktop application. Consult your device's manual for details.
Port
Chances are, your IP camera is using the default RTSP port, 554. If that's the
case, you may omit the :{port} section of the RTSP URL.
Path
IP cameras that provide multiple video streams may require you to append a path to the end of the RTSP URL. Even if your IP camera only provides one stream, the manufacturer may require a specific path value anyway.
How to find RTSL URL of a camera
Some aggregation websites like security.world may have RTSP URL information available for your device.
If your IP camera supports ONVIF, the BrainFrame CLI includes a tool called brainframe-onvif-tools, which is designed for professionals to discover, scan, and validate ONVIF-compatible cameras connected on the local network in bulk using Linux. Currently there is no Graphics User Interface provided, so it may not be friendly for everyday users.
There are other ONVIF-compatible tools to discover your device on a local network. These tools allow for easy access to the camera's IP address, port, and path for each stream.
For Windows, ONVIF Device Manager is free software and can be downloaded here.
For Linux, ONVIF Device Tool is a free utility provided by Lingodigit. Download the release corresponding to your distribution here.
Using Your Phone as an IP Camera
If you want to test BrainFrame's IP camera support but don't have a dedicated device available, you can repurpose an Android device using IP Webcam in the Play Store.
To start an IP camera stream, select the "Start server" option. Your device's IP address and port should be displayed near the bottom of the screen. Use those values to fill in this RTSP URL, which can be provided to BrainFrame:
rtsp://{ip address}:{port}/h264_ulaw.sdp
REST API ↵
Getting Started
Introduction
In this tutorial, we will connect video streams to the BrainFrame server. You can find the complete script on our GitHub repository.
Before we start, you should have BrainFrame Server and Client installed on your machine, If you don't have them yet, please follow the setup instructions.
This tutorial will use our Python library that wraps around the BrainFrame REST API. The library makes programming for BrainFrame in Python easier. If you're using Python, We strongly recommend you to use our Python API. Otherwise, you can always follow our REST API documentation to use the REST API directly.
Setup Environment
First, let's install the BrainFrame Python API library and setup the environment. Run the following commands. You can either do this in your virtual environment (recommended) or a root environment.
pip3 install brainframe-api
The Python API is now installed and ready for use.
The following APIs will be used in this tutorial:
api.get_stream_configurations()api.set_stream_configuration(...)api.start_analyzing(stream_id=...)
Check existing streams
Now let's create a new, empty script. The first thing you want to do is to import the Python API library.
from pathlib import Path
from brainframe.api import BrainFrameAPI, bf_codecs
Then, initialize an API instance with the BrainFrame server URL. In this tutorial, we will connect to the BrainFrame server instance running on our local machine.
api = BrainFrameAPI("http://localhost")
The server is now connected, and we can start working with BrainFrame. First, let's see if there are any streams already connected to BrainFrame.
stream_configs = api.get_stream_configurations()
print("Existing streams: ", stream_configs)
If you run the script, and you only have a freshly-installed BrainFrame server, you should see just an empty list. Otherwise, the list of streams you have already connected will appear.
Create a New Stream Codec
Next, we will create a new stream configuration. The API function we will use is
api.set_stream_configuration(...). Looking at the function, it takes just a
stream configuration codec as input. You can check the definition of different
codecs in the Python library documentation.
Currently, we support three types of video sources:
- IP cameras
- Webcams
- Local files
For different types of video source, you need to set the different connection types and connection options. For more information, check this documentation.
IP Camera
For an IP camera, the connection type will be IP_CAMERA. In the
connection_options, a valid url is required.
# Create a new IP camera StreamConfiguration codec
new_ip_camera_stream_config = bf_codecs.StreamConfiguration(
    # The display name on the client/in API responses
    name="IP Camera",
    connection_type=bf_codecs.StreamConfiguration.ConnType.IP_CAMERA,
    connection_options={
        # The url of the IP camera
        "url": "your_ip_camera_url",
    },
    runtime_options={},
    premises_id=None,
)
Webcam
For a Webcam, the connection type is WEBCAM. Note: This must be connected to
the server, not the client. In the connection_options, the device ID of the
webcam is required. On Linux, you can find the device ID using:
ls /dev/ | grep video
After you have the device ID, use it in the codec.
# Create a local file StreamConfiguration codec
new_web_camera_stream_config = bf_codecs.StreamConfiguration(
    # The display name on the client/in API responses
    name="Webcam",
    connection_type=bf_codecs.StreamConfiguration.ConnType.WEBCAM,
    connection_options={
        # The device ID of the web camera
        "device_id": 0,
    },
    runtime_options={},
    premises_id=None,
)
Local File
For a local file, you have to first upload the video file to the BrainFrame
server's database and get a storage ID. The connection type is FILE. In the
connection_options, the storage ID of the file is required.
# Upload the local file to the database and create a storage id
storage_id = api.new_storage(
    data=Path("../videos/shopping_cashier_gone.mp4").read_bytes(),
    mime_type="application/octet-stream"
)
# Create a local file stream configuration codec
new_local_file_stream_config = bf_codecs.StreamConfiguration(
    # The display name on the client side
    name="Local File",
    connection_type=bf_codecs.StreamConfiguration.ConnType.FILE,
    # The storage id of the file
    connection_options={
        "storage_id": storage_id,
    },
    runtime_options={},
    premises_id=None,
)
Create a StreamConfiguration on the Server Side
Once we have the StreamConfiguration codec, we can tell BrainFrame Server to connect to it. In this tutorial, we will use the file-based codec. If you have an IP camera or a Webcam connected to the server, you can try using those as well.
# Tell the server to connect to the stream configuration
new_local_file_stream_config = api.set_stream_configuration(
    new_local_file_stream_config)
Once the server receives the stream configuration, it will connect to it, assign a stream ID to it, and send it back. It is helpful to keep track of the IDs of the streams you have added using the return value.
Finally, don't forget to tell BrainFrame to start analyzing/preforming inference on the stream.
# Start analysis on the stream
api.start_analyzing(new_local_file_stream_config.id)
Now you should be able to see that stream in the BrainFrame client.

Send WeChat Notifications
Introduction
In this tutorial, we will walk you through a simple use case for BrainFrame: getting WeChat Notification when there is no cashier in the checkout area. You can find the complete script on our GitHub repository.
Setup The Environment
In a previous tutorial, we installed the BrainFrame server, client, and Python API libraries. In this tutorial, the API functions we are going to use are:
api.set_stream_configuration(...)api.set_zone(...)api.get_latest_zone_statuses()api.get_zone_status_stream()
We will be using a third-party library called itchat to send
notifications to WeChat. We'll install it using pip:
pip3 install itchat
We will also use one of our publicly available capsules,
detector_people_and_vehicles_fast. You can grab it from our
downloads page.
Before we start, you should have the BrainFrame server and client running, and capsules ready.

Log In to WeChat
As usual, we will begin by importing our dependencies:
from pathlib import Path
import itchat as wechat
from brainframe.api import BrainFrameAPI, bf_codecs
Then, let's log in to our WeChat account and send a test message:
wechat.auto_login()
wechat.send_msg(f"Notifications from BrainFrame have been enabled",
                toUserName="filehelper")
The script will display a QR code, Scan it with your WeChat app and login. Your File Helper will then receive the message.

Create a New Stream from a Local File
First set the BrainFrame URL:
api = BrainFrameAPI("http://localhost")
We will reuse the code snippet introduced in the previous tutorial to create a stream configuration on the BrainFrame server. We're going to use a simulated video file for this demo, but it will work with live video streams as well.
# Upload the local file to the BrainFrame server's database and get its storage
# ID
storage_id = api.new_storage(
    data=Path("../videos/shopping_cashier_gone.mp4").read_bytes(),
    mime_type="application/octet-stream"
)

# Create a StreamConfiguration with the storage ID
new_stream_config = bf_codecs.StreamConfiguration(
    # The display name on the client side
    name="Demo",
    # Specify that we're using a file
    connection_type=bf_codecs.StreamConfiguration.ConnType.FILE,
    connection_options={
        # The storage id of the file
        "storage_id": storage_id,
    },
    runtime_options={},
    premises_id=None,
)

# Send the StreamConfiguration to the server to have it connect
new_stream_config = api.set_stream_configuration(new_stream_config)

# Tell the server to start analysis on the new stream
api.start_analyzing(new_stream_config.id)
You can download the demo video from our tutorial scripts repository. We recorded a video simulating a cashier serving customers.
Create a Zone and Setup an Alarm
In BrainFrame, alarms are associated with zones, and you can configure them through the client or through the API. You can check our documentation on Zones and Alarms for more information.
Using the API, we will create a zone around the check-out counter, and an alarm that will be triggered if no people are in that zone.
# Condition for the Alarm that will trigger when there is <1 person in the zone
# that it is assigned to
no_cashier_alarm_condition = bf_codecs.ZoneAlarmCountCondition(
    test=bf_codecs.CountConditionTestType.LESS_THAN,
    check_value=1,
    with_class_name="person",
    with_attribute=None,
    window_duration=5.0,
    window_threshold=0.5,
    intersection_point=bf_codecs.IntersectionPointType.BOTTOM,
)

# Create the ZoneAlarm. It will be active all day, everyday and will be
# triggered if the detection results satisfy the condition we created. Because
# use_active_time==False, the active end/start times will be ignored.
no_cashier_alarm = bf_codecs.ZoneAlarm(
    name="Missing Cashier!",
    count_conditions=[no_cashier_alarm_condition],
    rate_conditions=[],
    use_active_time=False,
    active_start_time="00:00:00",
    active_end_time="23:59:59",
)

# Create a Zone object with the above alarm
cashier_zone = bf_codecs.Zone(
    name="Cashier",
    stream_id=new_stream_config.id,
    alarms=[no_cashier_alarm],
    coords=[[513, 695], [223, 659], [265, 340], [513, 280], [578, 462]]
)

# Send the Zone to BrainFrame
api.set_zone(cashier_zone)
In the client, you will be able to see the zone there:

Get Zone Status
In BrainFrame, we use the ZoneStatus data structure to represent the inference
results of frames. Let's use it to get ours.
We can use the API to get the latest ZoneStatus objects from BrainFrame.
zone_statuses = api.get_latest_zone_statuses()
print("Zone Statuses: ", zone_statuses)
The above code will print out the latest ZoneStatus objects for each stream
with analysis/inference enabled. Warning: it can be a very long data structure,
depending on how many streams there are and what capsules are loaded.
This is the most direct way to get the most recent inference results from BrainFrame. However, you have to call this function each time you want new results, which is a hassle.
A different API function, get_zone_status_stream() helps alleviate this issue.
Instead of having relying on you polling for ZoneStatus objects, this function
will return an iterable object to you. Each time BrainFrame has a new result
available, it will be pushed to the iterator.
zone_status_iterator = api.get_zone_status_stream()
for zone_statuses in zone_status_iterator:
    print("Zone Statuses: ", zone_statuses)
This script will print the zone statuses as fast as the capsules can process the frames.
Get Alarms and Send Notifications to WeChat
We can iterate through the zone status packets and check if there are any alerts that recently terminated after lasting >5 seconds. If there were, we send a notification. Note that for this example, the alert will only trigger after the cashier returns to the counter, a situation that is not as useful outside of the demo environment. The script will also only send one notification before exiting, to avoid sending too many notifications.
# Iterate through the zone status packets
for zone_status_packet in zone_status_iterator:
    for stream_id, zone_statuses in zone_status_packet.items():
        for zone_name, zone_status in zone_statuses.items():
            for alert in zone_status.alerts:
                # Check if the alert has ended
                if alert.end_time is None:
                    continue

                total_time = alert.end_time - alert.start_time
                # Check if the alert lasted for more than 5 seconds
                if total_time > 5:
                    alarm = api.get_zone_alarm(alert.alarm_id)
                    wechat.send_msg(
                        f"BrainFrame Alert: {alarm.name} \n"
                        f"Duration {total_time}", toUserName="filehelper")

                    # Stop here, for demo purposes
                    exit()
The script will send an alert to your WeChat File Helper if the cashier has been missing for more than 5 seconds. It will then exit the loop.

Logout Your WeChat Account
Finally, before we exit the script, don't forget to log out your WeChat account.
Put the following code above exit().
wechat.logout()
Crawl Image Directory
Introduction
In other tutorials, we demonstrated how to start a video stream and run inference, a common scenario. But sometimes you might want to run inference on images instead of videos. This tutorial will demonstrate how to do that using BrainFrame.
The use case in this tutorial is pretty simple. We want to iterate over all images in a directory to find the ones with cats in them. You can find the complete script and sample images on our GitHub repository.
Setup The Environment
In a previous tutorial, we installed BrainFrame server, client, and Python API libraries. The API functions we are going to use in this tutorial are:
api.get_plugins(...)api.process_image(...)
In this tutorial, we will use one of our publicly available capsules:
detector_people_and_vehicles_fast. You can download it from our
downloads page.
Before we start, you should already have the BrainFrame server and client running, and the capsule downloaded.
Check the Existing Capsules
As usual, let's import the dependencies first:
from pathlib import Path

import cv2

from brainframe.api import BrainFrameAPI
And connect to the server:
api = BrainFrameAPI("http://localhost")
Before we start processing images, we want to check the existing capsules to
verify that detector_people_and_vehicles_fast is loaded:
# Get the names of existing capsules
loaded_capsules = api.get_plugins()
loaded_capsules_names = [capsule.name for capsule in loaded_capsules]

# Print out the capsules names
print(f"Loaded Capsules: {loaded_capsules_names}")
Make sure detector_people_and_vehicles_fast is present.
Loaded Capsules: ['detector_people_and_vehicles_fast']
You can also check the loaded capsules using the client.
Iterate through the Image Directory
With the capsule loaded, we can iterate over all the images in the directory,
and get the inference results for each image. Then we will filter for detections
with class_name == "cat".
# Root directory containing the images.
IMAGE_ARCHIVE = Path("../images")

# Iterate through all images in the directory
for image_path in IMAGE_ARCHIVE.iterdir():
    # Use only PNGs and JPGs
    if image_path.suffix not in [".png", ".jpg"]:
        continue

    # Get the image array
    image_array = cv2.imread(str(image_path))

    # Perform inference on the image and get the results
    detections = api.process_image(
        # Image array
        img_bgr=image_array,
        # The names of capsules to enable while processing the image
        plugin_names=["detector_people_and_vehicles_fast"],
        # The capsule options you want to set. You can check the available
        # capsule options with the client. Or in the code snippet above that
        # printed capsule names, also print the capsule metadata.
        option_vals={
            "detector_people_and_vehicles_fast": {
                # This capsule is able to detect people, vehicles, and animals.
                # In this example we want to filter out detections that are not
                # animals.
                "filter_mode": "only_animals",
                "threshold": 0.9,
            }
        }
    )

    print()
    print(f"Processed image {image_path.name} and got {detections}")

    # Filter the cat detections using the class name
    cat_detections = [detection for detection in detections
                      if detection.class_name == "cat"]

    if len(cat_detections) > 0:
        print(f"This image contains {len(cat_detections)} cat(s)")
Now the script will tell you if there are cats in those images:
Processed image one-person.jpg and got []

Processed image no_people.jpg and got []

Processed image one-person-png.png and got []

Processed image one_cat.jpg and got [Detection(class_name='cat', coords=[[800, 0], [1566, 0], [1566, 850], [800, 850]], children=[], attributes={}, with_identity=None, extra_data={'detection_confidence': 0.9875224233}, track_id=None)]
This image contains 1 cat(s)

Processed image two_people_and_dtag.png and got []

Processed image two_people.jpg and got []
Social Distancing Applications
Introduction
In this tutorial, we will walk through a simple use case that checks if someone is violating social distancing rules.
Please be aware that the goal of this tutorial is to help you get familiar with the usage of BrainFrame's inference capabilities. A real social distancing use case is much more complicated than this script.
In this script, we only have two rules:
- Two
persondetection bounding boxes cannot overlap - The distance between the center of two people detections' bounding boxes must be greater than 500 pixels (by default; this will be configurable).
You can find the complete script on our GitHub repository.
Setup The Environment
The environment setup is similar to the environment we have in the [WeChat Notification][wechat_tutorial] tutorial. You can refer to it to set up the environment.
In this tutorial, the API functions that we are going to use are:
api.set_stream_configuration(...)api.set_zone(...)api.get_zone_status_stream()api.set_plugin_option_vals(...)
Help Function
First, import the dependencies:
import math
from argparse import ArgumentParser
from pathlib import Path

from brainframe.api import BrainFrameAPI, bf_codecs
To make the script more readable, we'll define two helper functions in advance.
The first will check if two bounding boxes are overlapped or not:
# Help function to check if two detections are overlapped
def is_overlapped(det1: bf_codecs.Detection,
                  det2: bf_codecs.Detection) -> bool:
    """
    :param det1: First Detection
    :param det2: Second Detection
    :return: If the two Detections' bboxes are overlapped
    """

    # Sort the x, y in ascending order
    coords1_sorted_x = sorted([c[0] for c in det1.coords])
    coords2_sorted_x = sorted([c[0] for c in det2.coords])
    coords1_sorted_y = sorted([c[1] for c in det1.coords])
    coords2_sorted_y = sorted([c[1] for c in det2.coords])

    # Return False if the rects do not overlap horizontally
    if coords1_sorted_x[0] > coords2_sorted_x[-1] \
            or coords2_sorted_x[0] > coords1_sorted_x[-1]:
        return False

    # Return False if the rects do not overlap vertically
    if coords1_sorted_y[0] > coords2_sorted_y[-1] \
            or coords2_sorted_y[0] > coords1_sorted_y[-1]:
        return False

    # Otherwise, the two rects must overlap
    return True
The second helper function one will calculate the distance between the center of two bounding boxes:
# Helper function to calculate the distance between the center points of two
# detections
def get_distance(det1: bf_codecs.Detection,
                 det2: bf_codecs.Detection) -> float:
    """
    :param det1: First Detection
    :param det2: First Detection
    :return: Distance between the center of the two Detections
    """
    return math.hypot(det1.center[0] - det2.center[0],
                      det1.center[1] - det2.center[1])
Create a New Stream from Local File
First, initialize the API instance and connect to the server.
# Initialize the API
api = BrainFrameAPI("http://localhost")
Then, we want to start a video stream, you can find the sample video on our tutorial repository.
# Upload the local file to the database and get its storage ID
storage_id = api.new_storage(
    data=Path("../videos/social_distancing.mp4").read_bytes(),
    mime_type="application/octet-stream"
)

# Create a Stream Configuration referencing the new storage ID
new_stream_config = bf_codecs.StreamConfiguration(
    # The display name on the client side
    name="Demo",
    # This stream will be from a file
    connection_type=bf_codecs.StreamConfiguration.ConnType.FILE,
    # The storage ID of the file
    connection_options={
        "storage_id": storage_id,
    },
    runtime_options={},
    premises_id=None,
)

# Tell the server to connect to that stream configuration
new_stream_config = api.set_stream_configuration(new_stream_config)
Next, we will configure some capsule options instead of using the default ones we defined earlier to filter out some bad detections.
# Filter out duplicate detections
api.set_plugin_option_vals(
    plugin_name="detector_people_and_vehicles_fast",
    stream_id=new_stream_config.id,
    option_vals={
        # If one bounding box is overlapped >80% with another bounding box, we
        # assume that they are really the same detection and ignore them.
        "max_detection_overlap": 0.8,
        "threshold": 0.9
    }
)
Finally, don't forget to tell BrainFrame to start analyzing/preforming inference on the stream.
# Start analysis on the stream
api.start_analyzing(new_stream_config.id)
Check Social Distancing Rules
Next, similar to the WeChat Notification tutorial, we will get the zone status iterator. Will will iterate through all of its zone statuses, checking against the social distancing rules we defined above.
In the WeChat Notification tutorial, the operations on zone statuses were somewhat complicated, being a nested data structure. In this tutorial, we will reorganize in order to make our calculations here easier.
# Verify that there is at least one connected stream
assert len(api.get_stream_configurations()), \
    "There should be at least one stream already configured!"

# Get the inference stream.
for zone_status_packet in api.get_zone_status_stream():
    # Organize detections results as a dictionary of
    # {stream_id: [Detections]}.
    detections_per_stream = {
        stream_id: zone_status.within
        for stream_id, zone_statuses in zone_status_packet.items()
        for zone_name, zone_status in zone_statuses.items()
        if zone_name == "Screen"
    }

    # Iterate over each stream_id/detections combination
    for stream_id, detections in detections_per_stream.items():
        # Filter out Detections that are not people
        detections = [detection for detection in detections
                      if detection.class_name == "person"]

        # Skip stream frame if there are no person detections
        if len(detections) == 0:
            continue
        # Compare the distance between each detections.
        for i, current_detection in enumerate(detections):
            violating = False
            for j in range(i + 1, len(detections)):
                target_detection = detections[j]
                current_detection: bf_codecs.Detection
                target_detection: bf_codecs.Detection
                # If the bbox representing two people are overlapped, the
                # distance is 0, otherwise it's the distance between the
                # center of these two bbox.
                if is_overlapped(current_detection, target_detection):
                    distance = 0
                else:
                    distance = get_distance(current_detection, target_detection)

                if distance < min_distance:
                    print(f"People are violating the social distancing rules, "
                          f"current distance: {distance}, location: "
                          f"{current_detection.coords}, "
                          f"{target_detection.coords}")
                    violating = True
                    break
            if violating:
                break
Now, whenever people violate our social distancing rules, our script will print the message out, including where are they located in the frame.
People are violating the social distancing rules, current distance: 499.8899878973373, location: [[30, 340], [411, 340], [411, 926], [30, 926]], [[571, 238], [828, 238], [828, 742], [571, 742]]
Ended: REST API
Capsules ↵
Introduction
This tutorial will guide you through the process of downloading one of our freely available OpenVisionCapsule capsules and adding it to BrainFrame. We will be installing our simple face detector capsule that works on all platforms, even those without a GPU.
Downloading the Capsule
On the computer that is hosting the BrainFrame server, navigate to our
downloads page and under Capsules, locate the
Detector Face Fast entry. Click the link to download the capsule.
Adding the Capsule to BrainFrame
In the server's data directory (/var/local/brainframe by default), there
should be a directory called capsules/. If the capsules/ directory does not
exist, create it. Place the capsule file that you just downloaded
(detector_face_fast.cap) within this directory.
Note: If you do not know the location of BrainFrame's data directory, you can get it directly using the BrainFrame CLI.
mv PATH/TO/detector_face_fast.cap $(brainframe info data_path)/capsules/
An alternative is to download the capsule directly to the capsules/ directory
wget -P $(brainframe info data_path)/capsules {DOWNLOAD_URL}
Verifying That the Capsule Works
The capsule should now be ready for use by BrainFrame. Let's open the client and make sure everything is working properly.
Open the BrainFrame client and then open the Global Capsule Configuration
dialog. You should see an entry for the Detector Face Fast capsule, with
configuration options.

Once you load a stream, you will be able to see the inference results on the Streams view.

Creating a Basic Capsule
Introduction
In this tutorial, we will walk you through the creation of a basic capsule. If you get stuck along the way or simply want to view the end-result of the tutorial, you can find the completed capsule on our GitHub repository.
Before we start, we highly recommend you to read the OpenVisionCapsules Documentation. It will give you a bit of background information about capsules.
Set Up Environment
To develop your own capsule, you will need to install vcap and vcap_utils,
which are a set of Python libraries for encapsulating machine learning and computer
vision algorithms for intelligent video analytics. They can be found on Github
here.
pip3 install vcap vcap_utils
You might also want to download a few of our open-source capsules:
git clone https://github.com/aotuai/capsule_zoo.git
Creating a Basic Capsule
In this tutorial, we will create a fake capsule. It isn't going to perform any inference, but instead return some fake values. The purpose of this example is to help you to understand our capsule system better.
Directory structure
First, let's create a folder called detector_bounding_box_fake under the
capsules directory under where your docker-compose file is located. Also create
a meta.py and a capsule.py under this directory. The resulting structure
will look like:
your_working_directory
├── docker-compose.yml
└── capsules
    └── detector_bounding_box_fake
        ├── meta.conf
        └── capsule.py
If everything is correct, BrainFrame automatically packages the directory as a .cap file. Alternatively, VisionCapsules can be packaged using the capsule-packaging command.
For more information about the structure, you can check the documentation here.
Capsule Metadata
The meta.conf file provides basic information about the capsule to BrainFrame
before the rest of the capsule is loaded. In our meta.conf, we are going to
define the version of the OpenVisionCapsules SDK that this capsule will be
compatible with.
[about]
api_compatibility_version = 0.3
This number should be the same as the Major.Minor version from
pip3 show vcap | grep Version
Capsule
In capsule.py, we define a class called Capsule, which will define the
actual behavior of the capsule. The Capsule class provides metadata that
allows BrainFrame to understand the capabilities of the capsule and how it
can be used, and must inherit from BaseCapsule. For more information about
the BaseCapsule class, see the documentation
here.
We'll import the dependencies from vcap first:
from vcap import BaseCapsule, NodeDescription, BaseBackend, DetectionNode
Then we'll define the Capsule class as a sub-class of BaseCapsule.
# Define the Capsule class
class Capsule(BaseCapsule):
    # Metadata of this capsule
    name = "detector_bounding_box_fake"
    description = "A fake detector that outputs a single bounding box"
    version = 1
    # Define the input type. As this is an object detector, and does not require
    # any input from other capsules, the input type will be a NodeDescription
    # with size=NONE
    input_type = NodeDescription(size=NodeDescription.Size.NONE)
    # Define the output type. In this case we are going to return a list of
    # bounding boxes, so the output type will be size=ALL
    output_type = NodeDescription(
        size=NodeDescription.Size.ALL,
        detections=["fake_box"],
    )
    # Define the backend. In this example, we are going to use a fake Backend,
    # defined below
    backend_loader = lambda capsule_files, device: Backend(
        capsule_files=capsule_files, device=device)
    options = {}
Backend
Now let's create a Backend class. The Backend class defines how the
underlying algorithm is initialized and used. For more information about
Backend classes, please refer to the
OpenVisionCapsules Documentation.
# Define the Backend Class
class Backend(BaseBackend):
    # Since this is a fake Backend, we are not going to do any fancy stuff in
    # the constructor.
    def __init__(self, capsule_files, device):
        print("Loading onto device:", device)
        super().__init__()

    # In a real capsule, this function will be performing inference or running
    # algorithms. For this tutorial, we are just going to return a single, fake
    # bounding box.
    def process_frame(self, frame, detection_node: None, options, state):
        return [
            DetectionNode(
                name="fake_box",
                coords=[[10, 10], [100, 10], [100, 100], [10, 100]]
            )
        ]

    # Batch process can be used to improve the performance, we will skip it in
    # this example.
    def batch_predict(self, input_data_list):
        pass

    # This function can be implemented to perform clean-up. We can't skip it
    # for this tutorial
    def close(self) -> None:
        pass
The fake capsule is now complete. If you restart your BrainFrame server, you will be able to see it loaded.

If you load a stream, you will be able to see the inference results.

Creating a TensorFlow Object Detector Capsule
Introduction
In this tutorial, we will walk through how to make a capsule using an existing model trained with the [Tensorflow Object Detection API] [TensorFlow detection model zoo]. You can find the complete capsule on our GitHub repository.
Setup The Environment
See the previous tutorial for information on setting up a development environment.
A TensorFlow Face Detection Capsule
File Structure
As in the previous tutorial, we will begin by creating a new folder called
detector_face, a meta.conf and a capsule.py.
You will also need to put the existing TensorFlow model and the metadata in
the directory. For this tutorial, they will be named detector.pb and
dataset_metadata.json. Download the detector.pb and dataset_metadata.json
from here. Other TensorFlow pre-trained
models can be found in the Tensorflow 1 Object Detection Model Zoo and [Tensorflow 2 Object Detection Model
Zoo]
TensorFlow 2 detection model zoo.
So now the file structure will look like:
your_working_directory
├── docker-compose.yml
└── capsules
    └── detector_face
        ├── meta.conf
        ├── capsule.py
        ├── detector.pb
        └── dataset_metadata.json
Capsule Metadata
Just as in the previous tutorial, put the version information in the
meta.conf:
[about]
api_compatibility_version = 0.3
Capsule
First, import the dependencies:
# Import dependencies
import numpy as np
from typing import Dict

from vcap import (
    BaseCapsule,
    NodeDescription,
    DetectionNode,
    FloatOption,
    DETECTION_NODE_TYPE,
    OPTION_TYPE,
    BaseStreamState,
    rect_to_coords,
)
from vcap_utils import TFObjectDetector
The capsule definition will be a little bit more complicated than the previous
one. In this capsule, we will have the threshold option. In addition, since
we are using a real backend, we will pass in a lambda for backend_loader. We
will talk more about this in the Backend section below.
# Define the Capsule class
class Capsule(BaseCapsule):
    # Metadata of this capsule
    name = "face_detector"
    description = "This is an example of how to wrap a TensorFlow Object " \
                  "Detection API model"
    version = 1

    # Define the input type. Since this is an object detector, and doesn't
    # require any input from other capsules, the input type will be a
    # NodeDescription with size=NONE.
    input_type = NodeDescription(size=NodeDescription.Size.NONE)

    # Define the output type. In this case, as we are going to return a list of
    # bounding boxes, the output type will be size=ALL. The type of detection
    # will be "face", and we will place the detection confidence in extra_data.
    output_type = NodeDescription(
        size=NodeDescription.Size.ALL,
        detections=["face"],
        extra_data=["detection_confidence"]
    )

    # Define the backend_loader
    backend_loader = lambda capsule_files, device: Backend(
        device=device,
        model_bytes=capsule_files["detector.pb"],
        metadata_bytes=capsule_files["dataset_metadata.json"])

    # The options for this capsule. In this example, we will allow the user to
    # set a threshold for the minimum detection confidence. This can be adjusted
    # using the BrainFrame client or through REST API.
    options = {
        "threshold": FloatOption(
            description="Filter out bad detections",
            default=0.5,
            min_val=0.0,
            max_val=1.0,
        )
    }
Backend
Because we are using a TensorFlow model, we are going to use a sub-class of
TFObjectDetector instead of BaseBackend. The TFObjectDetector class will
conveniently do the following for us:
- Load the model bytes into memory
- Perform batch inference
- Close the model and clean up the memory when finished
TFObjectDetector already defines the constructor, batch_process() and
close() methods for us, so we can skip defining them ourselves. We just need
to handle the process_frame() method.
# Define the Backend Class
class Backend(TFObjectDetector):
    def process_frame(self, frame: np.ndarray,
                      detection_node: None,
                      options: Dict[str, OPTION_TYPE],
                      state: BaseStreamState) -> DETECTION_NODE_TYPE:
        """
        :param frame: A numpy array of shape (height, width, 3)
        :param detection_node: None
        :param options: Example: {"threshold": 0.5}. Defined in Capsule class above.
        :param state: (Unused in this capsule)
        :return: A list of detections
        """

        # Send the frame to the BrainFrame backend. This function will return a
        # queue. BrainFrame will batch_process() received frames and populate
        # the queue with the results.
        prediction_output_queue = self.send_to_batch(frame)

        # Wait for predictions
        predictions = prediction_output_queue.get()

        # Iterate through all the predictions received in this frame
        detection_nodes = []
        for prediction in predictions:
            # Filter out detections that is not a face.
            if prediction.name != "face":
                continue
            # Filter out detection with low confidence.
            if prediction.confidence < options["threshold"]:
                continue

            # Create a DetectionNode for the prediction. It will be reused by
            # any other capsules that require a face DetectionNode in their
            # input type. An age classifier capsule would be an example of such
            # a capsule.
            new_detection = DetectionNode(
                name=prediction.name,
                # convert [x1, y1, x2, y2] to [[x1,y1], [x1, y2]...]
                coords=rect_to_coords(prediction.rect),
                extra_data={"detection_confidence": prediction.confidence}
            )
            detection_nodes.append(new_detection)

        return detection_nodes
When you restart BrainFrame, your capsule will be packaged into a .cap file
and initialized. You'll see its information on the BrainFrame client.
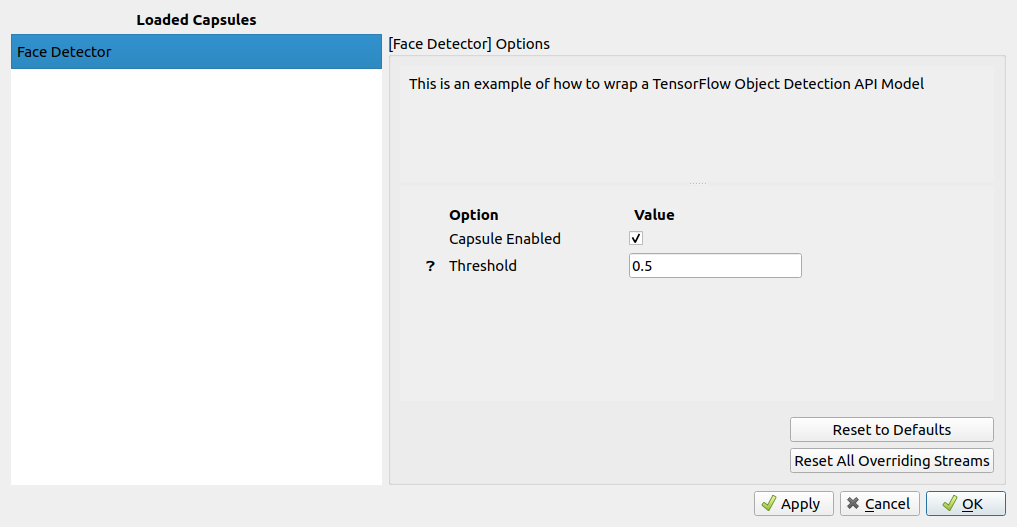
Once you load a stream, you will be able to see the inference results.
Creating an OpenVINO Object Detector Capsule
Introduction
This tutorial will guide you through encapsulating an OpenVINO object detector model. For this tutorial, we will be using the person-vehicle-bike-detection-crossroad-1016 model from the Open Model Zoo, but the concepts shown here will work for all OpenVINO object detectors. You can find the complete capsule on the Capsule Zoo.
See the previous tutorial for information on setting up a development environment.
Getting Started
We will start by creating a directory where all our capsule code and model
files will reside. By convention, capsule names start with a small description
of the role the capsule plays, followed by the kinds of objects they operate
on, and finally some kind of differentiating information about the capsule's
intended use or implementation. We will name this capsule
detector_person_vehicle_bike_openvino and create a directory with that name.
Then, we will add a meta.conf file, which will let the application loading
the capsule know what version of the OpenVisionCapsules API this capsule
requires. OpenVINO support was significantly improved in version 0.2.x, so we
will require at least that minor version of the API:
[about]
api_compatibility_version = 0.3
We will also add the weights and model files into this directory so they can be loaded by the capsule. After these steps, your data directory should look like this:
your_data_directory
├── volumes
└── capsules
    └── detector_person_vehicle_bike_openvino
        ├── person-vehicle-bike-detection-crossroad-1016-fp32.bin
        ├── person-vehicle-bike-detection-crossroad-1016-fp32.xml
        └── meta.conf
The Capsule Class
Next, we will define the Capsule class. This class provides the application
with information about your capsule. The class must be named Capsule and
the file it is defined in must be named capsule.py. We will create that
file in the capsule directory with the following contents:
from vcap import (
    BaseCapsule,
    NodeDescription,
    DeviceMapper,
    common_detector_options
)
from .backend import Backend


class Capsule(BaseCapsule):
    name = "detector_person_vehicle_bike_openvino"
    description = ("OpenVINO person, vehicle, and bike detector. Optimized "
                   "for surveillance camera scenarios.")
    version = 1
    device_mapper = DeviceMapper.map_to_openvino_devices()
    input_type = NodeDescription(size=NodeDescription.Size.NONE)
    output_type = NodeDescription(
       size=NodeDescription.Size.ALL,
       detections=["vehicle", "person", "bike"])
    backend_loader = lambda capsule_files, device: Backend(
        model_xml=capsule_files[
            "person-vehicle-bike-detection-crossroad-1016-fp32.xml"],
        weights_bin=capsule_files[
            "person-vehicle-bike-detection-crossroad-1016-fp32.bin"],
        device_name=device
    )
    options = common_detector_options
In this file, we have defined a Capsule class that subclasses from
BaseCapsule and defines some fields. The name field reflects the name
of the capsule directory and the description field is a short,
human-readable description of the capsule's purpose. The other fields are a bit
more complex, so let's break each one down.
version = 1
This is the capsule's version (not to be confused with the version of the
OpenVisionCapsules API defined in the meta.conf). Since this is the first
version of our capsule, we'll start it at 1. The version field can be used as a
way to distinguish between different revisions of the same capsule. This field
has no semantic meaning to BrainFrame and can be incremented as the capsule
developer sees fit. Some developers may choose to increment it with every
iteration; others only when significant changes have occurred.
device_mapper = DeviceMapper.map_to_openvino_devices()
This device mapper will map our backends to any available OpenVINO-compatible devices, like the Intel Neural Compute Stick 2 or the CPU.
input_type = NodeDescription(size=NodeDescription.Size.NONE)
This detector capsule requires no output from any other capsules in order to run. All it needs is the video frame.
output_type = NodeDescription(
    size=NodeDescription.Size.ALL,
    detections=["vehicle", "person", "bike"])
This detector provides "vehicle", "person", and "bike" detections as output and is expected to detect all vehicles, people, and bikes in the video frame.
backend_loader = lambda capsule_files, device: Backend(
    model_xml=capsule_files[
        "person-vehicle-bike-detection-crossroad-1016-fp32.xml"],
    weights_bin=capsule_files[
        "person-vehicle-bike-detection-crossroad-1016-fp32.bin"],
    device_name=device
)
Here we define a lambda function that creates an instance of a Backend class with the model and weights files, as well as the device this backend will run on. We will define this Backend class in the next section.
options = common_detector_options
We give this capsule some basic options that are common among most detector capsules.
With this new capsule.py file added, your capsule directory should look
like this:
your_data_directory
├── volumes
└── capsules
    └── detector_person_vehicle_bike_openvino
        ├── capsule.py
        ├── person-vehicle-bike-detection-crossroad-1016-fp32.bin
        ├── person-vehicle-bike-detection-crossroad-1016-fp32.xml
        └── meta.conf
The Backend Class
Finally, we will define the Backend class. This class defines how the
capsule runs analysis on video frames. An instance of this class will be
created for every device the capsule runs on. The Backend class doesn't
have to be defined in any specific location, but we will add it to a new file
called backend.py with the following contents:
from typing import Dict

import numpy as np

from vcap import (
   DETECTION_NODE_TYPE,
   OPTION_TYPE,
   BaseStreamState)
from vcap_utils import BaseOpenVINOBackend


class Backend(BaseOpenVINOBackend):
   label_map: Dict[int, str] = {1: "vehicle", 2: "person", 3: "bike"}

   def process_frame(self, frame: np.ndarray,
                     detection_node: DETECTION_NODE_TYPE,
                     options: Dict[str, OPTION_TYPE],
                     state: BaseStreamState) -> DETECTION_NODE_TYPE:
       input_dict, resize = self.prepare_inputs(frame)
       prediction = self.send_to_batch(input_dict).result()
       detections = self.parse_detection_results(
           prediction, resize, self.label_map,
           min_confidence=options["threshold"])
       return detections
Our Backend class subclasses from BaseOpenVINOBackend. This backend
handles loading the model into memory from the given files, implements batching,
and provides utility methods that make writing OpenVINO backends easy. All we
need to do is define the process_frame method. Let's take a look at each
call in the method body.
input_dict, resize = self.prepare_inputs(frame)
This line prepares the given video frame to be fed into the model. The video frame is resized to fit in the model and formatted in the way the model expects. Also provided is a resize object, which contains the necessary information to map the resulting detections to the coordinate system of the originally sized video frame.
This method assumes that your OpenVINO model expects images in the format (num_channels, height, width) and expects the frame to be in a dict with the key being the network's input name. Ensure that your model follows this convention before using this method.
prediction = self.send_to_batch(input_dict).result()
Next, the input data is sent into the model for batch processing. The call to
get causes the backend to block until the result is ready. The results
are objects with raw OpenVINO prediction information.
detections = self.parse_detection_results(
    prediction, resize, self.label_map,
    min_confidence=options["threshold"])
return detections
Finally, the results go through post-processing. Detections with a low confidence are filtered out, raw class IDs are converted to human-readable class names, and the results are scaled up to fit the size of the original video frame.
Wrapping Up
With the meta.conf, Capsule class, Backend class, and model files, the capsule is now complete! Your data directory should look something like this:
your_data_directory
├── volumes
└── capsules
    └── detector_person_vehicle_bike_openvino
        ├── backend.py
        ├── capsule.py
        ├── person-vehicle-bike-detection-crossroad-1016-fp32.bin
        ├── person-vehicle-bike-detection-crossroad-1016-fp32.xml
        └── meta.conf
When you restart BrainFrame, your capsule will be packaged into a .cap file
and initialized. You'll see its information on the BrainFrame client.

Load up a video stream to see detection results.

Creating an OpenVINO Classifier Capsule
Introduction
This tutorial will guide you through encapsulating an OpenVINO classifier model. For this tutorial, we will be using the vehicle-attributes-recognition-barrier-0039 model from the Open Model Zoo, but the concepts shown here apply to all OpenVINO classifiers. You can find the complete capsule on the Capsule Zoo. This model is able to classify the color of a detected vehicle.
This capsule will rely on the detector created in the previous tutorial to find vehicles in the video frame before they can be classified.
Getting Started
Like in the previous tutorial, we will create a new directory for the classifier
capsule. This time we will name it classifier_vehicle_color_openvino. We will
also add a meta.conf with the same contents, declaring that our capsule
relies on version 0.2 or higher of OpenVisionCapsules.
[about]
api_compatibility_version = 0.3
We will also add the weights and model files to this directory so that they can be loaded by the capsule.
The Capsule Class
The Capsule class defined here will be very similar in structure to the one in the detector capsule.
from vcap import BaseCapsule, NodeDescription, DeviceMapper

from .backend import Backend
from . import config


class Capsule(BaseCapsule):
    name = "classifier_vehicle_color_openvino"
    description = "OpenVINO vehicle color classifier."
    version = 1
    device_mapper = DeviceMapper.map_to_openvino_devices()
    input_type = NodeDescription(
        size=NodeDescription.Size.SINGLE,
        detections=["vehicle"])
    output_type = NodeDescription(
        size=NodeDescription.Size.SINGLE,
        detections=["vehicle"],
        attributes={"color": config.colors})
    backend_loader = lambda capsule_files, device: Backend(
        model_xml=capsule_files[
            "vehicle-attributes-recognition-barrier-0039.xml"],
        weights_bin=capsule_files[
            "vehicle-attributes-recognition-barrier-0039.bin"],
        device_name=device
    )
Let's take a look at some of the differences between this Capsule class and the detector's.
input_type = NodeDescription(
    size=NodeDescription.Size.SINGLE,
    detections=["vehicle"])
This capsule takes vehicle detections produced by the detector capsule as input. Each vehicle found in the video frame is processed one at a time.
output_type = NodeDescription(
    size=NodeDescription.Size.SINGLE,
    detections=["vehicle"],
    attributes={"color": config.colors})
This capsule provides a vehicle detection with a color attribute as output. Note
that classifier capsules do not create new detections. Instead, they augment the
detections provided to them by other capsules. We've moved the list of colors
out into a separate config.py file so that it can also be referenced by the
backend, which we will define in the next section.
# config.py
colors = ["white", "gray", "yellow", "red", "green", "blue", "black"]
You may have noticed that this capsule does not have any options. The options
field can be omitted when the capsule doesn't have any parameters that can be
modified at runtime.
The Backend Class
We will once again create a file called backend.py where the Backend class
will be defined. It will still subclass BaseOpenVINOBackend and we will only
need to implement the process_frame method.
from collections import namedtuple
from typing import Dict

import numpy as np

from vcap import (
    Resize,
    DETECTION_NODE_TYPE,
    OPTION_TYPE,
    BaseStreamState)
from vcap_utils import BaseOpenVINOBackend

from . import config


class Backend(BaseOpenVINOBackend):

    def process_frame(self, frame: np.ndarray,
                      detection_node: DETECTION_NODE_TYPE,
                      options: Dict[str, OPTION_TYPE],
                      state: BaseStreamState) -> DETECTION_NODE_TYPE:
        crop = Resize(frame).crop_bbox(detection_node.bbox).frame

        input_dict, _ = self.prepare_inputs(crop)
        prediction = self.send_to_batch(input_dict).result()

        max_color = config.colors[prediction["color"].argmax()]

        detection_node.attributes["color"] = max_color
Let's review this method line-by-line.
crop = Resize(frame).crop_bbox(detection_node.bbox).frame
Capsules always receive the entire video frame, so we need to start by cropping the frame to the detected vehicle.
input_dict, _ = self.prepare_inputs(crop)
We then prepare the cropped video frame to be fed into the model. The video frame is resized to fit into the model and formatted in the way the model expects. We can ignore the second return value, the resize object, because classifiers don't provide any coordinates that need adjusting.
prediction = self.send_to_batch(input_dict).result()
Next, the input data is sent into the model for batch processing. The call to
get causes the backend to block until the result is ready. The results
are objects with raw OpenVINO prediction information.
max_color = config.colors[prediction["color"].argmax()]
We then pull the color information from the prediction, and choose the color
with the highest confidence. We then convert the color from its integer
representation to a human-readable string using the colors list defined in
config.py.
detection_node.attributes["color"] = max_color
Finally, we augment the vehicle detection with the new "color" attribute. This capsule does not need to return anything because no new detections have been created.
Wrapping Up
Finally, the capsule is complete! Your data directory should look something like this:
your_data_directory
├── volumes
└── capsules
    └── classifier_vehicle_color_openvino
        ├── backend.py
        ├── capsule.py
        ├── config.py
        ├── meta.conf
        ├── vehicle-attributes-recognition-barrier-0039.bin
        └── vehicle-attributes-recognition-barrier-0039.xml
When you restart BrainFrame, your capsule will be packaged into a .cap file
and initialized. You'll see its information on the BrainFrame client.
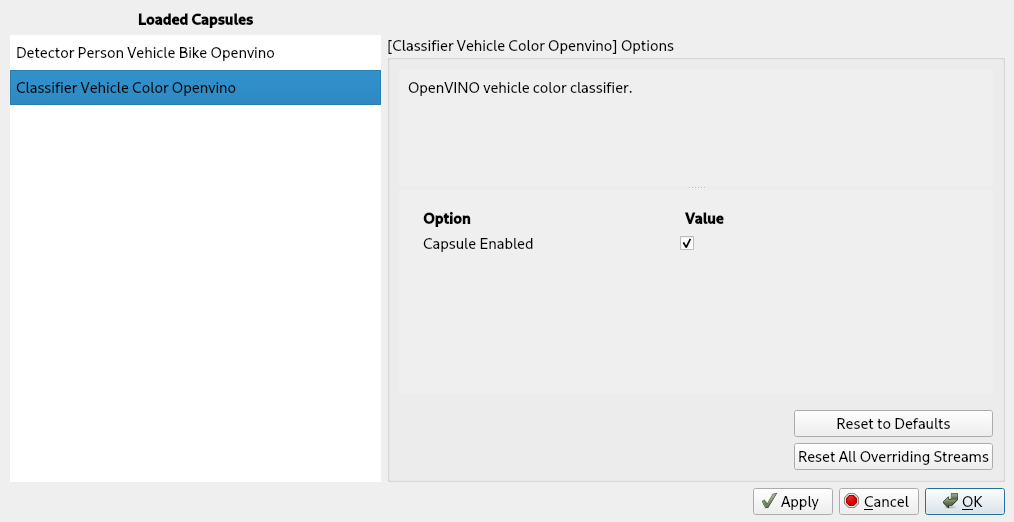
Load up a video stream to see classification results.

Ended: Capsules
Ended: Tutorials
Ended: Developer Guide
BrainFrame® Licensing
The BrainFrame software is Copyrighted. BrainFrame® is a trademarked name.
End-User License Agreement
SDK Licensing
Unless otherwise stated, the following commercial license applies to all other SDK components.
OEM Licensing
Open Source Licenses
Open source licenses for the BrainFrame client can be found under the
legal/licenses directory.
Open source licenses for the BrainFrame server can be found in the core
Docker image under the standard locations provided by the apt and pip
package managers.
Replacing Python Libraries
We offer BrainFrame client users the option to replace some libraries that have been packaged alongside or within the client binary with an API-compatible version of the library. Simply set the environment variable corresponding to the library you want to replace, and BrainFrame will use that version.
For example:
export PYGOBJECT_PATH=/usr/local/pygobject-custom
bash ./brainframe_client.sh
PyGObject
Environment variable: PYGOBJECT_PATH
Source: https://github.com/GNOME/pygobject
Argh
Environment variable: ARGH_PATH
Source: https://github.com/neithere/argh
Chardet
Environment variable: CHARDET_PATH
Source: https://github.com/chardet/chardet
Replacing C++ Libraries
Replaceable libraries are included in the release under the lib directory and
are dynamically linked at runtime. In order to use a custom version of these
dependencies, simply replace the included dynamic library files with your
version.
Please consult the source for their corresponding copyrights. Links to each
library's source code can be found in lib/brainframe_qt/legal/sources.txt
in the binary .zip.